Author: onetwothreeadmin

  • WordPress page caching: when dynamic content breaks static delivery

    WordPress page caching: when dynamic content breaks static delivery

    WordPress page caching: when dynamic content breaks static delivery
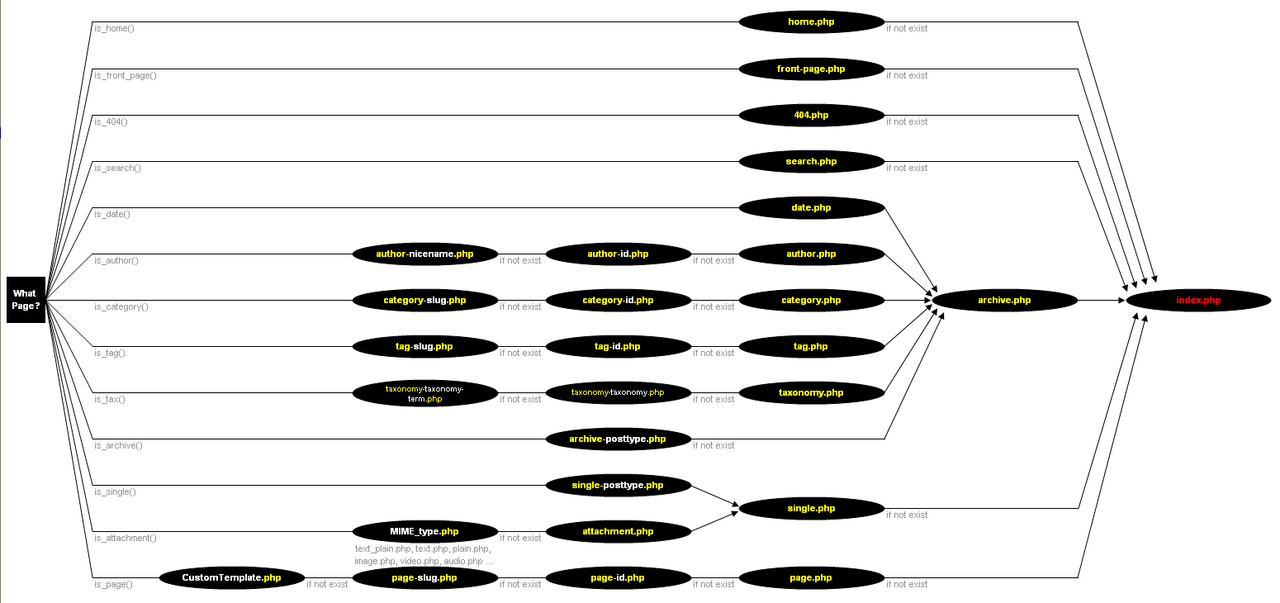
    Photo: Rami via Wikimedia Commons (Public domain)

    Page caching is one of the fastest ways to speed up a WordPress site. Instead of rebuilding every page on every visit, the server delivers a static HTML snapshot. For content-driven sites, it’s a performance multiplier—until it breaks something you didn’t realize was dynamic.

    The promise is simple: cache the page once, serve it to everyone. The problem is that “everyone” includes logged-in users, people in different time zones, and visitors who should see personalized content. When you turn on full-page caching without understanding what gets frozen, you end up serving stale data to the wrong people.

    What page caching actually does

    Most caching plugins—WP Rocket, LiteSpeed Cache, W3 Total Cache—generate a static HTML file the first time someone visits a page. Every subsequent visitor gets that file until it expires or you manually clear the cache. The PHP engine never runs. The database never gets queried. It’s fast because it skips WordPress entirely.

    That works fine for a blog post that doesn’t change. It breaks the moment you add anything that should look different for different visitors: a “Welcome back, [Name]” message, a shopping cart count, a members-only section, a countdown timer, or even a “currently online” widget.

    The static HTML file doesn’t know who’s visiting. It shows the same cached snapshot to everyone—logged in or not, subscriber or guest, New York or Tokyo.

    What breaks first

    The most common casualties are widgets and sidebar elements that rely on server-side state. A “recent comments” block might show the same five comments for hours, even as new ones come in. A “popular posts” widget freezes at whatever was popular when the cache was built. If you’re running ads or affiliate content that rotates server-side, the same banner gets served to everyone until the cache clears.

    Logged-in users see the logged-out version of the page unless you explicitly exclude them from caching. That means no admin bar, no edit links, no personalized menus. If you’re running a membership site or a course platform, this is a deal-breaker. Members land on a page that tells them to log in, even though they already are.

    Checkout pages, account dashboards, and cart views also break under full-page caching. Most plugins auto-exclude /cart/ and /checkout/ paths, but if you’re using a custom URL structure or a non-standard plugin, you need to add exclusions manually.

    How to cache without breaking dynamic content

    The cleanest fix is to separate static and dynamic elements. Cache the page structure—header, footer, main content—and load personalized pieces via JavaScript after the page renders. Most modern membership plugins and ecommerce platforms do this by default: the page loads instantly from cache, then an AJAX call fetches the cart count or user name and injects it into the DOM.

    If you’re building custom features, use the same pattern. Cache the full page, but add a data-user-id attribute to any personalized container and populate it client-side with a lightweight API call. Keep that endpoint uncached—exclude /wp-json/ routes or use a dedicated AJAX handler.

    For logged-in users, most caching plugins offer a “don’t cache for logged-in users” toggle. Enable it if your site has frequent admin activity or if subscribers expect personalized views. The trade-off is that logged-in traffic bypasses the cache entirely, so page speed drops for those visitors. If you have a small team and most traffic is anonymous, this is fine. If half your visitors are logged in, you’re losing most of the performance benefit.

    Time-sensitive content—countdowns, limited offers, live event notices—should either be excluded from caching or rendered client-side. A cached page with a countdown timer will show the same time to everyone until the cache expires, which defeats the urgency. Use JavaScript to calculate the time difference in the browser, or exclude the page from caching and accept the performance hit.

    Testing what actually gets cached

    The easiest way to catch caching issues before they go live: visit your site in an incognito window, clear the cache, reload the page, then log in and reload again. If the logged-in view looks identical to the logged-out view, something’s wrong. Check the page source—if you see on a logged-in page, you need to adjust your exclusion rules.

    Most caching plugins log which pages get cached and which get bypassed. WP Rocket and LiteSpeed Cache both show cache hit/miss stats in their dashboards. If a checkout page shows a cache hit, you know it’s misconfigured.

    For membership sites, test with a subscriber account. Log in, navigate to a members-only page, then open the same URL in a private window. If the private window shows the member content, the page was cached while you were logged in and is now being served to everyone. Add that path to your exclusion list immediately.

    Page caching is worth the setup cost—most WordPress sites see 40–60% faster load times once it’s configured correctly. But if you ship personalized content, ecommerce, or logged-in experiences, the default settings will break something. Test every dynamic element, exclude what needs to stay fresh, and move the rest to client-side rendering.

    Got a caching setup that works for your WordPress site? Reply and let us know which plugin you’re using and how you handle logged-in users—we’ll feature the best setups in a future roundup.
  • Social media APIs throttle embeds differently than timeline requests

    Social media APIs throttle embeds differently than timeline requests

    Social media APIs throttle embeds differently than timeline requests
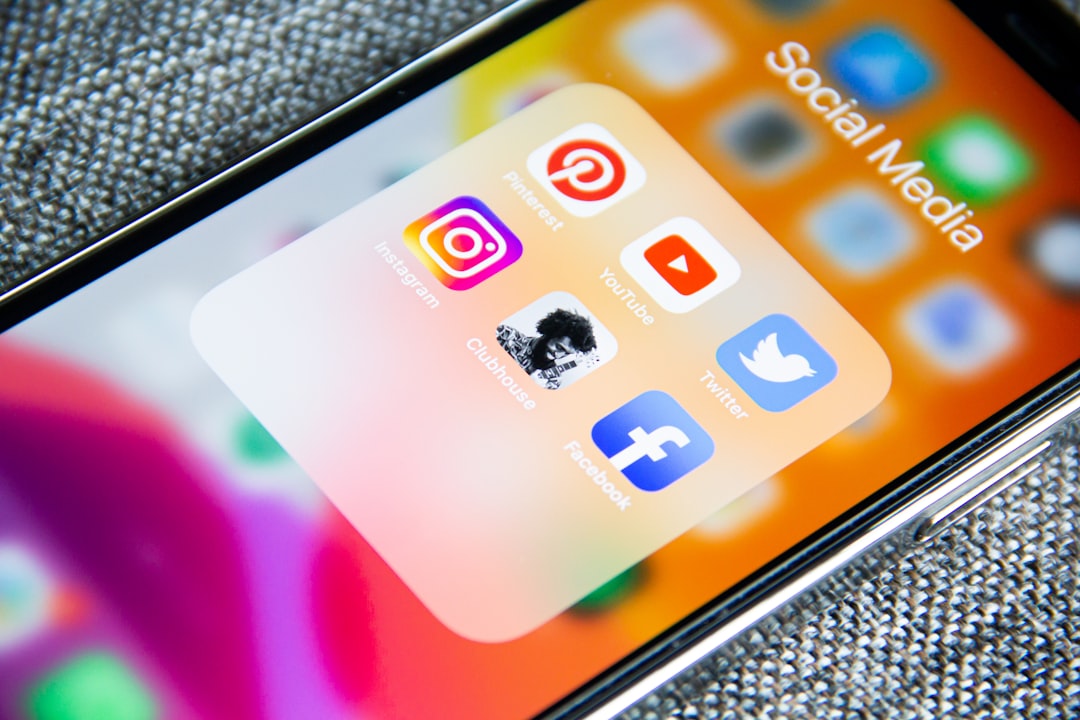
    Photo by Adem AY on Unsplash

    If you’ve ever built a site that pulls in social media content—testimonials from Twitter, Instagram feed widgets, YouTube video metadata—you’ve probably hit a rate limit at some point. What’s less obvious is that most platforms separate their rate limits by endpoint type, and embeds get treated very differently than timeline or profile requests.

    This matters because the failure modes aren’t the same. A timeline request that hits a rate limit usually returns a 429 status and a retry-after header. An embed request might return a cached fallback, a blank card, or—on some platforms—no error at all, just stale data.

    How platforms split rate limits

    Twitter’s API (now X) has separate buckets for /statuses/show (single tweet lookup, used by oEmbed), /statuses/user_timeline, and /search/tweets. If you’re on the free tier in 2026, you get 500 tweet lookups per month and 1,500 timeline requests. Embed a popular tweet on your homepage that gets 10,000 visits a day? You’ll burn through your embed quota in under an hour, but your timeline widget might still work fine.

    Instagram’s API treats embeds through the oEmbed endpoint separately from the Graph API used for pulling your own feed. The oEmbed endpoint is more permissive—no auth required—but it’s also cached aggressively on Instagram’s side. If you’re embedding a post that’s been deleted or made private, you might still see it rendered for hours because Instagram’s CDN hasn’t invalidated the embed yet.

    YouTube separates video metadata requests (used by oEmbed and the Data API) from channel or playlist requests. The Data API has a quota system measured in units, and a single video details request costs 1 unit, while a search costs 100. Embedding a video costs almost nothing; searching for videos to embed costs a lot.

    When embeds fail silently

    The worst case isn’t a 429 error—it’s when the embed keeps working but shows outdated content. Facebook’s oEmbed endpoint caches post data for up to 24 hours. If someone updates a post you’ve embedded, your site won’t reflect it until Facebook’s cache expires. There’s no manual purge option for third-party embeds.

    Twitter’s embed.js script fetches the rendered HTML client-side after page load. If the tweet’s been deleted, you’ll see a blank space or a “this tweet is unavailable” message—but only after the JavaScript loads and tries to hydrate the embed. Server-side rendering won’t catch this; your HTML will still contain the embed markup, and it’ll look fine until the browser tries to fetch the actual content.

    LinkedIn doesn’t offer a public oEmbed API at all anymore. If you’re embedding LinkedIn posts, you’re either using an unofficial scraper (which will break when LinkedIn changes their HTML structure) or you’re embedding a static screenshot. Neither approach respects rate limits because there’s no API to rate-limit in the first place.

    How to design around this

    If you’re embedding social content dynamically—testimonials, recent posts, social proof—build in a fallback that doesn’t depend on the API being available. Cache the embed HTML server-side with a TTL that matches the platform’s cache duration (24 hours for Facebook, 7 days for Twitter). Serve the cached version by default, and refresh it in the background on a slower schedule than your page views.

    For high-traffic pages, pre-render embeds at build time instead of fetching them on every request. If you’re using a static site generator, fetch the oEmbed data during the build step and store the HTML in your repo. You’ll avoid rate limits entirely, though you’ll need to rebuild when you want fresh content.

    If you’re embedding third-party content—user-generated tweets, Instagram posts from customers—don’t rely on real-time embeds. Fetch the content once when the user submits it, store the rendered HTML or a screenshot, and display that. If the original post gets deleted or rate-limited later, your page still works.

    Monitoring rate limit usage

    Most platforms include rate limit headers in their API responses: X-RateLimit-Limit, X-RateLimit-Remaining, and X-RateLimit-Reset. Log these when you make requests, especially for embeds that fire frequently. You’ll see when you’re close to a limit before you hit it.

    Twitter’s API dashboard shows rate limit usage per endpoint, but only if you’re using OAuth. Anonymous oEmbed requests—common for public embeds—don’t show up in your dashboard. You’ll only know you’ve hit the limit when embeds stop loading.

    YouTube’s quota usage appears in the Google Cloud Console under “APIs & Services.” If you’re embedding videos on multiple sites, they all share the same project quota unless you’ve set up separate API keys. One site hitting the limit will throttle all your other sites until the quota resets at midnight Pacific time.

    If you’re running a content site that embeds social posts frequently, set up alerting when your rate limit remaining drops below 20%. That gives you time to switch to cached embeds or disable dynamic loading before your pages start breaking.

    What are you embedding, and how often does it break? Reply and let us know what rate limits you’ve hit—or if you’ve found a workaround that works better than caching.

  • SEO keyword cannibalization: when it happens and how to fix it

    SEO keyword cannibalization: when it happens and how to fix it

    SEO keyword cannibalization: when it happens and how to fix it
    Photo by NisonCo PR and SEO on Unsplash

    You publish a guide on email segmentation in January. It ranks on page two. In March, you write another post about segmentation tactics. Google starts showing the new one instead—but now both hover around position 15–20, and neither breaks page one.

    That’s keyword cannibalization: when multiple pages on your site compete for the same search intent, Google can’t pick a clear winner, and your ranking power gets diluted across both.

    It’s more common than most solo operators realize, especially if you’ve been publishing consistently for a year or more. Here’s how to spot it, decide what to merge or redirect, and execute the fix without tanking your existing traffic.

    How to find cannibalization on your site

    Open Google Search Console. Navigate to Performance, then add a Query filter for a term you know you’ve written about multiple times—something like “email subject lines” or “WordPress caching.”

    Click into the query. Scroll to the Pages tab. If you see two or more URLs getting impressions and clicks for the same keyword, and their average positions are similar (both around position 8–15, for example), that’s a cannibalization signal.

    The clearer test: search Google directly for site:yoursite.com "your keyword". If three or four posts appear, all covering roughly the same angle, you’ve got overlap.

    Not every overlap is a problem. If one page ranks position 3 and another ranks position 47, that’s fine—the lower one isn’t stealing anything. Cannibalization matters when both pages are stuck in the same mid-tier range and neither can break through.

    Merge, redirect, or reposition

    Once you’ve identified cannibalized pages, you have three options.

    Merge and redirect. Take the better-performing URL (higher clicks, better backlinks, or older publish date) and fold the content from the weaker page into it. Update the stronger post with any useful material from the weaker one, then set up a 301 redirect from the weaker URL to the consolidated page. This passes link equity and tells Google there’s now one clear answer.

    Redirect without merging. If one post is clearly superior and the other adds nothing new, just redirect the weaker one. No need to bloat the winner with redundant paragraphs.

    Reposition one page for a different keyword. If both posts have value but target overlapping intent, rewrite one to focus on a distinct angle. For example, split “email segmentation” into “email segmentation for e-commerce” and “behavioral segmentation tactics.” Update titles, H2s, and meta descriptions to clarify the difference. Internal links should reflect the new distinction.

    Most operators default to option three because deleting content feels risky. But in practice, merging and redirecting usually produces faster ranking gains. Google rewards clarity.

    What happens after you redirect

    Rankings don’t update instantly. Expect a 2–4 week lag while Google recrawls the redirected URL, consolidates signals, and re-evaluates the surviving page.

    During that window, you might see both pages drop slightly before the consolidated one climbs. That’s normal. If the merged page hasn’t recovered within 30 days, check that the redirect is live (test it in an incognito browser), that the new page actually covers the topic comprehensively, and that you didn’t accidentally noindex it.

    Track the consolidated page in Search Console. Filter by the target query and watch position and impressions over the next month. If you picked the right survivor and the content is strong, you should see a 5–15 position jump within six weeks.

    When to leave duplicates alone

    Not every topical overlap needs fixing. If you run a newsletter with weekly tips and occasionally touch the same subject in different contexts—say, a how-to guide and a case study—that’s fine. Different content types satisfy different intents.

    Cannibalization is a problem when the search intent is identical and Google sees no reason to prefer one page over the other. If one page is a tutorial and another is a tool comparison, even if they mention the same keyword, they’re not cannibalizing.

    The test: would a searcher clicking one page feel like the other is redundant? If yes, merge. If no, leave them.

    Found cannibalization on your site? Reply with the query and competing URLs—I’ll tell you which one to keep.

  • Newsletter preview text: what gets truncated and when it matters

    Newsletter preview text: what gets truncated and when it matters

    Newsletter preview text: what gets truncated and when it matters
    Photo: Unknown via Wikimedia Commons (Public domain)

    Preview text—the snippet that appears below your subject line in most email clients—gets truncated at wildly different lengths depending on where your subscriber opens it. Gmail on desktop shows roughly 100 characters. Outlook on Windows cuts off around 40. Apple Mail on iPhone displays up to 140 in portrait mode, less in landscape.

    Most newsletter operators write preview text once and assume it renders consistently. It doesn’t. And because preview text directly influences open rates (some studies peg the lift at 8–12% when optimized), understanding how truncation works matters more than you’d expect.

    Where the cuts happen

    Desktop clients are the most forgiving. Gmail shows approximately 100 characters on a typical monitor width. Apple Mail on macOS displays around 90. Outlook 2019 and 2021 on Windows cut hard at 40–50 characters, depending on subject line length—they share a fixed pixel width, so a long subject line eats into preview space.

    Mobile is tighter. Gmail’s mobile app shows 80–90 characters in portrait, less in landscape. Apple Mail on iPhone displays up to 140 characters in portrait but drops to 70–80 in landscape. Outlook mobile sits around 65 characters regardless of orientation.

    The problem: if your key message or call-to-action lives past character 50, roughly 30–40% of your list won’t see it. Outlook desktop users and anyone reading in landscape mode get cut off mid-sentence.

    Frontloading vs. padding

    The common advice is to frontload value—put your hook, offer, or call-to-action in the first 40 characters. That works when you have a single, clear message. “Early access ends Friday” or “Three new case studies inside” fit cleanly.

    But frontloading creates a new problem: preview text that repeats your subject line. If your subject is “Case studies: how three operators doubled revenue” and your preview is “Three new case studies inside,” you’ve wasted 30 characters saying the same thing twice. Subscribers who do see the full preview get redundancy instead of context.

    A better approach: use preview text to extend or qualify the subject line, but assume only the first 40–50 characters will render universally. Structure it so the opening phrase stands alone, and anything past character 50 adds detail for clients that display more.

    Example: Subject line is “Affiliate link cloaking breaks in three places.” Preview text could be “DNS propagation, cache headers, redirect chains—here’s how to test each one.” The first phrase (“DNS propagation, cache headers, redirect chains”) gives context even when truncated. The second half (“here’s how to test each one”) adds value for subscribers on longer-display clients, but the preview still works without it.

    Testing across clients

    Most ESPs show a preview-text field in the send interface, but they don’t simulate truncation accurately. Beehiiv, MailerLite, and ConvertKit all display your full preview text in the editor—you won’t see how it renders on Outlook mobile until you send a test.

    The best workflow: send test emails to multiple addresses on different clients before publishing. At minimum, check Gmail desktop, Apple Mail on iPhone, and Outlook on Windows. If you’re running a paid newsletter or sending to a B2B audience, add Outlook mobile to the rotation—corporate subscribers skew heavily toward Microsoft clients.

    For operators sending daily or multiple times per week, set up a permanent test list with addresses tied to each major client. Send every issue to that list five minutes before the main send. Open each one, screenshot the inbox view, and compare truncation points. It takes three minutes and catches preview-text issues before they hit your full list.

    When preview text doesn’t matter

    Preview text has diminishing returns in three scenarios. First: if your open rates are already above 50%, you’re likely serving a highly engaged list that opens based on sender name and subject line alone. Optimizing preview text might add a percentage point or two, but it’s not your leverage point.

    Second: transactional emails. Password resets, order confirmations, and receipt emails get opened regardless of preview text. If you’re using Postmark or a dedicated transactional service, default preview text (often the first line of body copy) works fine.

    Third: emails where the subject line is self-contained and actionable. “Your invoice is ready” or “You’re confirmed for Friday’s workshop” don’t need preview-text reinforcement. Adding “Click here to download” or “See you at 2pm ET” is redundant.

    Preview text matters most when your subject line raises a question or teases value without fully delivering it. If the subject is “Three underused features in your analytics dashboard,” preview text like “Session replay, funnel drop-off alerts, and cohort comparison—most operators miss all three” gives just enough detail to justify the open.

    Want breakdowns like this in your inbox? Subscribe to One Two Three Send for operator-focused deep dives on the tools and tactics that actually move your online business forward.

    Heads up — some links in this article are affiliate links. If you sign up through them, we may earn a small commission at no extra cost to you. We only recommend tools we use ourselves.

  • Three ways affiliate link cloaking breaks and how to test it

    Three ways affiliate link cloaking breaks and how to test it

    Three ways affiliate link cloaking breaks and how to test it
    Photo by GuerrillaBuzz on Unsplash

    Affiliate link cloaking sounds simple: turn an ugly tracking URL into something clean, track the click, redirect the visitor. But redirects are fragile infrastructure, and most operators don’t test them until someone mentions a broken link in a reply.

    Cloaking breaks in three predictable ways. If you’re running affiliate links through a WordPress plugin, a custom subdomain, or a link-management service, you’ve probably hit at least one of these.

    The plugin update that changes redirect logic

    Most WordPress affiliate plugins—Pretty Links, ThirstyAffiliates, Lasso—handle redirects by intercepting requests at the PHP level. When the plugin updates, redirect logic can shift. A 301 permanent redirect might become a 302 temporary. A direct redirect might add an intermediate JavaScript step for click tracking.

    The symptom: your affiliate dashboard shows zero clicks, but Analytics shows traffic landing on the cloaked URL. The redirect fired, but the tracking layer didn’t log it—or vice versa.

    Test it: after every plugin update, open an incognito window and click one of your cloaked links. Watch the browser’s network tab (right-click > Inspect > Network). You should see a single 301 or 302 response pointing to the affiliate URL, with no intermediate stops. If you see a 200 response or multiple hops, something changed.

    Non-obvious fix: most plugins let you choose redirect type. Set it to 301 unless you’re actively A/B testing destinations. Temporary redirects (302, 307) tell browsers and crawlers not to cache the destination, which means more server load and slower clicks.

    The subdomain DNS record that expires

    Some operators run cloaked links on a subdomain—go.yourdomain.com or link.yourdomain.com—to keep affiliate URLs off the root domain. This requires a DNS A or CNAME record pointing the subdomain to your server.

    If you’re using a CDN or a hosting provider that rotates IP addresses, that DNS record can go stale. The subdomain resolves to an old IP, the redirect doesn’t fire, and the visitor sees a generic server error or a parked-domain page.

    This happens most often after migrating hosts or switching CDN providers. The root domain updates automatically because your registrar’s nameservers handle it. The subdomain doesn’t, because it’s a manual DNS entry you set once and forgot about.

    Test it: run nslookup go.yourdomain.com in your terminal (or use an online DNS lookup tool). Compare the returned IP to your current server’s IP. If they don’t match, update the A record. If you’re behind a CDN like Cloudflare, the CNAME should point to the CDN’s endpoint, not your origin server.

    Non-obvious fix: set a calendar reminder every 90 days to verify subdomain DNS records. Most hosts don’t send alerts when an A record points to a decommissioned IP—they assume you know what you’re doing.

    The browser privacy feature that blocks redirects

    Safari’s Intelligent Tracking Prevention and Firefox’s Enhanced Tracking Protection treat some redirects as tracking attempts and block them silently. If your cloaked link lands on a known affiliate domain (impact.com, shareasale.com, cj.com), the browser may strip tracking parameters or refuse to follow the redirect at all.

    The visitor sees your cloaked URL in the address bar, but the page doesn’t load. No error message. Just a blank screen or a “page took too long to respond” timeout.

    This isn’t theoretical. A reader running Safari 17 or later with default privacy settings will hit this on roughly 15–20% of affiliate networks, depending on how the network structures its tracking URLs.

    Test it: open Safari (or Firefox with Enhanced Tracking Protection set to Strict). Click your cloaked link. If the redirect doesn’t fire within two seconds, the browser blocked it. Check the browser console (Develop > Show JavaScript Console in Safari)—you’ll see a message about “prevented a redirect” or “blocked a tracker.”

    Non-obvious fix: some affiliate networks offer “privacy-friendly” tracking URLs that use first-party cookies instead of third-party parameters. Ask your affiliate manager if they have a Safari-compatible link format. If not, consider disclosing the redirect in your link text (“this link redirects to [Brand]”) so visitors know what to expect if the browser blocks it.

    How to catch breaks before they cost you

    Set up a monthly check: pick five high-traffic affiliate links and test them in Chrome (incognito), Safari (default privacy settings), and Firefox (Strict mode). Log the results in a spreadsheet with the date, the cloaked URL, the destination URL, and whether the redirect fired in each browser.

    If a link breaks, you’ll know which browser triggered it and when. Most breaks happen within 48 hours of a plugin update, a DNS change, or a hosting migration—events you can correlate with the test date.

    One more thing: if you’re using a link-management service like Bitly or Rebrandly for affiliate cloaking, check their status page once a quarter. These platforms occasionally retire redirect infrastructure or change how they handle affiliate domains. They’ll announce it in a changelog you probably don’t read. The first symptom is a spike in 404s on links that worked last week.

    Want more operator tactics like this? Subscribe to One Two Three Send for weekly breakdowns of the tools and workflows that actually matter when you’re running a content business solo.

  • AI assistants forget mid-conversation—here’s what triggers it

    AI assistants forget mid-conversation—here’s what triggers it

    AI assistants forget mid-conversation—here's what triggers it
    Photo by Cody Engel on Unsplash

    You’re three hours into a research session with an AI assistant. You’ve fed it your product brief, customer interview notes, and a draft outline. You ask it to refine the intro based on everything you’ve discussed. It responds with something generic—like it never saw any of your earlier messages.

    You didn’t do anything wrong. The assistant just ran out of memory.

    Context windows have hard limits

    Every AI model has a maximum context window—the total number of tokens (roughly words and punctuation) it can hold in a single conversation. For Claude, that’s 200,000 tokens on the Sonnet and Opus models. For GPT-4o, it’s 128,000. Once you exceed that limit, the model starts dropping the oldest messages to make room for new ones.

    A token isn’t exactly a word. Short words like “it” or “to” are single tokens. Longer words like “conversation” might be two or three. Punctuation, formatting, and code add up faster than you expect. A 1,000-word document is usually around 1,300 tokens. A 10-message back-and-forth with code snippets and formatting can easily hit 5,000.

    If you’re working in a long session—drafting email sequences, debugging workflows, refining a landing page—you can hit the limit without realizing it. The assistant doesn’t warn you. It just starts forgetting.

    What gets dropped first

    Most models use a sliding window. When the conversation exceeds the token limit, the system drops the oldest user and assistant messages first, but keeps the system prompt and the most recent exchanges. That means the assistant remembers what it’s supposed to do (your initial instructions), but not why you made certain decisions earlier in the session.

    This is why an assistant might contradict itself after a long thread. It still knows it’s helping you write a welcome sequence, but it no longer remembers that you explicitly rejected a friendly tone in message twelve.

    Some platforms handle this better than others. Claude‘s Projects feature lets you pin reference material—brand guidelines, product specs, style rules—so it doesn’t count against the per-conversation limit. That buys you more room for the actual back-and-forth. If you’re using the standard chat interface, though, everything counts.

    How to structure prompts so you don’t lose context

    The simplest fix: start a new conversation before you hit the limit. If you’re working on a complex project, break it into discrete sessions. Draft the outline in one chat. Write the first section in another. Edit in a third. Paste the relevant output from the previous session into the new one as reference material.

    It’s more manual, but it forces you to compress and curate what the assistant actually needs to remember. Instead of a 50-message thread where half the exchanges are clarifications and dead ends, you give it a clean summary and move forward.

    If you need to preserve context across a long session, front-load your instructions. Put your brand voice, audience details, and key constraints in the first message. If the model starts forgetting, it’ll drop the middle of the conversation first—your initial setup stays intact longer.

    Another option: export the conversation transcript periodically and save it as a text file. If the assistant loses context, you can paste relevant sections back in as a reminder. It’s not elegant, but it works when you’re deep in a research or drafting session and don’t want to start over.

    When to check token usage

    Most AI platforms don’t surface token counts prominently. Claude’s interface shows approximate usage if you hover over certain UI elements, but it’s not always visible. The OpenAI Playground displays token counts directly; the ChatGPT web interface does not.

    If you’re using the API, you can track tokens in the response metadata. For the web interfaces, assume that any conversation longer than 30 back-and-forth messages is approaching limits—especially if you’re pasting documents, code, or formatted text.

    A rough heuristic: if you’ve scrolled more than three screen heights in a single conversation, consider starting fresh or summarizing.

    The platform doesn’t owe you a warning. Token limits are documented, but the interface won’t stop you from continuing a conversation that’s functionally useless because the model can’t remember the beginning. It’ll keep responding. It just won’t be accurate.

    If you’re running into this regularly, reply and tell us what you’re working on. We’re cataloging the specific workflows where context limits cause the most friction—and which tools handle it best.

    Heads up — some links in this article are affiliate links. If you sign up through them, we may earn a small commission at no extra cost to you. We only recommend tools we use ourselves.

  • Google Analytics 4 session timeout: what 30 minutes actually measures

    Google Analytics 4 session timeout: what 30 minutes actually measures

    Google Analytics 4 session timeout: what 30 minutes actually measures
    Photo: Saleemkce via Wikimedia Commons (CC BY-SA 4.0)

    Google Analytics 4 ends a session after 30 minutes of inactivity by default. Most operators know that number, but fewer understand what the timer actually tracks—or how changing it affects every engagement metric in your dashboard.

    If you’re running a content site, newsletter archive, or documentation hub where readers spend time away from the tab, the standard timeout can fragment what should count as a single visit. Here’s how the mechanism works and when to adjust it.

    How the 30-minute timer starts and resets

    GA4 starts a session the moment someone lands on your site and fires the first pageview or event. The 30-minute countdown begins immediately. Every subsequent interaction—pageview, scroll, click event, video play—resets the timer back to zero.

    If someone reads an article for twelve minutes, opens a new tab to check email for eight minutes, then returns to click a link, GA4 sees continuous activity. The session persists because the gap never hit thirty minutes.

    But if that reader leaves the tab open, walks away for thirty-one minutes, then comes back and scrolls, GA4 registers a new session. Same browser, same tab, different session. That split changes your session count, pages-per-session average, and engagement rate.

    The timer is client-side and local to the browser. It doesn’t sync across devices. If someone starts reading on mobile during a commute and picks up the same article on desktop an hour later, those are always separate sessions—even if they’re logged in.

    When the default timeout distorts your metrics

    Thirty minutes works well for ecommerce and SaaS dashboards where sessions map to discrete tasks: browse products, compare plans, check out. Gaps longer than half an hour usually signal a different intent or context.

    Content sites see different behavior. A reader might open five tabs from your homepage, read each article for eight minutes over the course of an hour, and trigger five separate sessions because the gaps between tab switches exceeded the threshold.

    Documentation sites and tutorial hubs get hit hardest. Readers toggle between your guide and their own project. A thirty-minute threshold treats a single problem-solving session as three or four visits, deflating engagement time and inflating bounce rate.

    If your average GA4 session duration is under two minutes but you publish 10-minute reads, the timeout setting is likely splitting real reading sessions into fragments.

    Adjusting the session timeout in GA4

    You can change the session timeout in GA4’s data stream settings. Navigate to Admin → Data Streams → [your stream] → Configure tag settings → Adjust session timeout. The range is 1 to 120 minutes for inactivity timeout.

    Extending it to 60 or 90 minutes makes sense if your content encourages multi-tasking or requires readers to step away and return. Shortening it to 15 minutes can help if you want tighter attribution windows for fast-moving campaigns or live events.

    Changing the timeout doesn’t backfill historical data. GA4 applies the new setting only to sessions that start after you save the change. If you’re comparing month-over-month engagement metrics and you adjusted the timeout mid-period, your averages will be skewed.

    One non-obvious side effect: increasing session timeout also extends the window for attributing conversions to the original traffic source. If someone arrives from organic search, reads for twenty minutes, leaves for forty, then returns and subscribes, a 30-minute timeout attributes that conversion to direct traffic. A 60-minute timeout keeps the organic attribution intact.

    When not to change it

    If you’re running paid campaigns or affiliate tests and need to compare performance across tools, keep GA4’s timeout at the default. Most ad platforms and attribution tools assume a 30-minute session window. Diverging from that standard makes cross-platform reporting harder to reconcile.

    Similarly, if you’re part of a media network or benchmark group that shares analytics data, non-standard timeout settings make your engagement metrics incomparable. A 90-minute timeout will always show higher pages-per-session than a peer using 30 minutes, even if actual behavior is identical.

    And if your content is truly short-form—tweet threads, quick-hit news briefs, recipe cards—a longer timeout just adds noise. Sessions that stretch across an hour when your median read time is ninety seconds don’t reflect real engagement; they reflect open tabs.

    The default exists for a reason: it works for most sites most of the time. But if your engagement metrics don’t align with how readers actually use your content, the session timeout is one of the first settings worth testing.

    Want more analytics breakdowns like this? Subscribe to One Two Three Send for weekly deep-dives on the tools and settings that shape your business metrics.

  • Productivity automation fail states: three ways workflows break silently

    Productivity automation fail states: three ways workflows break silently

    Productivity automation fail states: three ways workflows break silently
    Photo: Lbeaumont via Wikimedia Commons (CC BY-SA 4.0)

    The worst kind of automation failure is the one you don’t notice for three weeks.

    Your workflow dashboard shows green checkmarks. The logs say “success.” But subscribers aren’t getting added to your CRM, payments aren’t triggering welcome emails, and your analytics are missing half the events they should be tracking.

    Silent failures compound. By the time you notice, you’re reconciling weeks of missing data, apologizing to customers, or discovering that your entire attribution model has been off since you changed one field name in a form.

    Here are the three most common fail states that look like successes—and how to catch them before they cost you.

    The webhook returned 200, but nothing processed

    HTTP status codes lie.

    When Zapier, Make, or n8n sends data to your app via webhook, a 200 OK response just means the server acknowledged receipt. It doesn’t mean the data was validated, stored, or acted on.

    I’ve seen this break two ways:

    • The receiving endpoint changed its required fields. Your automation still sends the old structure. The server responds with 200 but silently drops the payload because it failed internal validation.
    • The webhook hits a rate limit or queue. The server accepts it, returns 200, then discards it when the queue overflows five minutes later.

    The fix: log the full response body, not just the status code. If your automation platform supports it, add a conditional step that checks for a specific success token in the response JSON—something like "status": "processed" or "id": "12345". If that field is missing, trigger an alert.

    For high-stakes workflows—payment confirmations, subscriber imports—set up a daily reconciliation check. Compare your source system’s record count to your destination. If they drift by more than a threshold, you know something’s dropping.

    The trigger fired twice, but your deduplication logic failed

    Most automation platforms have built-in deduplication, but it’s not foolproof.

    If a form submission webhook retries due to a network hiccup, or if two browser tabs both fire the same event within milliseconds, you can end up with duplicate actions: two welcome emails, two Slack notifications, two rows in your spreadsheet.

    The problem gets worse when you’re chaining automations. Zapier fires a Make scenario, which posts to n8n, which updates Airtable. Each handoff is another chance for a retry to slip through.

    What breaks deduplication:

    • Time-based IDs. If your deduplication key is a timestamp rounded to the second, two events in the same second collide.
    • Missing IDs entirely. Some tools don’t pass a unique identifier. You’re deduping on email address or name, which fails when the same person submits twice legitimately.
    • Platform memory windows. Zapier’s deduplication only remembers recent tasks. If someone resubmits after a week, it might not catch it.

    The fix: generate your own unique ID at the source. If you control the form or webhook trigger, append a UUID or nanoid to the payload. Use that as your deduplication key, and store it in a simple key-value store (Redis, a dedicated Airtable table, or even a Google Sheet) with a longer TTL than your platform’s memory window.

    The automation ran, but the data format changed midstream

    This is the sneakiest one.

    You built a workflow six months ago that pulls data from your payment processor, reformats it, and logs it to your analytics dashboard. It’s been running perfectly.

    Then your payment processor updates its API. One field—say, customer_email—gets renamed to email. Or a string that used to be "USD" is now returned as {"currency": "USD", "symbol": "$"}.

    Your automation still runs. It doesn’t throw an error. But every row in your analytics dashboard now has a blank email column, or your currency filter breaks because it’s comparing a string to an object.

    You don’t notice until you run a report and realize your MRR tracking has been off for two months.

    The fix: schema validation as a step. Before your automation writes data anywhere important, add a filter or code step that checks the shape of the incoming payload. If a required field is missing or the wrong type, fail loudly—send yourself a Slack message, log an error, halt the workflow.

    Tools like Zapier’s Code step or Make’s JSON validation module let you write a quick function:

    if (!input.customer_email || typeof input.customer_email !== 'string') { throw new Error('Schema mismatch'); }

    For high-volume workflows, consider a monitoring tool like Sentry or a simple daily cron that samples recent records and flags anomalies.

    When to add redundancy vs. when to simplify

    The instinct when you discover silent failures is to add more checks: redundant logs, backup automations, parallel workflows.

    That works for mission-critical paths—payment confirmations, subscriber onboarding. But for everything else, the better fix is often to reduce the number of handoffs.

    If your workflow chains four tools together, each one is a potential fail point. Can you consolidate two steps into one? Can you pull data directly from the source instead of passing it through an intermediary?

    The fewer transformations, the fewer places for silent corruption.

    Want more breakdowns like this? Subscribe to One Two Three Send for weekly deep-dives on the tools and workflows that actually run online businesses—no fluff, just the mechanics that matter.

  • WordPress REST API authentication: tokens vs. cookies vs. nonces

    WordPress REST API authentication: tokens vs. cookies vs. nonces

    WordPress REST API authentication: tokens vs. cookies vs. nonces
    Photo: Bilal Elmoussaoui and Authenticator contributors via Wikimedia Commons (GPLv3)

    If you’re building custom workflows on top of WordPress—feeding published posts into a social scheduler, syncing custom fields to an external CRM, or triggering email sends when a post goes live—you’re probably using the REST API. And authentication is where most operators hit a wall.

    WordPress offers three main authentication methods for REST API requests: application passwords (tokens), cookie authentication, and nonces. Each behaves differently, and choosing the wrong one means your automation fails silently or exposes your site to unnecessary risk.

    Application passwords: the safe default for external tools

    Application passwords were added to WordPress core in version 5.6. They’re revocable tokens tied to a specific user account, designed for external applications that need programmatic access without exposing your actual login password.

    When you generate an application password from your user profile, WordPress creates a 24-character token. You pass it via HTTP Basic Auth in every API request. If your workflow tool gets compromised or you stop using it, you revoke the token—your main password stays intact.

    This is the right choice for any tool that lives outside WordPress: Zapier workflows, custom Node.js scripts, Python automation, or third-party SaaS that needs to read or write data. The token can’t be used to log into the WordPress admin, only to authenticate API calls.

    Non-obvious gotcha: Application passwords only work over HTTPS. If your staging site uses HTTP, authentication will fail with a vague 401 error. WordPress blocks the feature entirely on non-encrypted connections.

    Cookie authentication: built-in, but brittle for automation

    Cookie authentication is what WordPress uses when you’re logged into the admin and browse the site. Your session cookie proves who you are. The REST API respects that cookie, so any JavaScript running on your own site—inside the WordPress admin or on the front end—can make authenticated requests without extra setup.

    This works fine for plugins or custom admin dashboards. But it’s unreliable for external automation. Cookies expire. They don’t travel well across domains. And if you’re running a headless setup or calling the API from a server, cookies don’t exist.

    Cookie-based requests also require a valid nonce for any write operation (POST, PUT, DELETE). The nonce is a time-limited token WordPress generates to prevent cross-site request forgery. It’s automatically included in admin-area JavaScript via wp_localize_script(), but if you’re building a custom front-end interface, you need to fetch and attach it manually.

    When to use it: Custom admin-area tools, React-based dashboards embedded in WordPress, or AJAX requests from logged-in users on the front end. Not for cron jobs, external services, or anything that runs without an active browser session.

    Nonces: not authentication, just anti-forgery

    Nonces are often confused with authentication, but they’re not. A nonce proves a request came from your site—not from a malicious third-party form. It doesn’t prove who sent the request; it just checks that the request originated from a legitimate WordPress-generated page.

    Nonces expire after 24 hours by default (technically 12–24 hours depending on when they were generated). If your automation fetches a nonce and then waits two days to use it, the request fails.

    You generate a nonce in PHP with wp_create_nonce('action-name') and validate it with wp_verify_nonce(). The REST API checks nonces automatically when you use cookie authentication, but only for destructive operations. Read-only GET requests don’t need one.

    Common mistake: Hardcoding a nonce into a JavaScript file. It expires, and your AJAX calls start failing silently. Always generate nonces dynamically and pass them to your script at page load.

    Which one to use

    If you’re calling the WordPress REST API from outside WordPress—Zapier, a headless front end, a Python script, a mobile app—use application passwords. Generate one per tool, label it clearly, and revoke it when you’re done.

    If you’re building a feature inside WordPress—a custom admin page, a front-end dashboard for logged-in users—use cookie authentication. WordPress handles the session for you. Just remember to include a nonce for write operations.

    If you’re passing data between WordPress and an external service that you control, consider setting up a custom endpoint with a shared secret instead of relying on user-based authentication. Store the secret in an environment variable, check it in your endpoint logic, and skip the user-permission overhead entirely.

    Most authentication failures in WordPress automations come from mixing these methods or assuming cookies work outside the browser. Pick the method that matches where your code runs, and half your API errors disappear.

    Got a WordPress automation question? Reply to this email—we cover one reader question every Sunday.

  • ConvertKit automation delay settings: how long between steps

    ConvertKit’s visual automation builder lets you add delays between steps—wait 3 days, then send an email; wait 1 hour, then tag the subscriber. But the delay feature doesn’t work the way most operators expect, and misunderstanding it can break onboarding sequences, drip campaigns, and time-sensitive offers.

    How ConvertKit measures delay duration

    When you set a delay of “3 days,” ConvertKit waits exactly 72 hours from the moment the subscriber enters that delay step. It’s not “3 business days” or “3 days at 9 a.m.” It’s a rolling 72-hour timer that starts the instant the previous action completes.

    If someone subscribes at 2:37 p.m. on a Tuesday and your automation includes a 3-day delay before the welcome email, that email sends at 2:37 p.m. on Friday. If you have 200 subscribers enter the automation throughout the day, you’ll have 200 different send times spread across the clock.

    This matters most when you’re running time-sensitive promotions or trying to align emails with specific days of the week. A “launch on Monday” automation that uses a 7-day delay from sign-up will send on different days depending on when people joined.

    Delay minimums and processing lag

    ConvertKit’s shortest delay is 1 hour. You can’t set a 15-minute or 5-minute delay. If you need tighter timing—say, sending a lead magnet immediately followed by a second email 10 minutes later—you’ll need to use two separate broadcasts or handle the second email outside ConvertKit.

    There’s also a processing window. ConvertKit doesn’t guarantee that a 1-hour delay fires at exactly 60 minutes. In practice, most delays resolve within a few minutes of the target time, but during high-traffic periods (big launches, Black Friday campaigns), you might see 5–10 minute lag on short delays. Longer delays (24+ hours) tend to be more precise.

    One operator I spoke with runs a 5-day product launch sequence and noticed emails sometimes landed 8–12 minutes late during a coordinated launch with affiliates. For most content sequences, that’s irrelevant. For a flash sale ending at noon, it’s a problem.

    Stacking delays vs. using date-based rules

    If you want emails to send on specific days regardless of sign-up time, don’t use delay steps alone. ConvertKit’s automation builder includes a “Wait until a specific day/time” condition. You can set a rule like “wait until next Wednesday at 10 a.m.” instead of “wait 3 days.”

    This batches subscribers. Everyone who enters the automation between Wednesday at 10:01 a.m. and the following Tuesday at 11:59 p.m. will receive the next email on Wednesday at 10 a.m. It’s cleaner for weekly digest-style sequences or coordinated launches.

    The tradeoff: if someone subscribes on Tuesday, they wait 8 days instead of 7. If they subscribe on Wednesday at 9 a.m., they wait 7 days minus 1 hour. The timing variance shifts from send time to wait duration.

    I use day-based rules for anything tied to external deadlines (webinar reminders, cart-close emails) and rolling delays for evergreen onboarding where the calendar date doesn’t matter.

    One non-obvious trick: buffer delays before conditional splits

    If your automation includes a conditional split—”if they opened the last email, send A; if not, send B”—add a short delay before the condition checks. ConvertKit needs time to register the open event. If you check immediately after sending, most subscribers won’t have opened yet, and your condition will route everyone to the “didn’t open” branch.

    A 6-hour or 12-hour buffer before checking open/click conditions gives the data time to populate. I’ve seen operators skip this and wonder why 95% of their list is routed to the “low engagement” path when open rates are actually 40%+. The timing was the issue, not the engagement.

    ConvertKit doesn’t surface this in the UI. The delay step just says “wait X hours”—it doesn’t explain why you might need it before a condition. But once you know, it’s an easy fix.

    Want more breakdowns like this? Subscribe to One Two Three Send for weekly deep-dives on the tools that run online businesses.