Author: onetwothreeadmin

  • SEO content briefs overspecify—and kill the writing

    SEO content briefs overspecify—and kill the writing

    SEO content briefs overspecify—and kill the writing
    Photo by ZBRA Marketing on Unsplash

    SEO content briefs have become instruction manuals. Word count: 1,847. Include “best email marketing tools” 7 times. Add 3 H2s, 5 H3s. Link to these 4 internal pages. Use a FAQ schema block.

    The result? Content that reads like it was written by committee—because it was. The brief became the straightjacket.

    I’m arguing that over-specified SEO briefs are now hurting rankings more than helping them. The tighter you constrain the writing, the more it sounds like everyone else targeting the same keyword. And Google’s gotten good at recognizing when something was optimized into mediocrity.

    The brief creep problem

    Five years ago, a content brief might have been a topic, a target keyword, and three competitor URLs to reference. Now they’re multi-page documents with:

    • Exact keyword placement by paragraph
    • Semantic keyword lists pulled from LSI tools
    • Prescribed word counts down to the hundred
    • Mandatory subheading structures
    • Required schema markup types
    • Internal linking maps

    This isn’t research. It’s paint-by-numbers.

    The problem: when you tell a writer exactly what to write and where to write it, you strip out the two things that make content rank in 2026—original insight and natural language patterns that signal expertise.

    A writer following a 47-point checklist isn’t thinking about the reader’s actual question. They’re thinking about the checklist. The content becomes a vehicle for compliance, not communication.

    What Google’s actually rewarding now

    Google’s helpful content updates over the past two years have consistently punished one thing: content that exists to rank rather than to answer.

    The signals it uses aren’t secret anymore. Time on page. Scroll depth. Pogo-sticking back to search results. Whether someone opens a second tab to verify what you said. Whether they link to you when they write about the same topic later.

    None of those signals care whether you hit 1,847 words or 1,650. They care whether the content was useful enough to hold attention.

    Over-specifying a brief optimizes for the wrong metric. You’re not optimizing for usefulness—you’re optimizing for historical correlations that may not apply to your topic, your audience, or the current algorithm.

    I’ve seen this firsthand. A client’s blog post ranked #3 with 890 words and zero keyword optimization. A competitor’s 2,400-word “complete guide” with perfect keyword density sat at #9. The difference? The shorter post answered the question in the first 200 words and backed it with a real example. The longer one buried the answer under six paragraphs of SEO throat-clearing.

    What to brief instead

    Strip your briefs back to three things:

    1. The reader’s actual question. Not the keyword—the question. “How do I migrate from Mailchimp to something cheaper without losing subscribers?” is a better brief anchor than “Mailchimp alternatives.”

    2. What the top 5 results miss. This is your research layer. What question do the current top-rankers leave unanswered? What example do they skip? Where do they get vague? That gap is your angle.

    3. One credibility anchor. A number, a screenshot, a named tool, a specific price point—something concrete that signals you’ve done this, not just read about it.

    That’s it. No word count. No keyword density. No mandatory subheading structure.

    Give the writer room to write the way a human would explain it to another human. Let them frontload the answer. Let them skip the fluff intro. Let them use the keyword twice instead of seven times if that’s what sounds natural.

    The exception: when to spec it tight

    There is a place for detailed briefs: when you’re working with a writer who doesn’t know the subject and won’t do independent research.

    If you’re hiring freelancers at $50 per post who are rewriting competitor content, then yes—you need guardrails. The brief becomes quality control.

    But if you’re writing it yourself, or working with someone who knows the space, the over-specified brief just gets in the way. You’re not managing quality—you’re managing compliance. And compliance doesn’t rank anymore.

    The best-performing posts I’ve published in the past year had three-sentence briefs. The worst-performing ones had the longest checklists. That’s not causation, but it’s a pattern worth noticing.

    If your brief is longer than the outline you’d write freehand before starting a post, it’s too long.

    Want more operator-to-operator takes on what’s working now? Subscribe to One Two Three Send—one article like this every day, no fluff.
  • Getting paid as a solopreneur—here’s what you actually see

    Getting paid as a solopreneur—here’s what you actually see

    Getting paid as a solopreneur—here's what you actually see
    Photo by Alexander Mils on Unsplash

    You sold $5,000 worth of courses last month. Stripe’s dashboard confirms it. Your bank account shows $4,200. The difference isn’t a mystery—it’s just that nobody walks you through the cascade of fees, holds, and timing gaps that sit between a customer’s payment and your actual cash.

    Here’s what actually happens to your money, in order, and what you’ll see at each stage.

    The payment arrives—minus processing fees

    When a customer pays $100, the payment processor takes its cut immediately. Stripe charges 2.9% + $0.30 per transaction for most U.S. cards. That’s $3.20 gone before the money even enters your account balance.

    PayPal is 3.49% + $0.49 for standard transactions—$3.98 on that same $100. If you’re using Gumroad, they take 10% on the free plan, which includes processing fees. On a $100 sale, you’re down to $90 before anything else happens.

    These fees show up as line items in your dashboard, but they never touch your bank. The net amount—what’s left after processing—is what gets queued for payout.

    Payout schedules and rolling reserves

    Most processors don’t pay you instantly. Stripe’s default payout schedule is two business days in the U.S. If you sell something on Monday, you’ll see the money in your bank on Wednesday—assuming no holds.

    New accounts, accounts with sudden revenue spikes, or high-risk categories (digital products, coaching, info products) often trigger rolling reserves. Stripe might hold 10–30% of each transaction for 30–90 days. If you made $5,000 but 20% is in reserve, only $4,000 moves toward your bank. The rest sits in limbo.

    You won’t always get notified when a reserve is applied. Check your payout report in the dashboard—if “Reserved funds” has a balance, that’s money you’ve earned but can’t access yet.

    Refunds, chargebacks, and clawbacks

    If a customer requests a refund, the processor reverses the transaction and pulls the money back from your next payout. You don’t just lose the sale—you also lose the processing fee. Stripe doesn’t refund their 2.9% + $0.30 when you issue a refund. You’re out the fee twice: once when the customer paid, once when they didn’t.

    Chargebacks are worse. The customer disputes the charge with their bank, and the processor pulls the money back immediately—even if the dispute is weeks old. Stripe charges a $15 chargeback fee on top of the lost sale. PayPal charges $20.

    If you’re running a subscription product and a customer’s card expires, some platforms will retry the charge multiple times. Failed retries don’t cost you fees, but successful retries after a gap can reset your payout schedule.

    Platform fees on top of payment fees

    If you’re selling through a course platform, membership site, or marketplace, they take a cut too. Teachable takes 10% of each sale on the Pro plan ($159/month). Kajabi doesn’t take a transaction fee, but you’re paying $149–$399/month in platform costs.

    Gumroad’s 10% includes payment processing, but that’s still double what you’d pay with Stripe + a standalone site. On $5,000 in sales, that’s $500 to Gumroad vs. ~$150 in Stripe fees if you handle fulfillment yourself.

    These platform fees usually come out before the money reaches the payment processor, so your Stripe dashboard will only show the net revenue after the platform’s cut. If Gumroad shows $5,000 in sales, Stripe sees $4,500, and you get $4,500 minus processing fees.

    What you actually see in your bank

    Let’s say you sold $5,000 in a month. Here’s the realistic breakdown:

    • Payment processing fees (2.9% + $0.30 average): ~$150
    • Platform fee (if applicable, e.g., 10%): $500
    • Rolling reserve (20%, held for 60 days): $870 (on the net $4,350)
    • One refund ($100 sale): -$103.20 (includes lost processing fee)
    • One chargeback ($50 sale): -$66.45 (sale + original fee + $15 chargeback fee)

    Your bank sees roughly $2,810 in the first payout cycle. The reserved $870 trickles in over the next two months. The refund and chargeback are just gone.

    This isn’t a complaint about processors—it’s just how the system works. But if you’re forecasting cash flow or trying to figure out why your revenue and bank balance don’t match, this is the gap.

    Track net revenue, not gross

    Most operators track gross sales because that’s the number platforms show you first. It feels good to say you made $5,000. But your actual operating cash is 15–30% lower, depending on fees, holds, and disputes.

    Build a simple spreadsheet that logs gross sales, processing fees, platform fees, refunds, chargebacks, and reserved amounts. Update it weekly. Your accountant will thank you, and you’ll stop wondering where the money went.

    If you want a cleaner view, connect your payment processor to a tool like QuickBooks Self-Employed or Wave. Both pull transaction data automatically and separate fees from revenue. You’ll see exactly what hit your bank and what didn’t.

    What’s one payment fee or hold that surprised you the first time you saw it? Reply and let me know—I’m curious what trips up operators most.

  • Automation retry logic: when workflows replay steps and when they quit

    Automation retry logic: when workflows replay steps and when they quit

    Automation retry logic: when workflows replay steps and when they quit
    Photo: Orfa Visser via Wikimedia Commons (CC BY 3.0)

    You built a workflow: new Stripe payment triggers a welcome email, adds the customer to a spreadsheet, and posts a Slack notification. It runs flawlessly for three months. Then one morning, Slack’s API times out for six seconds, and your entire automation stops cold.

    Whether that step retries—or silently fails and leaves your workflow half-complete—depends entirely on which tool you’re using and how you configured it. Most operators don’t think about retry logic until something breaks. By then, you’ve already lost data.

    What retry logic actually does

    Retry logic is the ruleset that decides what happens when a step in your workflow fails. The failure might be a network timeout, a rate-limit response from an API, a malformed payload, or a third-party service returning a 500 error.

    Some tools retry the failed step automatically. Others halt the entire workflow and send you a notification. A few do nothing—they log the error and move on, leaving you with incomplete records and no alert.

    The distinction matters most when you’re chaining actions across platforms. If step three fails but steps four and five execute anyway, you end up with a customer charged via Stripe but never added to your CRM. Or a confirmation email sent to someone whose payment actually bounced.

    How the major workflow tools handle retries

    Zapier retries failed steps automatically—up to three times, spaced a few minutes apart. If all three attempts fail, the Zap pauses and you get an email. The retry only applies to the failed step, not the entire workflow. That means earlier steps won’t re-execute, which prevents duplicate charges or double-sent emails.

    Make (formerly Integromat) gives you granular control. You can set retry attempts per module, configure exponential backoff intervals, and define fallback routes if retries exhaust. The default is zero retries—if you don’t configure it, a failed HTTP request just stops the scenario dead.

    n8n offers retry settings at the workflow level and the node level. You can specify attempts, delay between tries, and whether to retry only on specific HTTP status codes (e.g., retry on 429 rate-limit, but not on 404 not-found). It’s powerful, but it requires you to think through failure modes up front.

    Most no-code tools—Pabbly, Integrately, Activepieces—implement Zapier-style automatic retries with little configurability. That’s fine for simple workflows, but it becomes a liability when you need to handle idempotent vs. non-idempotent actions differently.

    When retries make things worse

    Not every failed step should retry. If you’re posting a payment to Stripe and the API returns a 400 error because the card was declined, retrying three times won’t fix it—you’ll just log three identical failures and delay the workflow.

    Worse: if the original request actually succeeded but Stripe’s response timed out before reaching your workflow tool, a retry might charge the customer twice. Stripe’s API is idempotent when you pass an idempotency_key, but most workflow tools don’t generate or pass one by default.

    The same risk applies to any action that creates a record: adding a row to a spreadsheet, sending a transactional email via Postmark, or posting to Slack. If the action completed but the acknowledgment was lost in transit, a retry duplicates it.

    This is why Make and n8n let you disable retries on specific steps. If you’re calling a non-idempotent API, you’re better off logging the failure and handling it manually than risking duplicate actions.

    What to configure before your first failure

    Most operators set up a workflow, test it once with clean data, then assume it’s bulletproof. The first failure happens three months later, in production, with real customer data.

    Before you deploy any multi-step automation, configure these three things:

    Error notifications. Make sure your workflow tool emails or Slacks you when a step fails. Zapier does this by default. Make and n8n require you to add an error-trigger route or enable notifications in settings.

    Retry limits. If your tool allows it, cap retries at two or three attempts with exponential backoff. A six-second delay between attempts is usually enough for transient API issues to resolve.

    Idempotency keys. If you’re calling an API that supports them—Stripe, Postmark, most payment processors—pass a unique key (usually a hash of the trigger event ID) in your request payload. That way, even if the workflow retries, the API won’t duplicate the action.

    One more thing: test a failure scenario manually. Intentionally break an API call—use a bad auth token, or point it at a non-existent endpoint—and watch what your workflow does. Does it retry? Does it notify you? Does it leave the rest of the workflow half-executed?

    You’d be surprised how many tools do nothing.

    Want more operator-focused breakdowns like this? Subscribe to One Two Three Send—we publish a new deep-dive every day on the tools and tactics that actually matter when you’re running a content business solo.

  • LinkedIn post scheduling: when native beats third-party tools

    LinkedIn post scheduling: when native beats third-party tools

    LinkedIn post scheduling: when native beats third-party tools
    Photo: HoganChou via Wikimedia Commons (CC BY-SA 4.0)

    LinkedIn’s native post scheduler went mostly unnoticed when it launched in 2024, but it’s quietly become the better option for a specific use case: posting carousels and link-heavy content without triggering algorithmic penalties.

    If you’re scheduling LinkedIn posts through a third-party tool like Buffer, Hootsuite, or Publer, you’re technically using LinkedIn’s API—and that API strips or degrades certain post features that the native scheduler preserves. The difference shows up in reach, not in whether the post publishes.

    What the native scheduler preserves

    LinkedIn’s in-app scheduler—accessible from the post composer by clicking the clock icon—handles three things differently than API-based tools:

    Carousel uploads. Native scheduling lets you upload multi-page PDFs as carousels. Most third-party tools either don’t support carousels at all or require you to upload each slide as a separate image, which LinkedIn then stitches together. The native path preserves metadata and formatting that the API route often mangles.

    Link preview control. When you paste a URL into the native composer, LinkedIn generates a preview card. You can edit the headline, remove the preview entirely, or let it render. Third-party tools send the link as plain text through the API, and LinkedIn decides whether to generate a preview after the post goes live—usually with worse results and no editorial control.

    Engagement priority. LinkedIn has never officially confirmed this, but multiple operators report that natively-scheduled posts appear to get a slight boost in initial distribution compared to API-scheduled posts. The working theory: LinkedIn treats API posts as “bulk” or “automated” and deprioritizes them in the feed. The delta is small—maybe 10–15% reach difference in the first hour—but it compounds if you’re posting daily.

    When third-party tools still win

    Native scheduling only works if you’re managing one LinkedIn account and you’re comfortable logging into LinkedIn’s interface several times a week. If you’re running multiple profiles, posting to LinkedIn alongside Twitter and Instagram, or collaborating with a team that needs approval workflows, third-party tools still make sense.

    Cross-posting to multiple networks. Publer, Buffer, and Hootsuite let you write once and distribute everywhere. Native scheduling requires you to compose separately for each platform—and LinkedIn’s composer doesn’t save drafts reliably.

    Approval and review workflows. If you’re working with a VA, editor, or client, third-party tools offer commenting, approval gates, and revision history. LinkedIn’s native scheduler is single-user only.

    Analytics consolidation. Third-party dashboards aggregate performance across platforms. LinkedIn’s native analytics live in a separate tab, and you can’t export or compare them to other networks without manual work.

    The hybrid approach most operators use

    Here’s the split that works for most solo operators and small teams: use the native scheduler for high-leverage posts—carousels, long-form text posts, and anything with a link you want to control—and use a third-party tool for everything else.

    That usually means 2–3 native posts per week (your main content pieces) and 3–4 API posts (commentary, reposts, quick takes). You get the reach advantage where it matters and the convenience of automation for lower-stakes content.

    One operator I spoke with—running a B2B consultancy with 18,000 LinkedIn followers—schedules all carousel posts natively and uses Publer for everything else. His carousel posts average 4,200 impressions in the first 24 hours; his API posts average 2,800. Same follower base, same posting times, same topics. The only variable is the scheduling method.

    How to decide

    If you post to LinkedIn once or twice a week, and you’re not managing multiple accounts, the native scheduler is worth the extra two minutes per post. You’ll preserve formatting, control link previews, and likely see a small reach bump.

    If you’re posting daily, managing multiple profiles, or working with a team, stick with a third-party tool and accept the trade-off. The time savings and workflow structure outweigh the reach penalty.

    And if you’re in between—posting 3–5 times a week, mostly solo—try the hybrid model for a month and compare your analytics. Track impressions, engagement rate, and profile visits for native vs. API posts. If the delta is meaningful, shift more posts to native. If it’s negligible, automate everything and move on.

    Want more breakdowns like this? Reply with the tool or feature you want explained next—we read every response.

    Heads up — some links in this article are affiliate links. If you sign up through them, we may earn a small commission at no extra cost to you. We only recommend tools we use ourselves.

  • Traffic from Medium republishing: what happens when you click ‘Import Story’

    Traffic from Medium republishing: what happens when you click ‘Import Story’

    Traffic from Medium republishing: what happens when you click 'Import Story'
    Photo by Leyla M on Unsplash

    Medium’s “Import Story” button looks like a shortcut to wider reach. You’ve already written the post on your own site—why not let Medium’s audience find it too?

    But Medium’s republishing mechanics work differently than syndicating to LinkedIn or dropping a link in a Reddit thread. The platform applies specific SEO directives that change how Google treats both versions of your content. If you’re deciding whether to republish, you need to know what happens behind that import button.

    Medium sets a canonical tag pointing back to your original

    When you use the Import Story feature and paste your original URL, Medium automatically adds a rel="canonical" tag in the HTML header of the republished post. That tag tells Google: “This is a duplicate—credit the original source.”

    In theory, this protects your site from duplicate content penalties and keeps your original URL ranking. In practice, Google usually respects canonical tags, but it’s a hint, not a command. If Medium’s version gets significantly more engagement, backlinks, or social signals, Google may decide to rank it instead.

    Check your Search Console after republishing. If you see impressions shifting to the Medium URL for target keywords, Google ignored the canonical. At that point, you’re competing with your own content.

    Medium sometimes adds noindex to imported posts

    Medium has quietly applied noindex meta tags to some imported stories over the past year, especially for accounts with low follower counts or minimal platform engagement. A noindex directive tells Google not to include the page in search results at all.

    This isn’t universal—high-traffic publications and writers with established Medium followings rarely see it—but if you’re new to the platform or republishing your first few posts, check the page source. If you see <meta name="robots" content="noindex">, your imported story won’t show up in Google, period.

    That kills the SEO upside, but it doesn’t make republishing useless. Medium’s internal distribution—the home feed, topic tags, and recommendations—can still send traffic. You’re just betting on Medium’s algorithm instead of Google’s.

    Referral traffic comes through medium.com, not your backlink profile

    When readers click through from your Medium story to your site, the referrer is medium.com. That’s fine for analytics, but it doesn’t help your backlink profile. Medium uses rel="nofollow" on all outbound links, so even if your story gets 10,000 views and 500 clicks, Google won’t count any of those as endorsements.

    Compare that to a guest post on an independent blog, where you might get a followed link from a domain with authority. Medium republishing is a traffic play, not a link-building one.

    The traffic quality matters more than the volume. Medium readers who click through are often in discovery mode—they’re browsing, not searching with intent. Conversion rates from Medium referrals tend to run 30–50% lower than organic search traffic, based on what operators in communities like Indie Hackers and niche Slack groups report.

    When republishing makes sense

    Republish when your original post has already ranked and captured most of its organic search traffic. If a piece is six months old, sitting on page one for its target keyword, and impressions have plateaued, there’s little downside. You’re adding a second distribution channel without cannibalising fresh SEO potential.

    Also worth it: evergreen how-tos and opinion pieces that aren’t keyword-dependent. If the post’s value is in the take or the tutorial, not the SERP ranking, Medium’s internal audience can be a win. Just make sure you’re linking back to a relevant landing page—your newsletter signup, a related product, or a hub post—so the traffic converts.

    Skip republishing for new posts targeting competitive keywords. Let your original URL build authority first. And avoid it entirely if you’re in a niche where Medium has its own high-authority posts ranking for your target terms. You’ll end up competing with both Medium’s editorial content and your own imported version.

    Check the source before you assume anything

    Before you click Import Story, right-click the last post you republished and view the page source. Search for canonical and noindex. If you see the canonical pointing to your domain and no noindex tag, you’re clear. If not, you know what you’re trading off.

    And after republishing, set a calendar reminder for two weeks out. Open Search Console, filter by page, and compare impressions for both URLs. If your original is holding steady or growing, republishing worked. If Medium’s URL is climbing and yours is dropping, you’ve just learned your site doesn’t have enough authority to override Medium’s domain strength.

    Got a question about republishing, syndication, or content distribution? Reply to this post—we’re tracking operator questions for upcoming Q&A editions.

  • WordPress plugin staging environments: what gets cloned and what doesn’t

    WordPress plugin staging environments: what gets cloned and what doesn’t

    WordPress plugin staging environments: what gets cloned and what doesn't
    Photo: Nevin Aladağ via Wikimedia Commons (CC BY-SA 4.0)

    Most WordPress hosts now offer one-click staging environments. You spin up a copy of your live site, test a plugin update or theme change, then push it back. Clean, safe, professional.

    Except staging environments are selective clones. They copy most of your site, but not all of it—and the gaps aren’t always obvious until something breaks in production.

    If you run a content business on WordPress, you’ve probably assumed staging mirrors everything. It doesn’t. Here’s what actually transfers, what gets left behind, and how to avoid silent failures when you merge changes back to live.

    What staging environments actually copy

    A typical staging setup clones two things: your database and your file system. That includes:

    • WordPress core files
    • Plugins and themes
    • Uploads (images, PDFs, media library assets)
    • Posts, pages, and custom post types
    • User accounts, comments, and most settings

    Most hosts—BigScoots, Kinsta, WP Engine, Flywheel—use this model. The staging site gets its own subdomain (often staging.yourdomain.com or a randomized URL), and you work there without touching production.

    The clone happens at the database and filesystem level. Your staging environment is a snapshot, usually taken within the last few minutes. It’s current, but not live-synced.

    What doesn’t transfer—and why it matters

    Staging environments don’t replicate everything. Here’s what commonly gets left behind:

    External API connections. If your site talks to a payment processor, email platform, or CRM, those connections often stay pointed at production endpoints. Stripe webhooks, Mailchimp API keys, and analytics tracking codes don’t automatically switch to “test mode” just because you’re in staging. You can accidentally trigger real transactions, send live emails, or pollute your analytics with test traffic.

    Cron jobs and scheduled tasks. Staging clones your cron schedule, but it doesn’t always disable it. If you have a plugin that sends daily digest emails or publishes scheduled posts, those tasks might fire from staging—using production data. Some hosts disable wp-cron.php in staging by default. Others don’t.

    CDN and caching layers. Your staging site bypasses your CDN. That’s intentional—caching would defeat the purpose of testing—but it means performance in staging won’t match production. A plugin that works fine in staging might choke under real traffic once your CDN and object cache are back in the loop.

    Environment variables and secrets. If you store API keys or credentials in environment variables (via wp-config.php or server-level config), those may not carry over to staging. Some hosts isolate staging environments deliberately to prevent accidental key reuse. You’ll see “API key missing” errors that don’t appear in production.

    User-uploaded files after the snapshot. Staging clones your uploads directory at the moment you create it. Any images, PDFs, or media uploaded to production after that point won’t appear in staging. If you’re testing a gallery plugin or a membership site with gated downloads, you’re working with stale assets.

    What breaks when you push changes back

    Most staging tools let you push database changes, file changes, or both back to production. This is where silent failures happen.

    If you only push file changes (plugin updates, theme edits), you’re safe—unless those files expect database schema changes that didn’t carry over. A plugin update might add a new table or modify column types. If you skip the database push, production won’t match staging.

    If you push database changes, you’re overwriting production data. That includes posts published since you created staging, comments left by readers, new user signups, and form submissions. One-click database pushes are destructive. Most hosts warn you. Many operators click through anyway.

    The safest approach: push file changes automatically, migrate database changes manually using a migration plugin or SQL export. It’s slower, but you control what gets overwritten.

    How to test without poisoning production

    Before you work in staging, take three steps:

    Disable outbound email and API calls. Install a plugin like WP Mail Logging or use an SMTP plugin’s test mode. If your site integrates with Stripe, Mailchimp, or similar, swap in test API keys for staging. Don’t assume the platform knows you’re in a non-production environment.

    Check your cron schedule. Run wp cron event list via WP-CLI, or use a plugin like WP Crontrol to see what’s queued. Disable any tasks that send email, post to social media, or trigger external webhooks.

    Document what you change. Keep a text file listing every plugin you update, every setting you toggle, every theme file you edit. When you push back to production, you’ll know exactly what should change—and you can verify it did.

    Staging environments are useful, but they’re not magic mirrors. They’re partial clones with built-in gaps. The faster you map those gaps, the fewer surprises you’ll hit when you go live.

    Want more backend WordPress breakdowns? Subscribe to One Two Three Send—we cover the infrastructure stuff other newsletters skip.

  • Course platform video transcoding: what happens behind the upload bar

    Course platform video transcoding: what happens behind the upload bar

    Course platform video transcoding: what happens behind the upload bar
    Photo: ROCKY via Wikimedia Commons (CC BY-SA 4.0)

    You upload a 2GB video file to your course platform. The progress bar hits 100%. You refresh the page—and the video still isn’t playable. Instead, you see “Processing” or “Encoding in progress.”

    What’s happening isn’t a bug. It’s transcoding: the platform is converting your uploaded file into multiple formats and resolutions so learners on different devices and bandwidths can stream it smoothly. But most operators don’t know what’s actually being created, how long it takes, or when pre-encoding on your own machine saves hours of waiting.

    What transcoding creates

    When you upload a single .mp4 file, the platform generates:

    • Multiple resolutions: 1080p, 720p, 480p, and sometimes 360p. Adaptive bitrate streaming (ABR) lets the player switch resolutions mid-playback based on the viewer’s connection speed.
    • Audio-only streams: A separate audio track for mobile users on metered data.
    • Thumbnail images: Usually extracted at the 5-second mark or generated from the first keyframe.
    • Closed-caption tracks (if enabled): Some platforms auto-generate .vtt or .srt subtitle files using speech-to-text.

    Platforms like Teachable, Thinkific, and Kajabi handle this server-side. You upload once; they generate four to six derivative files. For a 60-minute 1080p video at 30fps, expect transcoding to take 15–45 minutes depending on platform load.

    When transcoding stalls

    Three scenarios slow or break the process:

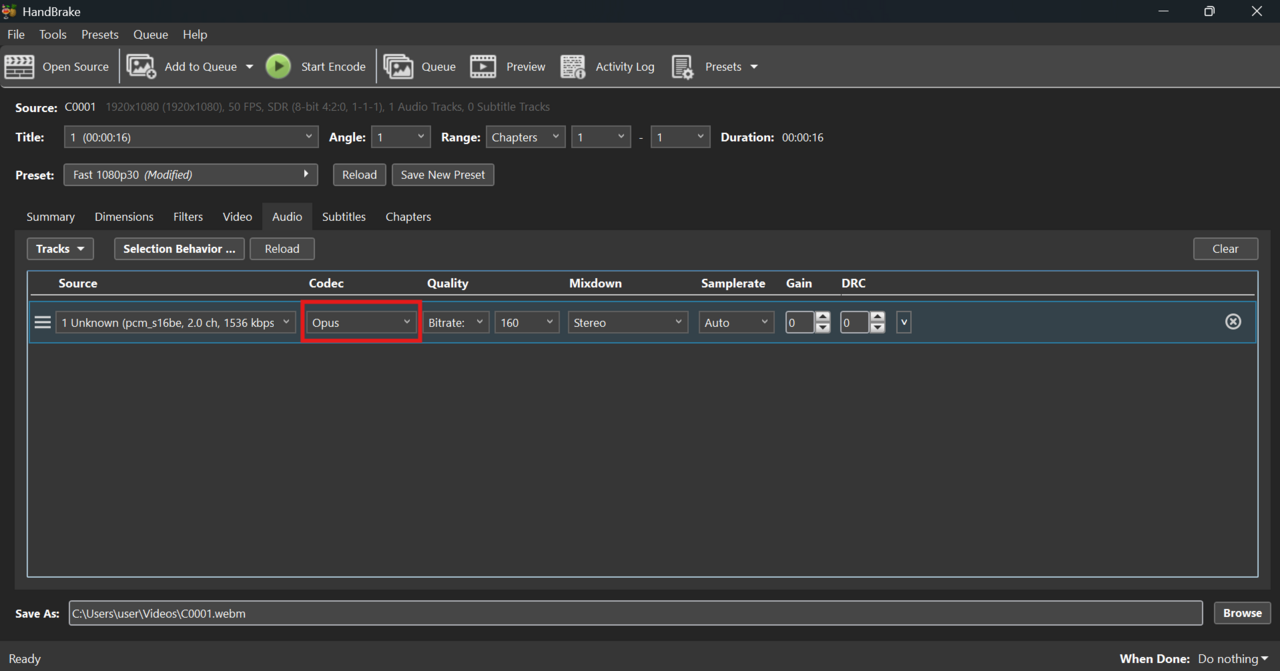
    Variable frame rate (VFR) source files. Screen recordings from tools like OBS or Loom sometimes use VFR to save file size. Transcoders expect constant frame rate (CFR). If your upload takes longer than expected or fails silently, re-encode to CFR using Handbrake (preset: “Fast 1080p30”) before uploading.

    Non-standard codecs. Most platforms expect H.264 video and AAC audio. If you shot in ProRes, HEVC, or VP9, the transcoder may reject the file or produce a low-quality output. Check your export settings: H.264, AAC, .mp4 container, and progressive scan (not interlaced).

    Peak-hour congestion. Transcoding is compute-intensive. Platforms batch-process uploads. If you upload at 9 a.m. EST on a Tuesday when everyone else is launching courses, your video joins a queue. Mid-afternoon or evening uploads often finish faster.

    When to pre-encode locally

    If you’re uploading more than five videos in a session, pre-encoding saves platform processing time and gives you control over quality.

    Use Handbrake (free, cross-platform) with these settings:

    • Preset: “Fast 1080p30” or “HQ 1080p30 Surround” if you have multichannel audio
    • Format: MP4
    • Video codec: H.264, constant quality RF 20–22 (lower number = higher quality)
    • Audio codec: AAC, 128 kbps stereo
    • Framerate: Constant, 30fps (or 25fps for PAL regions)

    A 60-minute talking-head video at RF 22 outputs around 800MB–1.2GB. The platform still transcodes it, but processing time drops by 30–50% because the source is already optimized.

    What you lose with platform transcoding

    Most platforms cap output at 1080p even if you upload 4K. Kajabi, Teachable, and Thinkific all downsample. If you want to deliver 4K to learners, you’ll need to self-host with a video CDN like Bunny.net or Mux—but that adds $20–$200/month depending on bandwidth.

    Platform transcoders also strip metadata. Chapter markers, embedded subtitles, and custom thumbnails uploaded in your video file are ignored. You’ll need to add those through the platform’s interface after transcoding finishes.

    If you’re launching a course in the next 48 hours and uploading a dozen videos, start three days early. Transcoding delay is the most common reason course launches miss their scheduled time.

    Want more operator tactics like this? Subscribe to One Two Three Send—one article every morning on the tools, infrastructure, and strategy behind online businesses.

  • ConvertKit vs. MailerLite vs. Beehiiv: price breaks at 5k, 10k, 50k

    If you’re running a content business and crossing 5,000 subscribers, you’ve probably started doing the math on platform costs. The difference between ConvertKit, MailerLite, and Beehiiv isn’t just monthly pricing—it’s what you get at each tier, what breaks when you scale, and where each platform forces you to upgrade or migrate.

    Here’s an operator-level comparison at the tiers that matter: 5,000, 10,000, and 50,000 subscribers.

    Pricing at scale

    At 5,000 subscribers:

    • ConvertKit: $66/month (Creator plan), unlimited sends
    • MailerLite: $45/month (Growing Business), unlimited sends
    • Beehiiv: $99/month (Scale plan), unlimited sends

    At 10,000 subscribers:

    • ConvertKit: $100/month
    • MailerLite: $75/month
    • Beehiiv: Still $99/month—pricing doesn’t change until 100k

    At 50,000 subscribers:

    • ConvertKit: $208/month
    • MailerLite: $225/month
    • Beehiiv: Still $99/month

    Beehiiv’s flat-rate structure wins on raw cost above 10k subscribers, but that’s not the whole story.

    Feature trade-offs you’ll actually notice

    ConvertKit gives you visual automation workflows, robust tagging, and subscriber scoring at every paid tier. If you’re running a funnel with lead magnets, tripwires, or multi-step onboarding, ConvertKit’s automation builder is the most operator-friendly. The downside: no native referral program, no ad network, and you’ll need Zapier or custom code for anything beyond email.

    MailerLite includes landing pages, pop-ups, and a drag-and-drop site builder in every plan. You can run a lightweight site-plus-newsletter business without WordPress. The automation is simpler than ConvertKit’s, but it works for most workflows. Where MailerLite falls short: no built-in monetization tools, no recommendation network, and segmentation gets clunky above 20k subscribers.

    Beehiiv bundles a referral program, ad network access (on Scale and above), polls, and a recommendation engine. If you’re treating your newsletter as a standalone media property, Beehiiv’s feature set supports that model out of the box. The catch: automations are basic—think “send this email after X days” rather than ConvertKit’s branching logic. If you need complex funnels, you’ll bolt on external tools.

    Who each is best for

    Pick ConvertKit if you’re selling digital products, running evergreen sequences, or need tight control over subscriber journeys. It’s the best tool for creators who treat email as a funnel, not just a broadcast channel. You’ll pay more per subscriber, but the automation flexibility justifies it if your revenue model depends on segmentation and timing.

    Pick MailerLite if you’re early-stage, budget-sensitive, and want an all-in-one starter stack. The site builder and pop-up tools let you skip a separate landing-page tool. It’s ideal for solopreneurs who want simplicity and don’t need advanced monetization features yet. Expect to migrate or supplement when you cross 25k subscribers and need better segmentation.

    Pick Beehiiv if you’re running a publication-style newsletter where growth, referrals, and sponsorships matter more than product funnels. The flat pricing makes budgeting predictable, and the ad network can offset platform costs once you’re approved. You’ll sacrifice automation depth, but if your business model is “grow audience, sell ads or subscriptions,” Beehiiv’s feature set aligns.

    Migration friction points

    All three platforms let you export subscriber lists as CSV, but custom fields and tag structures don’t map cleanly. If you’ve built automations in ConvertKit, expect to rebuild them manually in Beehiiv or MailerLite—there’s no one-click migration for workflows.

    Beehiiv’s referral program data doesn’t export. If you’ve grown 10k subscribers via referrals and want to migrate, you’ll lose the referral tree and reward history.

    MailerLite’s site-builder content lives inside their platform. Migrating to ConvertKit or Beehiiv means rebuilding landing pages elsewhere.

    Want more tool breakdowns like this? Subscribe to One Two Three Send—we compare platforms, dissect pricing, and publish the operator-level details that marketing pages skip.

    Heads up — some links in this article are affiliate links. If you sign up through them, we may earn a small commission at no extra cost to you. We only recommend tools we use ourselves.

  • Analytics sampling kicks in at 500k sessions—here’s what vanishes

    Analytics sampling kicks in at 500k sessions—here’s what vanishes

    Analytics sampling kicks in at 500k sessions—here's what vanishes
    Photo: Saleemkce via Wikimedia Commons (CC BY-SA 4.0)

    If you’ve crossed the half-million session mark in Google Analytics 4 and noticed your reports feeling… fuzzy, you’re not imagining it. GA4 starts applying data sampling once your property processes more than 500,000 sessions in the selected date range, and the effects ripple through every custom report, exploration, and funnel you build.

    Sampling isn’t a bug. It’s a deliberate trade-off Google makes to return reports faster when you’re querying large datasets. But for operators who rely on precise conversion attribution, cohort analysis, or granular funnel breakdowns, sampling introduces enough noise to derail decisions.

    What sampling actually does to your data

    When GA4 samples your data, it processes a subset of your sessions—often between 10% and 50% depending on query complexity—and extrapolates the results across the full dataset. You’ll see a green shield icon in the top-right corner of any sampled report, along with a percentage indicating how much of your data was included.

    The problem isn’t the sampling itself; it’s what gets smoothed over in the process. Event counts round to the nearest integer after extrapolation. Rare conversion paths disappear entirely if they don’t appear in the sample. Multi-touch attribution models lose fidelity because session sequences get stitched together from incomplete fragments.

    If you’re running A/B tests on landing pages, a 2% lift in conversions might be real—or it might be sampling noise. GA4 won’t tell you which.

    Where sampling breaks operator workflows

    Sampling hits hardest in three scenarios:

    Custom funnels with tight segmentation. If you’re filtering by UTM source, device category, and a custom event parameter, GA4 has to scan millions of rows to assemble your report. That pushes you past the sampling threshold even if your total session count is under 500k for the date range. The tighter your segment, the more aggressive the sampling.

    Cohort retention analysis. Operators tracking subscriber lifecycle—first visit to signup to first purchase—need session-level precision. Sampling collapses low-frequency paths, so if 3% of your signups convert via a specific two-week sequence, that segment may not survive the sample cut.

    Multi-channel attribution. GA4’s data-driven attribution model already makes probabilistic guesses about credit assignment. Add sampling on top, and you’re attributing revenue based on a model trained on incomplete data. If your paid social budget depends on those numbers, you’re optimizing toward a phantom baseline.

    When to export raw event data instead

    GA4 offers a BigQuery export that bypasses sampling entirely. Every event, parameter, and user property lands in your own BigQuery dataset within 24 hours, and you can query it without extrapolation.

    The free tier covers up to 10GB of queries per month, which is enough for most solo operators to run weekly cohort reports and attribution models. Once you cross that threshold, BigQuery charges $6.25 per additional TB scanned—but you control query costs by limiting date ranges and indexing high-cardinality fields.

    If you’re already paying for analytics tooling like Mixpanel or Amplitude, BigQuery is cheaper for historical analysis. You lose the GA4 interface, but you gain SQL-level control over every dimension and metric.

    The trade-off: you need to write SQL, or pay someone who can. Tools like Looker Studio connect to BigQuery and offer a visual layer, but you’re still responsible for schema design and query optimization.

    How to check if you’re being sampled right now

    Open any Exploration report in GA4. If the green shield icon appears in the top right, click it. GA4 will show you the exact percentage of sessions included in the report and offer a link to adjust your date range or remove segments to reduce sampling.

    If you’re consistently seeing sample rates below 50%, your reports are unreliable for anything beyond directional trends. That’s the signal to either narrow your date ranges, simplify your segments, or move attribution analysis to BigQuery.

    One more thing: GA4 Analytics 360—the paid tier starting at $50,000/year—raises the sampling threshold to 100 million sessions and offers unsampled reporting in the interface. Unless you’re processing tens of millions of events per month, the BigQuery export is the better ROI.

    If you’re hitting sampling limits and want to compare how other analytics platforms handle high-volume properties, reply to this issue with your current session count—we’ll dig into it in a future piece.

  • WordPress database backups: what incremental snapshots skip

    WordPress database backups: what incremental snapshots skip

    WordPress database backups: what incremental snapshots skip
    Photo by CARTIST on Unsplash

    Incremental database backups sound efficient: only save what changed since the last snapshot, cut storage costs, speed up the process. Most WordPress backup plugins offer the option, and plenty of managed hosts enable it by default.

    But incremental backups make silent trade-offs. They skip tables that haven’t registered a timestamp change, ignore transient data that might matter during recovery, and often fail to capture schema modifications. If you’ve ever restored from an incremental backup and found missing comments, broken plugin settings, or mysteriously stale content, this is why.

    How incremental database backups decide what to save

    An incremental backup compares the current database state to the last full or incremental snapshot. It looks for changed rows, usually by checking a modified or updated_at timestamp column. If a row hasn’t been touched since the last backup, it gets skipped.

    That works well for posts, pages, and user accounts—tables with reliable timestamp tracking. It breaks down for:

    • Tables without timestamp columns. Some plugins store settings in custom tables with no date field. The backup tool can’t tell if the data changed, so it assumes it didn’t.
    • Schema changes. If you add a column, rename a table, or adjust an index, the incremental job may not flag that as a data change. The new structure exists, but the backup doesn’t record it.
    • Transient and cache tables. WordPress uses wp_options to store transients—temporary data with expiration timestamps. Incremental backups often exclude transients by design, assuming they’re disposable. That’s true for caching, but some plugins misuse transients to store semi-permanent config.
    • Comment metadata. If a comment gets edited or a new meta field is added via a plugin, the parent comment row’s timestamp might not update. The incremental scan misses it.

    You won’t notice the gaps until you restore. Then you’re troubleshooting why a contact form stopped working or why a membership plugin forgot half its settings.

    When incremental backups make sense

    If your site publishes daily content and you’re backing up multiple times per day, incremental snapshots cut down on redundant transfers. A site publishing ten posts a day doesn’t need to re-export its entire wp_posts table every hour—just the new rows.

    Incremental backups also help when bandwidth or storage is metered. A full WordPress database backup on a site with 50,000 posts and 200,000 comments can run 500 MB to 1 GB compressed. Doing that hourly gets expensive. An incremental job might be 5–20 MB.

    But incremental-only strategies fail during migrations, plugin conflicts, or schema drift. If your last full backup was three months ago and you’ve been running incrementals since, you’re stitching together dozens of delta files during a restore. One corrupted increment in the chain, and the whole recovery breaks.

    How to layer full and incremental backups without waste

    Run a full database backup weekly. Run incrementals daily or after major content pushes. Store both.

    Most backup plugins let you set independent schedules. UpdraftPlus, for example, supports separate intervals for full and incremental jobs. BackupBuddy and BlogVault do the same. If you’re on managed WordPress hosting with BigScoots or a similar provider, check whether their automated backups are full or incremental—and whether you can trigger a manual full snapshot before big updates.

    Tag your full backups clearly. If you’re using a plugin that stores backups in Amazon S3, Google Cloud Storage, or Backblaze B2, add a naming convention: full-2026-09-27.sql.gz vs. incr-2026-09-27-14-00.sql.gz. When you need to restore, you’ll know which file is the anchor.

    Test a restore at least once per quarter. Spin up a local WordPress instance with Local by Flywheel or a staging environment, restore from your most recent full backup, then layer on the incrementals. Confirm that everything loads: plugins activate, custom post types appear, user roles are intact, and forms submit. If something’s missing, adjust your backup scope or switch to full-only until you know why.

    What to check in your plugin’s incremental settings

    Open your backup plugin’s settings and look for these options:

    • Table exclusion list. Some plugins exclude wp_options transients by default. If you rely on plugins that store settings there, remove the exclusion or switch to full backups.
    • Change detection method. Does the plugin use timestamp columns, row checksums, or binary logs? Checksum-based detection catches more changes but takes longer. Timestamp detection is faster but misses schema edits.
    • Retention policy. How many incremental snapshots does the plugin keep? If it’s set to retain only the last seven, and your last full backup was two weeks ago, you can’t reconstruct the database past seven days.
    • Manual trigger. Can you force a full backup on demand? You should be able to run one before plugin updates, theme changes, or bulk imports—events that modify the database in ways incrementals might miss.

    If your plugin doesn’t expose these controls, consider switching. UpdraftPlus, BackWPup, and Duplicator all offer granular settings. Managed hosts often abstract this away—ask support whether their incremental backups include schema changes and plugin config tables.

    Want more breakdowns of the infrastructure tools that underpin online businesses? Subscribe to One Two Three Send and get one operator-focused deep dive every day.