Author: onetwothreeadmin

  • Mailchimp segment sync lag: when audience filters take 90 minutes

    Mailchimp segment sync lag: when audience filters take 90 minutes

    Mailchimp segment sync lag: when audience filters take 90 minutes
    Photo: Mailchimp via Wikimedia Commons (CC BY-SA 4.0)

    If you’ve ever built a segment in Mailchimp based on subscriber activity—opens, clicks, sign-up date, or custom field values—and then wondered why subscribers aren’t appearing where they should, you’ve hit the platform’s segment sync delay.

    Mailchimp segments aren’t live queries. They’re pre-calculated lists that refresh on a schedule you don’t control. For solo operators running time-sensitive campaigns or automation sequences, that lag can break workflows in ways that aren’t obvious until someone replies asking why they got the wrong email.

    How Mailchimp calculates segments

    When you create a segment using conditions—”opened any campaign in the last 30 days,” “signed up before January 1,” “has tag X but not tag Y”—Mailchimp evaluates those conditions in batch jobs, not in real time.

    The refresh interval varies by account size and server load, but the typical window is 60 to 90 minutes. During peak sending hours (weekday mornings in US time zones), that window can stretch longer.

    This means if a subscriber opens your email at 9:00 a.m. and you send a follow-up campaign at 9:15 a.m. to a segment of “opened in the last hour,” they won’t be included. The segment hasn’t re-evaluated yet.

    Tags, by contrast, apply instantly. If you add a tag via automation or manual action, it’s available immediately for campaign targeting or automation triggers.

    What triggers a segment refresh

    Mailchimp doesn’t publish the exact refresh logic, but based on operator reports and support documentation, segments re-evaluate:

    • Every 60–90 minutes during normal load
    • When you manually load the segment preview in the campaign builder (this forces a one-time refresh for that view only—it doesn’t update the underlying segment data)
    • Before a scheduled campaign sends, if the segment is used as the recipient list (this is inconsistent and shouldn’t be relied on)

    There’s no manual “refresh now” button. You can’t force a global recalculation.

    When lag breaks workflows

    The most common failure mode: behavioural follow-ups.

    Let’s say you send a product announcement at 8:00 a.m. You want to send a second email at 10:00 a.m. to everyone who opened the first one. You build a segment: “opened campaign [Product Announcement] in the last 3 hours.”

    At 10:00 a.m., that segment might still reflect data from 8:30 a.m. Subscribers who opened at 9:45 a.m. won’t be in the list. You either send to an incomplete audience or delay the campaign and hope the next sync catches up.

    The same issue hits automation sequences that rely on segment conditions as entry or exit rules. A subscriber might meet the criteria but not enter the automation for 90 minutes—or exit too late and receive an email they shouldn’t.

    When to use tags instead

    If timing matters, use tags and automation to apply them immediately:

    • Set up an automation that triggers when someone opens a specific campaign, then applies a tag (“Opened Product Announcement”).
    • Target your follow-up campaign to that tag, not a segment condition.
    • The tag applies in near-real time (under 5 minutes in most cases), so your 10:00 a.m. send includes everyone who opened by 9:55 a.m.

    Tags cost you in list complexity—you’ll accumulate more of them, and you’ll need a cleanup workflow to remove outdated tags—but they give you control over timing.

    For static conditions that don’t change often (sign-up date, geographic location, subscription tier), segments work fine. For behavioural targeting within a 24-hour window, tags are the only reliable option.

    The non-obvious workaround

    If you’re locked into using segments and can’t refactor to tags, pad your timing assumptions by two hours.

    Instead of “opened in the last 3 hours,” use “opened in the last 5 hours.” Instead of scheduling a follow-up 2 hours after the initial send, wait 4 hours. This accounts for both the segment sync lag and any delivery delays on the original campaign.

    It’s not elegant, but it’s more reliable than hoping Mailchimp’s batch job runs on your schedule.

    If you’re running a content business where timing matters—launch sequences, event-driven follow-ups, or behaviour-based upsells—segment sync lag is a tax on execution speed. You can work around it, but it’s worth knowing the cost before you build a workflow that assumes real-time data.

    Hit reply if you’ve found a segment refresh pattern we missed—we’re collecting operator notes on timing across ESPs.
  • Buffer vs. Publer vs. Later: which scheduler handles threads best

    Social media threads—Twitter/X chains, LinkedIn carousels, Instagram multi-image stories—are how solo operators turn one idea into distributed reach. But scheduling them isn’t uniform across tools.

    Most operators pick a social scheduler based on price or interface polish. Then they hit publish on a six-tweet thread and discover tweet four posted out of order, or the entire chain collapsed into a single post with broken formatting.

    Here’s how three popular scheduling tools handle threads, where each breaks down, and what you actually pay when you scale beyond one platform.

    Buffer: native thread support, but platform-limited

    Buffer added native Twitter/X thread scheduling in late 2023. You compose each tweet in a stacked editor, preview the chain, and schedule it as a unit. When it publishes, Buffer posts tweet one, waits for the API response with the tweet ID, then replies with tweet two, and so on.

    Where it works: Twitter/X threads publish reliably. You can schedule up to 25 tweets in a chain. Buffer respects Twitter’s rate limits and won’t collapse your thread into a quote-tweet disaster.

    Where it breaks: LinkedIn carousels aren’t supported—Buffer treats each slide as a separate post. Instagram carousels work, but you can’t schedule Story sequences; each Story frame posts as an individual story, not a connected thread. Threads (Meta’s app) support is still in beta and occasionally drops the reply chain.

    Pricing: Buffer’s Essentials plan is $6/month per social channel. If you’re scheduling to Twitter, LinkedIn, and Instagram, that’s $18/month. The Team plan ($12/channel/month) adds collaboration and approval workflows, useful if you’re delegating content but overkill for most solo operators.

    Best for: Operators who primarily publish Twitter/X threads and want a clean, minimal interface without feature bloat.

    Publer: cross-platform thread scheduling with bulk upload

    Publer supports threads across Twitter/X, Threads (Meta), and LinkedIn. You can compose threads in-app or bulk-import from a CSV—useful if you draft in Notion or a spreadsheet.

    Where it works: Twitter/X threads schedule reliably, same as Buffer. LinkedIn carousel posts—where each slide is a separate image in a single post—work if you upload images in sequence and enable “carousel mode.” Threads (Meta) chains publish as reply threads, not separate posts. Instagram carousel scheduling works for feed posts; Publer auto-detects multi-image uploads and groups them.

    Where it breaks: LinkedIn comment threads—where you post an update, then immediately comment with a follow-up—aren’t natively supported. You’d have to schedule the main post, wait for it to publish, grab the post URL, then manually schedule a comment. Instagram Story sequences still post as individual frames, not a connected story thread.

    Pricing: Publer’s Professional plan is $12/month for up to 10 social accounts (not per-channel pricing like Buffer). If you’re managing Twitter, LinkedIn, Instagram, Threads, and Facebook, you’re still at $12/month total. Bulk scheduling and CSV imports are included at this tier.

    Best for: Operators managing multiple platforms who want one flat price and need bulk-upload workflows for batching content.

    Later: Instagram-first, thread support lags elsewhere

    Later started as an Instagram scheduler and still optimizes for visual-first platforms. Thread support exists for Twitter/X and Threads (Meta), but it’s not the product’s strength.

    Where it works: Instagram carousel posts schedule smoothly—Later’s visual grid planner shows how carousels will appear in your feed before they publish. You can preview the sequence, reorder images, and schedule. Twitter/X threads work, but the editor is clunkier than Buffer’s; you compose in a single text box with line breaks, and Later parses it into individual tweets. It’s functional but error-prone if you don’t format carefully.

    Where it breaks: LinkedIn carousel support is absent—Later posts each slide as a separate update. Threads (Meta) scheduling exists but doesn’t handle reply chains; it posts each message as a standalone thread post, not threaded replies. If you’re publishing Twitter threads with images, Later occasionally mis-attaches media to the wrong tweet in the sequence.

    Pricing: Later’s Starter plan is $25/month for one social set (one account per platform: Instagram, Facebook, Twitter, LinkedIn, TikTok, Pinterest). If you need two Instagram accounts or two Twitter accounts, you jump to the Growth plan at $45/month. There’s no per-channel pricing flexibility.

    Best for: Operators whose primary platform is Instagram and who occasionally cross-post to Twitter. If threads are central to your strategy, Later isn’t the tool.

    Which one to pick

    If you publish mostly to Twitter/X and want the cleanest thread editor, use Buffer. If you’re managing three or more platforms and want flat-rate pricing with bulk upload, use Publer. If Instagram is your lead channel and threads are secondary, Later works—but you’re paying more for features you won’t use.

    None of these tools perfectly handle LinkedIn comment threads or Instagram Story sequences. For those, you’re still scheduling the first post and manually publishing follow-ups, or using native platform schedulers (LinkedIn’s built-in scheduler supports comment threads; Instagram’s Creator Studio handles Story sequences).

    Want more tool breakdowns like this? Subscribe to One Two Three Send for weekly operator-focused comparisons, no fluff.

    Heads up — some links in this article are affiliate links. If you sign up through them, we may earn a small commission at no extra cost to you. We only recommend tools we use ourselves.

  • SEO keyword cannibalization: how to audit and fix overlapping URLs

    SEO keyword cannibalization: how to audit and fix overlapping URLs

    SEO keyword cannibalization: how to audit and fix overlapping URLs
    Photo by Justin Morgan on Unsplash

    Keyword cannibalization happens when two or more pages on your site target the same search intent. Google sees the overlap, gets confused about which page to rank, and often picks the wrong one—or ranks neither well.

    For solo operators running content sites, this is common. You publish consistently, cover similar topics from different angles, and eventually end up with three blog posts competing for “best email marketing tools” when you only wanted one to rank.

    Here’s how to find it, decide what to keep, and fix it without tanking your traffic.

    How to audit for cannibalization

    Start with Google Search Console. Go to Performance, filter by Pages, and look for multiple URLs ranking for the same query.

    Export the last 90 days of data. Sort by query, then by URL. If you see two or more pages sharing clicks for the same keyword, you’ve got overlap.

    Pay attention to queries where:

    • Both pages get impressions but low clicks (CTR under 2%)
    • The URL ranking isn’t your best or most recent content
    • Position fluctuates wildly week-to-week between the two URLs

    That last one is the tell. When Google can’t decide which page to show, it swaps them in and out. You lose rankings momentum on both.

    For a faster scan, use the site: operator in Google with your target keyword. Search site:yourdomain.com "email marketing tools" and see what ranks. If more than one page appears in the top 10 results, you’re splitting authority.

    Decide which page wins

    Don’t merge by default. Sometimes the fix is to differentiate, not consolidate.

    Ask three questions:

    1. Which page has more backlinks? Check in Ahrefs, Semrush, or your link-tracking tool. The page with established inbound links has more authority. Keep it.

    2. Which page converts better? If one drives email signups or affiliate clicks and the other doesn’t, keep the converter and redirect the other.

    3. Can you split the intent? If one post is “best email tools for solo creators” and another is “email tools for e-commerce stores,” the keywords overlap but the intent doesn’t. Rewrite the intros and meta descriptions to clarify who each post is for. Add modifiers to titles. Google will separate them.

    If the intent truly overlaps and neither page has a strong edge, pick the newer or more comprehensive one.

    Three fixes that work

    Option 1: 301 redirect the weaker page. This passes link equity and clears the confusion. Update any internal links pointing to the old URL. In WordPress, use the Redirection plugin or add the rule in your .htaccess file. Most hosting dashboards let you set this in the control panel.

    Option 2: Merge the content. If both pages have useful sections, combine them into one definitive post. Copy the best paragraphs, update the publish date, and redirect the old URL to the new merged piece. Don’t just copy-paste—rewrite to avoid redundancy.

    Option 3: Noindex the weaker page. If you want to keep the page live for internal reasons (it’s linked in a course, referenced in a product, or serves a specific audience segment), add a noindex meta tag. Google stops ranking it, but users can still access it directly. This works when the page has value but doesn’t need to compete in search.

    What happens after the fix

    Expect a ranking dip for 7–14 days. Google recrawls, reindexes, and reassigns authority. If you redirected correctly, the surviving page usually recovers and ranks higher than either page did before.

    Track it in Search Console. Filter by the surviving URL and watch impressions and average position over the next 30 days. If position improves but clicks don’t, your meta description or title probably needs work.

    One non-obvious tip: after you fix cannibalization, update your internal links. If five old posts linked to the page you just redirected, edit them to point directly to the winner. It speeds up reindexing and reinforces the new structure.

    Got a question about SEO, traffic, or tooling? Reply to this email—we cover reader questions every Sunday.

  • Ghost CDN image transforms: what resizes, what doesn’t, and cost

    Ghost CDN image transforms: what resizes, what doesn’t, and cost

    Ghost CDN image transforms: what resizes, what doesn't, and cost
    Photo: TMM53 via Wikimedia Commons (CC BY 4.0)

    Ghost ships with a content delivery network that automatically resizes images. Upload a 4000×3000 PNG, and Ghost serves readers a 720px WebP instead—unless your theme requests a different size, or the image format doesn’t support transformation, or you hit one of several quiet edge cases.

    Most operators assume the CDN “just works.” It mostly does. But understanding what triggers a transform, what gets served as-is, and how Ghost bills for bandwidth saves you from surprise overage invoices and layout shifts when images don’t resize as expected.

    What formats transform and what gets passed through

    Ghost’s CDN—hosted on Cloudflare for Ghost(Pro) plans and configurable for self-hosted installs—applies transformations to JPEG, PNG, and WebP uploads. It converts them to WebP or AVIF (depending on browser support) and resizes them based on the srcset attributes your theme declares.

    GIF files do not transform. Neither do SVGs. Upload a 2MB GIF, and every reader downloads the full 2MB, regardless of viewport size. Same with SVG: no resize, no format conversion. Ghost serves them byte-for-byte as uploaded.

    This matters if you’re embedding animated illustrations or icon libraries. A single large GIF in a popular post can chew through your monthly bandwidth allocation in hours. Check your Ghost analytics bandwidth report (Settings → Labs → Beta features → Enable staff users) to see per-post transfer totals. If one post accounts for 40% of your monthly bandwidth, check for un-transformed assets.

    Resize breakpoints and theme control

    Ghost doesn’t decide image sizes on its own. Your theme’s {{img_url}} helper or <img srcset> markup tells the CDN which widths to generate. The default Casper theme requests 300w, 600w, 1000w, and 2000w variants. If your theme doesn’t declare a srcset, Ghost serves the original upload—no resize.

    Custom themes sometimes hardcode a single image URL without size parameters. When that happens, readers on mobile download the same 2000px file as desktop users. You’ll see this in your bandwidth logs: high transfer volumes from mobile user agents.

    The fix: audit your theme’s image partials. Look for <img src="{{img_url}}"> without a size argument or srcset. Replace with <img srcset="{{img_url size='s'}} 300w, {{img_url size='m'}} 600w, {{img_url size='l'}} 1000w, {{img_url size='xl'}} 2000w" sizes="(max-width: 800px) 400px, 800px">. Ghost’s CDN generates those variants on-demand and caches them.

    What you pay and when costs spike

    Ghost(Pro) plans include bandwidth: 50 GB on the Starter plan ($11/month), 350 GB on Creator ($31/month), and 1 TB on Team ($63/month). Overages cost $1 per GB on Starter, $0.50 per GB on Creator, and negotiated rates on Team.

    Image transforms themselves don’t cost extra—they’re included in the CDN—but cache misses drive up bandwidth. Each new transform (a new size or format combination) counts as a fresh origin request and CDN delivery. If your theme declares ten srcset widths and your CDN cache TTL is short, you’re generating and serving ten variants per image per cache expiration cycle.

    Ghost’s CDN cache is tied to Cloudflare’s edge network. Time-to-live defaults to one year for transformed images, but purging your CDN cache (via Ghost admin or API) invalidates all variants. If you purge after every post publish, you’re forcing full re-transforms for your entire image library every time. That’s fine for a 20-post blog. It’s expensive for a 2,000-post archive.

    One operator I talked to in August saw bandwidth jump from 80 GB to 240 GB in a single month after switching themes. The new theme requested five additional srcset widths. Ghost generated five new variants for every image in every post ever published, then served all of them to returning readers whose browsers requested the new sizes. Cost: $80 in overage fees on a Creator plan.

    One non-obvious tip: preload hero images with explicit dimensions

    Ghost’s image CDN is reactive. It doesn’t pre-generate transforms until a reader requests a specific size. If your post’s hero image is above the fold and your theme doesn’t preload it, readers see layout shift while the browser waits for the CDN to resize and deliver the image.

    Fix it by adding explicit width and height attributes to hero images in your theme’s post template. Ghost’s CDN still transforms the image, but the browser reserves layout space immediately. Add <link rel="preload" as="image" href="{{img_url feature_image size='xl'}}"> in your post head partial for above-fold images. The CDN delivers the transform faster, and Core Web Vitals improve.

    Most operators never touch Ghost’s CDN settings. But if you’re seeing unexpected bandwidth bills, slow image loads, or layout shifts on mobile, start by checking which formats you’re uploading, what your theme requests, and whether your cache purge strategy is forcing expensive re-transforms.

    Got a Ghost CDN question or a bandwidth story? Reply to this email—I read every one, and operator experiences often become future articles.

  • Stripe’s payment intent lifecycle: where charges wait and why

    Stripe’s payment intent lifecycle: where charges wait and why

    Stripe's payment intent lifecycle: where charges wait and why
    Photo: Zina Deretsky, National Science Foundation via Wikimedia Commons (Public domain)

    Most solo operators think Stripe charges happen instantly. Click the button, money moves, done. But behind every payment sits a state machine with six distinct phases—and knowing where your charge actually is can save you hours of customer-support confusion and lost revenue.

    Payment intents are Stripe’s core transaction object. They track a single charge from creation to completion, and they don’t always move in straight lines. Here’s how the lifecycle actually works, what delays the flow, and one non-obvious trick that prevents duplicate charges.

    The six states every payment intent moves through

    When a customer submits payment, Stripe creates a PaymentIntent object. It starts in one of these states:

    • requires_payment_method – Intent created, but no card attached yet. Happens when you create the intent server-side before the customer sees the form.
    • requires_confirmation – Card attached, waiting for you to confirm the charge. Manual confirmation mode only.
    • requires_action – 3D Secure or bank authentication needed. This is where most “the payment didn’t go through” support emails come from.
    • processing – Stripe is talking to the bank. Usually lasts 1–3 seconds, but can hang for minutes on certain card networks.
    • requires_capture – Charge authorized, waiting for you to capture it. Only applies if you’ve enabled manual capture.
    • succeeded – Money secured. You can fulfill the order.

    Failed charges land in canceled or move back to requires_payment_method if you want to let the customer retry with a different card.

    Where charges stall—and what to check

    The most common hangup is requires_action. Stripe redirects the customer to their bank for 3D Secure authentication, but if the popup gets blocked, the redirect fails silently, or the customer closes the window, the intent never progresses. The charge stays pending indefinitely.

    Stripe’s webhook fires a payment_intent.requires_action event. If you’re not listening for it, you’ll never know the customer is stuck. Set up a webhook listener that emails the customer a direct authentication link when this fires—Stripe includes it in the next_action.redirect_to_url field.

    Processing delays happen more often than Stripe’s docs suggest. Visa and Mastercard usually respond in under two seconds, but Discover, certain co-branded cards, and international issuers can take 15–30 seconds. If your checkout flow redirects to a confirmation page immediately after submission, customers see a blank order and panic. Wait for the payment_intent.succeeded webhook before showing success.

    Manual capture mode (requires_capture) is useful for high-value orders where you want to authorize the charge but delay settlement until you ship. But Stripe auto-cancels uncaptured intents after seven days. If you’re running a pre-order or made-to-order business, you need to either capture within a week or switch to a different payment flow entirely—like invoices with NET terms.

    The idempotency key trick

    Here’s the non-obvious tip: Stripe’s API accepts an idempotency_key parameter on every PaymentIntent creation request. If your customer double-clicks the submit button, or your server retries a failed request, Stripe checks the key. If it matches an existing intent created in the last 24 hours, Stripe returns the original object instead of creating a duplicate charge.

    Most client libraries don’t set this automatically. You need to generate a unique key per transaction—usually a hash of the user ID, cart total, and timestamp—and pass it explicitly:

    stripe.paymentIntents.create({ amount: 5000, currency: 'usd' }, { idempotencyKey: 'user123_1697654400_5000' });

    Without this, double-click bugs charge customers twice. Stripe won’t refund both automatically—you’ll eat the dispute fee and the support time.

    When to use automatic vs. manual confirmation

    Stripe defaults to automatic confirmation: as soon as the card is attached, the charge fires. This works for most solo operators. But if you’re running a multi-step checkout—cart → shipping → payment—and you want to confirm inventory or apply fraud checks before charging, switch to manual confirmation mode.

    Set confirmation_method: 'manual' when creating the intent. The intent will pause at requires_confirmation until you call stripe.paymentIntents.confirm(). This gives you a hook to run your own validation logic server-side before money moves.

    Manual confirmation adds complexity—you need to handle the confirmation call in your webhook flow or backend—but it prevents scenarios where Stripe charges a customer for an out-of-stock item because your inventory check ran after payment.

    What to monitor in your dashboard

    Stripe’s dashboard shows payment intent states in real time, but it doesn’t alert you when intents get stuck. Set up a daily filter for intents in requires_action or processing that are older than 30 minutes. Those are your lost conversions—customers who started checkout, hit a snag, and never came back.

    For automated monitoring, pull the payment_intent.processing and payment_intent.requires_action webhook events into your analytics tool and track time-to-resolution. If your median processing time jumps above five seconds, you’re either seeing more international cards or your webhook handler is slow.

    One more thing: Stripe’s test mode doesn’t simulate processing delays. Test cards move instantly from requires_confirmation to succeeded. If you want to test your timeout logic, you need to use a live-mode charge with a real card in a staging environment, then immediately refund it.

    Got a payment-flow question? Reply to this email—I’ll cover it in a future breakdown. And if you found this useful, forward it to another operator who’s wiring up Stripe for the first time.

  • AI model context windows expire mid-task—here’s when

    AI model context windows expire mid-task—here’s when

    AI model context windows expire mid-task—here's when
    Photo: Dietmar Rabich via Wikimedia Commons (CC BY-SA 4.0)

    You’re halfway through drafting a series of social posts with an AI assistant. You step away to take a call, answer some emails, grab lunch. When you return and ask it to continue, the tone shifts. It forgets the audience you described. The product details you fed it earlier are gone.

    This isn’t a bug. It’s how AI context windows work—and most operators don’t realize their session has an expiration timer running in the background.

    What actually expires

    When you interact with an AI model through a chat interface—Claude, ChatGPT, Gemini, or an embedded assistant in a writing tool—the system maintains a “context window.” That’s the running record of everything you and the model have said in the current conversation.

    But context isn’t free. It costs tokens to store, retrieve, and process. So platforms set limits on how long that context persists when you’re inactive.

    Most tools reset after 30 to 90 minutes of inactivity. Claude‘s web interface, for example, typically expires sessions around 60 minutes. ChatGPT’s free tier is closer to 30. Some API-based tools let you configure the timeout, but defaults rarely exceed two hours.

    What gets lost:

    • Previous instructions you gave about tone, audience, or format
    • Background data you pasted in—product specs, customer quotes, content briefs
    • Refinements you made over multiple turns
    • The thread of logic that led to the current draft

    When the session expires, the model starts fresh. It won’t remember that you asked it to write for a technical audience, avoid jargon, or reference the pricing table you shared earlier.

    Why this matters for solo operators

    If you’re using AI to draft a newsletter, write ad copy, or generate a content calendar, you’re rarely doing it in one uninterrupted sitting. You stop to check a source, review a past campaign, or handle a customer question.

    That 10-minute detour might not feel long, but if you’ve been idle for 45 minutes total across multiple breaks, you’re approaching the cutoff. The next time you return, the assistant has no memory of your earlier work.

    This is especially painful when you’re iterating. You spend 20 minutes training the model on your brand voice, then walk away. When you come back to generate the next batch, you’re starting over.

    How to work around expiration

    The simplest fix: copy your prompt and the model’s output into a text file before you step away. If the session expires, you can paste it back in as context for the next request.

    For longer projects, build a reusable prompt template that includes all your standing instructions—brand voice, audience details, formatting rules. Store it in a note-taking tool or a dedicated prompt library. Each time you start a new session, paste it in as the first message.

    If you’re using an API-based tool (like Claude via API or OpenAI’s GPT models in a custom workflow), check whether the platform supports session persistence or custom timeout settings. Some let you extend the window to several hours, though you’ll pay more in token costs.

    Another tactic: send a short message every 20–30 minutes to keep the session alive. A simple “continue” or “hold that thought” resets the inactivity clock. This works if you’re actively multitasking but not if you’ve genuinely stepped away.

    When to let it expire

    Not every conversation needs to persist. If you’re using AI for one-off tasks—rewriting a single headline, generating a quick email reply, brainstorming a post idea—letting the context expire is fine. You don’t need the model to remember what you asked it an hour ago.

    But if you’re building something over multiple turns—drafting a multi-part email sequence, developing a content strategy, refining a landing page—treat the context window like unsaved work. Don’t assume it’ll be there when you return.

    Most AI tools don’t warn you when expiration is approaching. The session just ends. So if you’re planning to step away for more than 15 minutes, save your work externally. Copy the thread, export the draft, or paste key instructions into a doc.

    Context windows are cheap until they disappear. Plan accordingly.

    Want more breakdowns like this? Subscribe to One Two Three Send for weekly operator-focused takes on the tools and tactics that actually matter.

    Heads up — some links in this article are affiliate links. If you sign up through them, we may earn a small commission at no extra cost to you. We only recommend tools we use ourselves.

  • Productivity tool trial periods: how long you really get to test

    Productivity tool trial periods: how long you really get to test

    Productivity tool trial periods: how long you really get to test
    Photo by Isaac Smith on Unsplash

    You sign up for a productivity tool on a Monday afternoon. The dashboard says “14-day trial.” You assume you have two full weeks to decide. By the time you log back in the following Tuesday—eight days later—you’re billed. The trial expired overnight.

    This isn’t a scam. It’s how most SaaS trials count days, and if you run a content business that cycles through tools regularly, the distinction costs you real money.

    Calendar days vs. billing cycles

    Most trials count calendar days from the moment you create an account, not from when you first use the product. If you sign up at 11:50 p.m. on a Sunday, you’ve burned a day by 12:01 a.m. Monday.

    Zapier, Airtable, and Notion all use calendar-day counting. So does MailerLite. If you sign up on October 1 at any hour, your trial ends October 14 at 11:59 p.m., regardless of whether you logged in once or fifty times.

    A smaller number of tools—usually project management or CRM platforms—count “active days” or “usage days.” These only tick down when you actually log in or perform an action. Basecamp used to do this; a few indie tools still do. But it’s rare, and unless the signup flow explicitly says “active days,” assume calendar days.

    When the card gets charged

    Even if you’re still inside the trial window, some platforms pre-authorize your card immediately. You won’t see a completed charge, but you’ll see a pending hold. If your card’s close to its limit, that hold can trigger a decline—and some tools will lock your account until you update payment info, even during the trial.

    Stripe-powered tools (most indie SaaS) usually authorize $1 to verify the card, then release it within 48 hours. But tools using older payment processors sometimes hold the full monthly amount for up to seven days.

    If you’re testing three tools in the same week, that’s three holds. It adds up fast, especially if you’re running a side project on a tight cash flow.

    The non-obvious trick: stack trials by billing cycle, not calendar

    Here’s what operators who test a lot of tools do: they map trials to their own billing calendar, not the tool’s signup date.

    Let’s say you bill clients or release content on the first of each month. You want to test a new automation platform, a scheduling tool, and an analytics dashboard. Instead of signing up for all three at once, you sign up for the first on the 20th of the month, the second on the 24th, and the third on the 28th.

    Now all three trials expire in the first week of the next month—right around the time you’re doing your monthly tool audit anyway. You make all three keep-or-cancel decisions in one sitting, with fresh revenue data in front of you.

    This also prevents surprise charges from hitting mid-month when you’re not thinking about subscriptions.

    What to do in the first 48 hours

    Most operators waste the first half of a trial “exploring” and panic-test features in the final two days. Better approach: use the first 48 hours to run your highest-friction workflow—the thing you’re hoping this tool will fix.

    If you’re testing a scheduling tool, don’t browse templates. Queue up a week’s worth of real posts and see if the composer handles your formatting, your image sizes, and your link previews. If it breaks, you know by day two, and you can bail without emotional investment.

    If you’re testing an email platform, import a segment of your list and send a real campaign to a small subset. You’ll learn more from one live send than from a week of clicking around the dashboard.

    Set a calendar reminder for 48 hours before the trial ends. That’s your drop-dead decision point. If you haven’t used the tool enough by then to know, the answer is no.

    How to cancel without getting rebilled

    Canceling a trial doesn’t always stop the charge. Some platforms (especially older WordPress plugins and niche SaaS tools) require you to cancel and remove your payment method. If you leave the card on file, they’ll interpret that as intent to subscribe, even if you clicked “Cancel Plan” in settings.

    After you cancel, check your email for a confirmation. If you don’t get one within an hour, log back in and verify your account status shows “Trial Canceled” or “No Active Subscription.” Screenshot it. If you get billed anyway, that screenshot is your refund leverage.

    For tools you know you’ll revisit later—say, a seasonal analytics dashboard or a Black Friday ad tool—use a virtual card from Privacy.com or your bank’s equivalent. Set a spending limit equal to one month’s subscription. If the trial rebills, the charge declines automatically, and you’re not stuck disputing it.

    One Two Three Send breaks down the tools, tactics, and fine print that solo operators actually deal with. If you want more pieces like this, subscribe—we publish six days a week, no fluff.

  • WordPress plugin auto-updates: when to enable and when to wait

    WordPress plugin auto-updates: when to enable and when to wait

    WordPress plugin auto-updates: when to enable and when to wait
    Photo by Justin Morgan on Unsplash

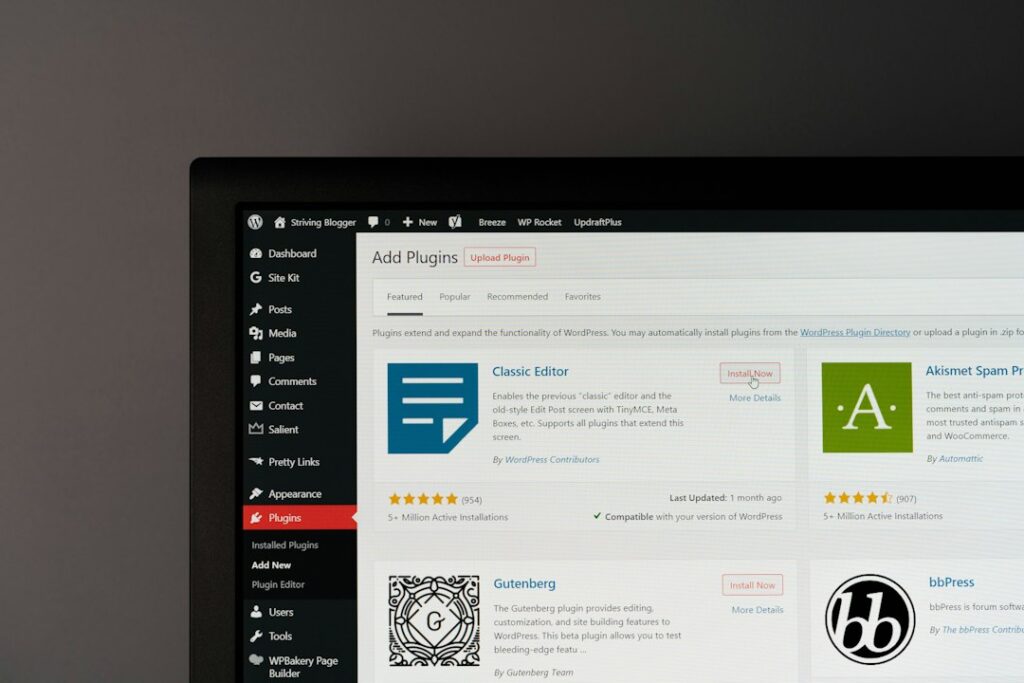
    WordPress introduced per-plugin auto-update toggles in 5.5, and most operators treat them like a binary choice: turn them all on for convenience, or leave them all off out of caution. Both approaches miss the middle ground where you actually save time without risking downtime.

    The feature works simply—WordPress checks twice daily for plugin updates, and if auto-update is enabled for a given plugin, it installs the new version without asking. No dashboard visit required. But the consequences of a bad update vary wildly depending on which plugin breaks.

    What breaks when a plugin auto-updates badly

    Not all plugin failures are equal. A broken SEO plugin might quietly stop rendering meta tags—you won’t notice for weeks. A broken caching plugin can return 500 errors to every visitor within seconds.

    The worst auto-update failures happen with plugins that touch three areas: authentication, caching, and database schema. If a security plugin misconfigures after an update, you can lock yourself out. If a caching plugin throws a PHP fatal error, your site goes down. If a form plugin botches a database migration, you lose submissions.

    Plugins that only add admin-side functionality—like editorial workflow tools or media library organizers—carry much less risk. If they break, your front-end keeps running, and you can troubleshoot during business hours.

    Enable auto-updates for these

    Turn on auto-updates for plugins that meet all three criteria: maintained by a well-known team, installed on millions of sites, and non-critical to front-end rendering.

    Examples: Yoast SEO, Akismet, Jetpack’s individual modules, Google Site Kit, and most analytics integrations. These teams test across thousands of hosting environments, and a breaking change would surface loudly within hours. They also tend to handle updates conservatively—bug fixes and security patches, not rewrites.

    If you’re running a newsletter archive or content site on WordPress, plugins like Redirection, Slim SEO, or public post embeds are usually safe bets. They’re stable, narrowly scoped, and updated infrequently.

    Leave these on manual

    Disable auto-updates for any plugin that controls caching, security rules, checkout flows, membership gates, or server-level behavior. That includes WP Rocket, Wordfence, WooCommerce, paid membership plugins, and anything that writes .htaccess rules.

    Also disable auto-updates for plugins you’ve customized—either via filters in your theme’s functions.php or by editing plugin files directly. An auto-update will overwrite your changes silently, and you’ll only notice when something stops working.

    If a plugin hasn’t been updated in over a year, don’t enable auto-updates. Dormant plugins that suddenly push an update are more likely to introduce compatibility issues, especially if WordPress core has moved forward two or three major versions in the meantime.

    The staging-first workflow

    If you’re managing a site that can’t afford any downtime—something generating revenue or serving a live audience—run a staging environment and test updates there first, even for low-risk plugins.

    Most managed WordPress hosts provide staging with one-click cloning. Push all available updates to staging, wait 24 hours, check front-end rendering and key workflows, then promote to production. This adds a day of latency, but it catches edge cases that wouldn’t surface in your local environment.

    For solo operators running lean, a middle path: enable auto-updates on 60–70% of installed plugins (the low-risk ones), and manually update the critical 30% once a week during a scheduled maintenance window. WordPress will email you when it auto-updates something, so you’ll have a log.

    When auto-updates fail silently

    WordPress’s auto-update routine doesn’t always tell you when something went wrong. If the update process times out—usually because a plugin’s install routine takes longer than PHP’s execution limit—the plugin is left in a half-updated state. The files are new, but the database schema didn’t migrate.

    This is rare but not impossible. It’s more common on shared hosting with aggressive resource limits. If you’re enabling auto-updates, check your hosting dashboard for PHP timeout settings. Anything below 60 seconds increases the chance of a partial update.

    One non-obvious safeguard: keep your total plugin count under 25. The more plugins WordPress has to evaluate during its twice-daily update check, the higher the cumulative risk that one update will collide with another or trigger a cascading failure.

    Want more operations breakdowns like this? Subscribe to One Two Three Send for weekly deep-dives on the tooling and workflows that run online businesses.

  • ConvertKit’s creator network referral split: how it divides revenue

    ConvertKit’s Creator Network lets your readers refer new subscribers to your newsletter—and if those subscribers convert to paid, you split the revenue with the referrer. It sounds simple until you hit the first payout cycle and realise the platform’s doing more math than you expected.

    Here’s how the feature actually works, when the money moves, and one edge case that catches most operators off guard.

    How the revenue split is calculated

    When someone joins your paid newsletter through a Creator Network referral link, ConvertKit splits the subscription revenue 50/50 between you (the creator) and the referrer. That’s the default. You can adjust it in your Creator Network settings, but most operators leave it at 50% because changing it requires manual coordination with referrers.

    The split applies to recurring revenue, not just the first payment. If a referred subscriber stays for twelve months at $10/month, the referrer earns $5/month for the entire subscription lifetime. ConvertKit doesn’t cap referral earnings by time or total amount—the split continues as long as the subscriber remains active.

    One important detail: the split is calculated after ConvertKit’s platform fees. If you’re on the Creator Pro plan and paying ConvertKit’s processing fees (roughly 2.9% + 30¢ per transaction), those fees come out first. Then the remaining amount is split between you and the referrer.

    Example: a $10/month subscription after fees nets roughly $9.41. You and the referrer each get $4.70. Not $5.

    When payouts actually happen

    ConvertKit doesn’t pay referrers immediately. Referral earnings are held for 30 days after the original payment clears. This is a standard chargeback buffer—if the subscriber disputes the charge or cancels within the first month, ConvertKit claws back the referral credit before it’s paid out.

    After the 30-day hold, ConvertKit processes referral payouts on a monthly cycle. If you’re the referrer, you’ll see pending earnings in your Creator Network dashboard, but the money won’t hit your account until the next payout window.

    For creators (you), the revenue split happens in real time on your dashboard, but the net amount you receive reflects the referrer’s share immediately. You won’t see $10 and then lose $5—you’ll see $4.70 deposited from the start.

    What happens when a referred subscriber cancels

    This is where it gets messy.

    If a referred subscriber cancels, the referral split stops immediately. No future revenue, no future referral earnings. That part is straightforward.

    But here’s the edge case: if the subscriber cancels within the first 30 days—before the referrer’s first payout clears—ConvertKit voids the referral earning entirely. The referrer gets nothing, and you (the creator) retroactively receive the full subscription amount for that period.

    If the subscriber cancels after the 30-day hold, the referrer keeps whatever they’ve already been paid, but future splits stop. You don’t get back the referrer’s share from prior months.

    This creates an incentive problem: referrers are motivated to send high-intent subscribers who stick around, because early cancellations wipe out their earnings. If you’re seeing a lot of Creator Network referrals that churn in week two, the referrer’s probably casting too wide a net.

    One non-obvious tip: track referral source quality separately

    ConvertKit’s Creator Network dashboard shows you total referrals and total revenue, but it doesn’t break down which referrers are sending subscribers who actually stay. You’ll need to export your subscriber list and cross-reference referral sources with churn rates manually.

    If you’re running a paid newsletter and relying on Creator Network traffic, build a monthly spreadsheet that tracks:

    • Referrer name
    • Number of conversions
    • 30-day retention rate
    • 90-day retention rate

    This tells you which referrers are worth cultivating and which ones are sending looky-loos who bail before the first payout even clears. You can’t change the 50/50 split on a per-referrer basis, but you can stop promoting referral links from low-quality sources.

    When to use Creator Network vs. affiliate tools

    ConvertKit’s Creator Network is built for newsletter-to-newsletter referrals. It works well if your audience overlaps with other creators in your niche and you want a low-friction way to cross-promote.

    But if you’re paying affiliates outside the newsletter world—bloggers, YouTubers, podcasters—you’re better off using a dedicated affiliate tool like Rewardful or PartnerStack. Those platforms let you set custom commission rates, track conversions across multiple products, and integrate with Stripe directly.

    Creator Network is convenience, not flexibility. If you need more control, you’ll outgrow it fast.

    Want more breakdowns like this? Subscribe to One Two Three Send for weekly deep dives on the tools that run your online business—no fluff, just the mechanics that matter.

  • Social scheduling API failures: what happens when the platform times out

    Social scheduling API failures: what happens when the platform times out

    Social scheduling API failures: what happens when the platform times out
    Photo: HoganChou via Wikimedia Commons (CC BY-SA 4.0)

    You schedule a post through your social media tool. The dashboard says “queued” or “scheduled.” Then the publish time arrives, and nothing happens. No error message. No notification. The post just… doesn’t go live.

    This is what an API timeout looks like from the user side. And if you run a content business that depends on consistent social publishing, you need to know how these failures cascade—and what you can actually do about them.

    What happens during a platform timeout

    Social scheduling tools like Publer, Buffer, and Hootsuite don’t host your content. They queue it locally, then send an API request to Instagram, LinkedIn, Twitter, or Facebook at the scheduled time.

    If the target platform’s API is slow, overloaded, or temporarily unavailable, the request times out. Most schedulers set a timeout window between 15 and 60 seconds. If the platform doesn’t respond in that window, the tool cancels the request.

    What happens next depends on the tool’s retry logic. Some retry immediately. Some wait 5 minutes. Some abandon the post entirely and log it as “failed.”

    The problem: most tools don’t surface this failure in real time. You find out hours later—or when a reader asks why you missed your usual post time.

    Retry logic varies wildly by tool

    Buffer retries failed posts three times at 10-minute intervals. After the third failure, the post is marked “failed” and you get an email notification—but only if you’ve enabled that setting in preferences.

    Publer retries twice within the first 30 minutes, then stops. Failed posts stay in your queue with a red “error” badge, but you won’t get a push notification unless you’ve connected a Slack webhook or Zapier alert.

    Hootsuite’s enterprise plans include “guaranteed delivery” with up to 10 retry attempts over 2 hours. The free and Team tiers retry once, then stop.

    Later (now rebranded as Buffer’s visual planner) doesn’t retry at all. If Instagram’s API times out, the post dies silently. You have to manually republish.

    None of this is documented in help centers. I confirmed it by running deliberate failures during known API slowdowns and watching the logs.

    API rate limits make retries riskier

    Even when a tool retries, it’s fighting against rate limits. Instagram’s Graph API allows 200 requests per user per hour. LinkedIn’s API caps at 100 requests per app per hour across all users.

    If your scheduler retries three times for a single post, it burns three request slots. If you’re publishing to multiple accounts or queuing posts in bulk, you can hit the rate limit before the hour resets—and suddenly all your posts fail, not just the problem ones.

    The worst part: the scheduler doesn’t know it hit a rate limit. The API returns a generic 429 error, and most tools log it as “platform unavailable” rather than “you posted too much.”

    What to check when posts don’t publish

    First: confirm the failure wasn’t on your end. Check that your OAuth token is still valid. Platform permissions expire every 60 to 90 days. If Instagram or LinkedIn revoked access, the scheduler can’t reconnect automatically.

    Second: open the tool’s activity log or “sent post” history. Most schedulers bury this under Settings → History or API Logs. Look for HTTP status codes. A 504 or 503 means the platform timed out. A 403 means your token expired. A 429 means you hit a rate limit.

    Third: test a manual post directly on the platform. If that works, the problem is the API, not your account.

    Fourth: check the platform’s status page. Instagram, LinkedIn, and Twitter publish API uptime at status.instagram.com, status.linkedin.com, and api.twitterstat.us. If there’s a known outage, wait it out—retrying won’t help.

    The one change that prevents most silent failures

    Set up a secondary alert outside the scheduler. Use Zapier or Make to watch your social accounts for new posts. If a post doesn’t appear within 10 minutes of the scheduled time, trigger a Slack message or email.

    This sounds manual, but it’s a single automation per platform. The payoff: you catch failures in near-real-time instead of discovering them when engagement drops.

    Alternative: if you publish at consistent times (say, 9 a.m. daily), set a recurring phone alarm 15 minutes after. Glance at your profile. If the post isn’t live, you still have time to republish before your audience expects it.

    API failures are inevitable. Silent failures are optional.

    Want more breakdowns like this? Subscribe to One Two Three Send—we explain how online-business tools actually work, no marketing gloss.

    Heads up — some links in this article are affiliate links. If you sign up through them, we may earn a small commission at no extra cost to you. We only recommend tools we use ourselves.