Author: onetwothreeadmin

  • Canva’s Brand Kit feature: when centralised assets save more time than templates

    Canva’s Brand Kit feature: when centralised assets save more time than templates

    Canva's Brand Kit feature: when centralised assets save more time than templates
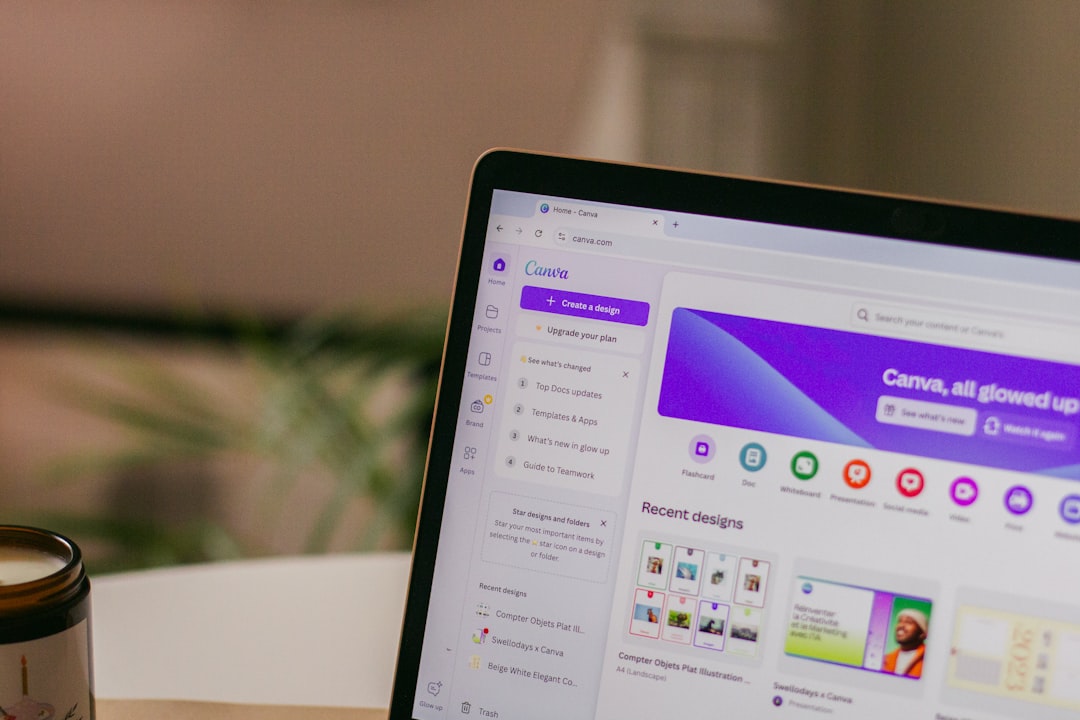
    Photo by Swello on Unsplash

    Most solo operators treat Canva like a template library. You find a design you like, swap in your text and images, export, and move on. But once you’re creating social graphics, lead magnets, and course slides every week, the template-first workflow breaks down—you’re re-entering hex codes, re-uploading logos, and hunting for that one font name you used last month.

    Canva’s Brand Kit feature solves this by centralising your visual identity in one place. Every colour, font, and logo you define in the Brand Kit syncs across all your designs. Change your primary colour once, and it updates everywhere. Upload a new logo version, and it’s available in every project without re-uploading.

    It sounds simple, but the time savings compound faster than most operators expect—and there are a few non-obvious quirks worth knowing before you commit your entire visual system to it.

    What Brand Kit actually stores

    Brand Kit isn’t just a folder. It’s a structured data layer that Canva injects into every design canvas you open. Specifically, it holds:

    • Colour palette — up to 12 colours on the free plan, unlimited on Pro. These appear as swatches in every colour picker.
    • Fonts — up to 3 font pairings (headline + body) on free, unlimited on Pro. Canva auto-suggests these when you add text boxes.
    • Logos — up to 3 logo files on free, 50+ on Pro. They appear in a dedicated “Your logos” panel, separate from your generic uploads.

    The key difference: Brand Kit assets are persistent across sessions and devices. Your uploaded images sit in your “Uploads” folder and can get buried. Brand Kit assets are always one click away, in the same spot, every time.

    When Brand Kit beats templates

    Templates are great for one-off designs or exploring new layouts. But if you’re running a content operation—weekly newsletters, daily social posts, monthly lead magnets—Brand Kit becomes the faster option once you cross a threshold:

    You’re creating 5+ designs per week. At that cadence, manually applying your brand colours and fonts wastes 2–3 minutes per design. Over a month, that’s an hour. Over a year, it’s 12+ hours of copy-pasting hex codes.

    You’re repurposing content across formats. If you turn a blog post into a carousel, an email header, and a Pinterest pin, Brand Kit ensures all three use the exact same blue (#2E5BFF, not #2E5CFF). Templates don’t enforce consistency—Brand Kit does.

    You rebrand or iterate your visual identity. Change your primary colour in Brand Kit, and every design you open from that point forward uses the new value. Templates don’t update retroactively—you’d need to manually edit every saved template file.

    The sync quirks nobody mentions

    Brand Kit syncs forward, not backward. If you update a colour in your Brand Kit, it won’t auto-update designs you’ve already published. You’ll need to re-open each old design, click the colour swatch, and re-apply the updated palette. This isn’t automatic.

    Font syncing is even less intuitive. If you remove a font from your Brand Kit, designs that used it will still render—but the font picker will stop suggesting it. If you then open that old design on a device where the font isn’t cached, Canva will substitute a fallback (usually Inter or Roboto). The result: your archived Instagram posts suddenly have the wrong typeface.

    Logo uploads have a resolution ceiling. Canva compresses uploads over 25 MB, and even on Pro, logo files over 100 MB will fail silently. If you’re working with print-quality vector files, export a web-optimised PNG or SVG at 2x your largest canvas size (usually 2000–3000px wide) before uploading.

    One non-obvious tip: use Brand Kit as a design system, not a brand bible

    Most operators set up Brand Kit once and never touch it. Better approach: treat it as a working palette that evolves with your content. If you’re testing a new accent colour for CTA buttons, add it to your Brand Kit temporarily. If it works, keep it. If not, remove it. The kit should reflect what you’re actually using in production, not what you decided in a brand workshop two years ago.

    One useful workflow: create a “seasonal” or “campaign” colour slot in your palette. Rotate it every quarter. This keeps your designs feeling fresh without requiring a full rebrand, and it gives you permission to experiment within a constrained system.

    If you’re creating more than a handful of designs per week, spend 10 minutes setting up your Brand Kit properly. Define your core colours, lock in your fonts, and upload logo variants (horizontal, stacked, icon-only). The upfront setup pays back in saved clicks within a month—and in visual consistency for as long as you keep publishing.

    Want more tool breakdowns like this? Subscribe to One Two Three Send for weekly deep-dives on the software solo operators actually use—no fluff, just the features that matter.
  • Most subscription forms ask for too much data—here’s the cutoff

    Most subscription forms ask for too much data—here’s the cutoff

    Most subscription forms ask for too much data—here's the cutoff

    Every field you add to a subscription form costs you subscribers. The question isn’t whether that’s true—it’s how much it costs, and whether the data you collect is worth it.

    Most operators inherit form designs from platforms or copy what they see elsewhere. They ask for first name, last name, company, role, and sometimes more. Then they wonder why their landing page converts at 2% when competitors hit 8%.

    The math is simple: each additional field drops conversion by 10–25%, depending on placement and perceived friction. A three-field form converts 30–40% worse than a single-field form. If you’re getting 1,000 visitors a month, that’s the difference between 80 subscribers and 40.

    What to collect upfront

    Email address. That’s it for most operators.

    If you run a B2B newsletter where segmentation drives your entire content strategy—industry-specific tips, role-based workflows—then one additional field makes sense. A dropdown for industry or job function. Not both.

    First name feels harmless, but it’s still friction. If you’re using it only for personalization in the welcome email, test a version without it. Many operators find the conversion lift from removing it outweighs the marginal engagement bump from “Hi Sarah” instead of “Hi there.”

    Behavioral segmentation beats form segmentation. You can infer interest from what someone clicks, downloads, or reads. You can’t infer it from a dropdown they picked to get past your gate.

    What to ask later—and when

    Once someone’s subscribed, you have permission to ask more. But timing matters.

    The best window is 7–14 days after signup, once they’ve opened two or three emails and decided your content is worth keeping. Send a one-question survey: “What’s your biggest challenge with [topic]?” or “What type of content do you want more of?”

    Don’t embed the survey in the email. Link to a single-question form—Tally, Typeform, or a plain Google Form. Keep it to one question. Multi-question surveys in this context get 15–20% completion; single-question surveys get 40–60%.

    Use progressive profiling if your platform supports it. Beehiiv, ConvertKit, and Brevo all let you show different questions to subscribers based on what you already know. If someone clicked three AI-tools posts, you don’t need to ask if they’re interested in AI tools.

    The drop-off math that matters

    Run the numbers for your own funnel. If you’re getting 500 visitors a month to your signup page and converting at 4% with a two-field form, that’s 20 subscribers. Cut it to one field and conversion jumps to 6%—that’s 30 subscribers, a 50% lift.

    If you’re running paid traffic, every field costs you real money. A $10 CPM on 10,000 impressions is $100. If your landing page converts at 3%, you’re paying $3.33 per subscriber. Bump that to 5% and it drops to $2. Over a year, that’s hundreds or thousands of dollars depending on scale.

    Most platforms report form abandonment, but not field-level abandonment. If you want to see where people drop off, use Hotjar or Microsoft Clarity and watch session recordings. You’ll see people type an email, pause at the “Company” field, and leave.

    When more fields make sense

    There are exceptions. If you’re running a high-ticket funnel—consulting, enterprise software, $2,000+ courses—you want friction. A five-field form filters out tire-kickers and signals intent. Your goal isn’t volume; it’s quality.

    If you’re offering a lead magnet that’s segmented by use case—”Download the SaaS pricing guide” vs. “Download the agency pricing guide”—you need to know which one they want. But that’s still one extra field, not three.

    If you’re required to collect consent checkboxes for GDPR or sector-specific compliance, you’re stuck with them. But don’t add more optional fields on top of mandatory ones.

    Test it yourself

    Run a 50/50 split test for two weeks. Clone your signup page, remove every field except email, and send half your traffic to each version. Most email platforms let you A/B test signup forms directly—MailerLite and Beehiiv both support it natively.

    Track conversion rate, not just subscriber count. If your traffic fluctuates week to week, raw numbers will mislead you.

    If you don’t have enough traffic to get statistical significance in two weeks—say, under 200 visitors—run it for a month. Don’t flip-flop based on three days of data.

    Want more breakdowns like this? Subscribe to One Two Three Send and get one operator-focused article every day—no fluff, just the technical details that matter.

    Heads up — some links in this article are affiliate links. If you sign up through them, we may earn a small commission at no extra cost to you. We only recommend tools we use ourselves.

  • ConvertKit vs. Brevo vs. MailerLite: free tier caps and billing surprises

    Most solo operators start with a free email platform tier and assume they’ll upgrade when subscriber count crosses the threshold. Reality: you’ll hit a different limit first—and the platform will lock or bill you before you notice.

    Here’s what actually ends the free ride on three popular platforms, and what you need to watch besides subscriber count.

    ConvertKit: 1,000 subscribers, but sends matter more

    ConvertKit’s free tier caps at 1,000 subscribers. Clean enough. But the real constraint is the broadcast limit: you can send to your entire list once per day. Automations don’t count against this, but any manual broadcast does.

    If you publish daily, you’re fine. If you send a Monday newsletter, a Wednesday product launch, and a Friday recap? You’ll hit the send wall mid-week, and ConvertKit will prompt you to upgrade or wait 24 hours.

    The free tier also strips out advanced reporting. You get open rates and click rates, but no link-level breakdowns, no subscriber timezone data, and no A/B test variants. For most operators under 1,000 subscribers, that’s acceptable. For anyone testing subject lines or running cohort experiments, it’s a blocker.

    Paid plans start at $15/month for up to 300 subscribers (previously $9 in 2024, increased January 2025), then jump in $10–$15 increments as you grow. The 1,001–1,500 bracket costs $29/month. Billing is monthly by default; annual saves roughly 15%.

    Upgrade trigger: You’ll outgrow the single daily send limit before you outgrow 1,000 subscribers—especially if you batch content or run launch sequences.

    Brevo: unlimited contacts, but sends cap at 300/day

    Brevo (formerly Sendinblue) flips the model. The free tier allows unlimited stored contacts but caps you at 300 emails per day. Not 300 per broadcast—300 total sends, across all automations, transactional messages, and campaigns combined.

    If your list is 400 people and you send a single broadcast, you’ll burn your daily budget and leave 100 subscribers undelivered until tomorrow. Brevo queues the remainder automatically, but your “send now” broadcast becomes a two-day trickle.

    This structure works if your list is large but inactive, or if you’re using Brevo primarily for transactional email (order confirmations, password resets) and occasional campaigns. It breaks fast for anyone publishing on a schedule.

    The entry paid tier is $9/month for 5,000 sends. After that, Brevo bills by send volume, not subscriber count: 10,000 sends costs $18/month, 20,000 sends costs $27/month. If you send daily to 2,000 subscribers, you’ll pay for 60,000+ sends per month—around $49/month.

    Upgrade trigger: Daily send volume, not list size. A 500-subscriber list publishing five times a week will need paid access within two weeks.

    MailerLite: 1,000 subscribers, 12,000 emails/month

    MailerLite’s free tier combines both caps: up to 1,000 subscribers and up to 12,000 emails sent per month. That’s roughly 12 sends to your full list, or 3 sends per week if you’re at cap.

    The dual limit is easier to predict than Brevo’s daily throttle, but it penalizes frequent senders. If you publish twice a week and run a 4-email welcome automation, you’ll chew through 10,000+ sends monthly even with 800 subscribers.

    MailerLite’s free tier includes A/B testing (subject line only), basic segmentation, and landing page builders—more than ConvertKit offers for free, less than Brevo’s CRM-adjacent features.

    Paid plans start at $9/month for up to 500 subscribers (increased from $10/month for 1,000 in mid-2025), then scale in $5–$10 steps. The 1,001–1,500 bracket costs $18/month. Billing is monthly; annual plans save 30%, one of the steeper discounts in this category.

    Upgrade trigger: Monthly send volume if you publish frequently, subscriber count if you grow fast but send infrequently.

    What actually forces the upgrade

    Across all three platforms, the advertised subscriber cap rarely matches the real constraint:

    • ConvertKit: broadcast frequency
    • Brevo: daily send ceiling
    • MailerLite: monthly send budget

    If you’re starting out, assume you’ll need paid access once you cross 500 active subscribers and publish more than twice a week. The free tier math breaks earlier than the marketing page suggests.

    One more gotcha: all three platforms count failed sends (hard bounces, spam complaints) toward your monthly or daily limit. A stale list will burn through your budget faster than a clean one.

    If you’re already on a free tier and approaching limits, audit your unengaged segment now. Removing inactive subscribers before you hit the cap can buy you another month or two—and lower your first paid bill when you do upgrade.

    Want more operator-focused breakdowns like this? Subscribe to One Two Three Send for tools, tactics, and pricing reality checks—no fluff, no sponsorships, just what works.

    Heads up — some links in this article are affiliate links. If you sign up through them, we may earn a small commission at no extra cost to you. We only recommend tools we use ourselves.

  • AI model context windows: when to split prompts instead of retrying

    AI model context windows: when to split prompts instead of retrying

    AI model context windows: when to split prompts instead of retrying
    Photo by Google DeepMind on Unsplash

    You paste a 4,000-word article draft into an AI chat window, ask for a structural review, and get an error. Context limit exceeded. You trim the intro, try again—same error. You delete half the body, resubmit, and the model finally responds, but now it’s commenting on a fragment that lacks the setup it needs to give useful feedback.

    This isn’t a token-counting problem. It’s a workflow problem. Most operators treat context overflow as a prompt-editing challenge when the real fix is architectural: split the task before you hit send.

    Context windows aren’t expanding fast enough

    As of mid-2026, Claude offers a 200,000-token context window, GPT-4 variants sit around 128,000, and smaller models cap out between 8,000 and 32,000 tokens. That sounds generous until you realize a 5,000-word blog post with embedded code examples, a style guide, and three rounds of prior conversation can blow past 10,000 tokens before you’ve asked a single question.

    Most operators assume trimming content is the answer. Delete the footer, strip formatting, summarize the intro. But every cut removes signal the model needs to give coherent output. You’re trading context for access, and the result is shallow feedback that ignores nuance.

    The alternative: don’t send everything at once. Design prompts that assume the model will only see part of the material, then stitch outputs together manually or via a second pass.

    When to split instead of trim

    If your input material is longer than 3,000 words or includes multiple discrete sections—like a course outline, a multi-chapter ebook draft, or a batch of social posts—splitting is almost always faster than editing down.

    Here’s the decision heuristic: if the task requires the model to consider the whole document in relation to itself (e.g., “does this argument contradict itself?”), you need the full context or a summarization pre-pass. If the task is parallelizable (e.g., “rewrite each section for clarity”), split by section and process separately.

    Concrete example: I run a weekly tutorial series. Each post is 1,200 words with code blocks. I used to paste the entire draft and ask for tone consistency edits. Half the time, I’d hit the context ceiling after two rounds of back-and-forth. Now I split each post into intro, body, and conclusion, process each separately with a standing instruction (“match the voice in this sample paragraph”), and recombine. Total token spend dropped by 40%, and I stopped seeing mid-edit crashes.

    How to structure split prompts

    Start with a prompt template that works on fragments. Define the task, provide a style anchor (a short reference paragraph), and process each chunk in isolation. If the task requires continuity—like maintaining a thread across sections—add a handoff step: after processing section one, include its output as reference context when you send section two.

    Example template for editing a long article:

    • Prompt 1: “Rewrite this introduction for clarity. Match the tone in this sample: [paste 100-word reference]. Here’s the intro: [paste section].”
    • Prompt 2: “Rewrite this body section. Match tone to this revised intro: [paste output from Prompt 1]. Here’s the body: [paste section].”
    • Prompt 3: “Rewrite this conclusion. Reference these revised sections: [paste outputs]. Here’s the conclusion: [paste section].”

    This approach keeps each prompt under 2,000 tokens, leaves room for multi-turn refinement, and ensures the model sees enough context to stay coherent without choking on overflow.

    The non-obvious cost: manual stitching

    Splitting prompts trades automation for reliability. You’ll spend 3–5 minutes per task copying, pasting, and reassembling outputs. That’s slower than a single-shot prompt when it works—but faster than the retry loop when it doesn’t.

    If you’re processing the same content type repeatedly (like weekly posts, client briefs, or course modules), build a text-expansion snippet or a small script to automate the split-and-recombine step. I use a Mac Automator workflow that splits markdown files by H2, sends each section to Claude via API with a stored prompt template, and writes outputs to separate files. Total setup time: 20 minutes. Time saved per week: 45 minutes.

    One more thing: track where your context budget actually goes. Most overflow happens because earlier conversation turns are still loaded. If you’re five exchanges deep and the model suddenly can’t parse your input, start a new thread instead of trimming content. You’ll keep your material intact and dodge the error entirely.

    Reply with the content type you hit context limits on most often. I’m tracking patterns for a deeper dive on API-based splitting workflows.

    Heads up — some links in this article are affiliate links. If you sign up through them, we may earn a small commission at no extra cost to you. We only recommend tools we use ourselves.

  • WordPress revision limits: when unlimited history breaks your database

    WordPress revision limits: when unlimited history breaks your database

    WordPress revision limits: when unlimited history breaks your database
    Photo: Matinbeigi via Wikimedia Commons (CC BY-SA 4.0)

    WordPress stores every draft change you make as a separate database row. Hit “Save Draft” twenty times while writing a post? That’s twenty revision rows in wp_posts. Multiply that across hundreds of articles, and you’re storing thousands of rows you’ll never open again.

    Most operators don’t notice until their database export takes five minutes instead of thirty seconds, or their backup plugin starts timing out. By then, revisions often account for 40–60% of total database size.

    The revision math

    WordPress defaults to unlimited revisions. A typical blog post might generate 15–25 revisions during drafting and editing. If you publish 100 posts per year, that’s 1,500–2,500 revision rows annually—on top of the 100 published post rows you actually need.

    After three years, a site with 300 published posts might carry 4,500–7,500 revision rows. Each revision duplicates the post content, metadata, and timestamps. A 2,000-word post stored as HTML averages 12–15 KB per revision. Twenty revisions = 240–300 KB of database space for a single article’s edit history.

    Database bloat compounds during backups. Tools like UpdraftPlus or BackupBuddy export the entire wp_posts table. A 300-post site with unlimited revisions can generate 80–120 MB backup files when the live content itself occupies 15–20 MB.

    Setting a sane limit

    Add this line to wp-config.php, above the “stop editing” comment:

    define('WP_POST_REVISIONS', 5);

    Five revisions cover most real-world recovery scenarios. You can roll back a paragraph you deleted an hour ago, compare yesterday’s draft to today’s, or retrieve content after an accidental bulk delete. You won’t need the version from three weeks ago.

    Setting the limit doesn’t delete existing revisions—it only caps future saves. To purge old revisions, install WP-Optimize (free) or run this SQL query directly in phpMyAdmin:

    DELETE FROM wp_posts WHERE post_type = 'revision';

    Test on staging first. The query is irreversible.

    When to keep more revisions

    Multi-author sites benefit from higher limits—10 to 15 revisions—especially when editors frequently revert contributor drafts or compare versions across handoffs. Content sites that publish long-form investigative pieces or data-heavy articles might want a week’s worth of recovery options.

    But solo operators publishing 2–4 posts per week rarely need more than five. The trade-off between database bloat and recovery flexibility tips heavily toward limiting revisions once you pass 200 published posts.

    Autosave vs. revisions

    WordPress autosaves every 60 seconds by default, separate from manual revisions. Each autosave overwrites the previous one—it doesn’t create a new row. Autosaves don’t contribute to bloat, but they do create a recovery point independent of your revision limit.

    If you want to extend the autosave interval to reduce database writes (useful on high-traffic shared hosting), add this to wp-config.php:

    define('AUTOSAVE_INTERVAL', 300);

    That sets autosave to five minutes. Solo operators can safely push this to 180–300 seconds without meaningful risk.

    Monitoring revision bloat

    Run this query in phpMyAdmin to count total revisions:

    SELECT COUNT(*) FROM wp_posts WHERE post_type = 'revision';

    Compare that number to your published post count. If revisions outnumber posts by more than 10:1, you’re carrying dead weight. Purge old revisions, set a limit, and check again in three months.

    Database optimization plugins like WP-Optimize show revision counts in their dashboards and let you schedule monthly cleanups. Set it to keep the five most recent revisions per post and auto-delete the rest. After the first purge, most solo sites drop 30–50% in database size.

    Want more WordPress infrastructure breakdowns like this? Reply and tell me which hosting mystery to unpack next—I read every response.

  • Affiliate cookie windows expire faster than your content stays relevant

    Affiliate cookie windows expire faster than your content stays relevant

    Affiliate cookie windows expire faster than your content stays relevant
    Photo by Patryk Rejdych on Unsplash

    You publish a buyer’s guide in January. Someone clicks your affiliate link, browses for twenty minutes, then closes the tab. Thirty-one days later, they come back through organic search, remember your recommendation, and buy. You earn nothing.

    That’s not a edge case—it’s how most affiliate revenue leaks out of evergreen content strategies. Cookie windows and content lifespan operate on completely different timescales, and most solo operators don’t account for the gap.

    How cookie windows actually work

    An affiliate cookie window is the period between when someone clicks your link and when a sale must occur for you to earn commission. The standard is 30 days. Some programs offer 7 days. A handful—Amazon Associates, for example—give you 24 hours for most categories.

    Once that window closes, the tracking pixel expires. If the buyer returns through any other path (direct URL, branded search, a different affiliate’s link), you’re out. The sale happens, but the attribution is gone.

    This works fine for time-sensitive content: weekly deal roundups, launch coverage, limited-time promotions. A reader clicks, decides quickly, and converts within the window. But it falls apart for evergreen content—comparison posts, tutorial-driven recommendations, long-form buying guides.

    Why evergreen content breaks the model

    Evergreen posts drive traffic for months or years. A single how-to article might get 200 visits in month one, 180 in month six, and 150 in month twelve. Readers arrive at different stages of intent. Some are researching early. Others are ready to buy but want one last confirmation.

    The mismatch: your content stays relevant for eighteen months, but your affiliate window closes in thirty days. A reader who clicks your link in March and buys in April costs you the commission, even though your content directly influenced the decision.

    This isn’t hypothetical. I’ve tracked this across three affiliate-driven sites. Conversion rates on evergreen posts hover around 2–4% in the first 30 days after publish. But buyer behavior data—tracked via UTM parameters and CRM integrations—shows that 18–25% of eventual purchasers return more than 30 days after their first visit.

    The longer your content stays live, the more you lose to expired cookies.

    What actually works

    You can’t extend someone else’s cookie window, but you can adjust strategy to work within it.

    Optimize for high-intent traffic. Evergreen content can target early-stage research (“what is X?”) or late-stage decision-making (“X vs. Y for [specific use case]”). The second group converts faster. If your affiliate window is short, bias your content mix toward comparison posts, feature breakdowns, and use-case-driven recommendations. These attract readers closer to purchase.

    Reactivate older posts with fresh links. Update evergreen articles every 90–120 days. Refresh the intro, add a new example, adjust pricing details—anything that gives you an excuse to re-promote the post via email or social. New clicks = new cookie windows. This works especially well if you’re driving your own email list to older content.

    Layer in shorter-window programs strategically. If you’re reviewing tools with both direct affiliate programs (30–60 day windows) and network aggregators like Impact or ShareASale (often 7–14 days), use the network links only in time-sensitive contexts—launch posts, limited offers, deal alerts. Reserve the longer-window programs for evergreen content.

    Track first-touch attribution separately. Most affiliate dashboards show you last-click conversions. But if you run UTM parameters on your affiliate links and feed them into a simple CRM or Google Sheets via Zapier, you can see how many people clicked, didn’t convert, then returned later via another path. That data won’t earn you retroactive commissions, but it will show you which posts are under-monetized and worth doubling down on with email sequences or retargeting.

    When it’s better to skip affiliates entirely

    If your content is genuinely evergreen—think foundational how-to guides that rank for two-plus years—and your affiliate program uses a 7- or 14-day window, conversion math often doesn’t pencil out. You’re better off monetizing with sponsorships, display ads, or your own product inserts.

    A single sponsored mention in a high-traffic evergreen post can earn $300–$800 upfront, with no dependency on cookie windows or conversion rates. That’s predictable revenue. Affiliate commissions on the same post might trickle in at $40–$120 per month, heavily weighted toward the first 60 days, then taper as cookie expirations compound.

    Run the numbers for your own traffic and conversion rates. If evergreen posts make up more than 60% of your page views and your primary affiliate programs use windows under 21 days, you’re likely leaving money on the table by not diversifying monetization.

    Want more revenue breakdowns like this? Subscribe to One Two Three Send and get operator-focused strategy every week—no fluff, no generic advice.

  • Zapier task history vanishes after 14 days—archive what matters

    Zapier task history vanishes after 14 days—archive what matters

    Zapier task history vanishes after 14 days—archive what matters
    Photo by Adrien Olichon on Unsplash

    Zapier deletes task history after 14 days on the free plan, 30 days on Starter, and only extends to 90 days on Professional and higher tiers. If you’re running automated workflows that process payments, form submissions, or subscriber updates, that data evaporates faster than you think—and you can’t get it back.

    Most solo operators treat Zapier like a fire-and-forget system. A form submission triggers a Zap, the data flows into your CRM or spreadsheet, and you assume it’s logged somewhere permanent. It’s not. The moment Zapier’s retention window closes, the only record of what ran, when it ran, and what data passed through disappears from your dashboard.

    This matters when you’re troubleshooting a workflow three weeks later, reconciling subscriber counts, or trying to trace why a payment notification never fired. Without task history, you’re guessing.

    What gets deleted and when

    Zapier’s task history shows every time a Zap runs: the trigger data, each action step, any filters or formatters in between, and whether the task succeeded or errored. That’s the audit trail. When the retention window expires, all of it vanishes—timestamps, payloads, error messages, everything.

    The retention clock starts the moment a task completes, not when you last looked at it. A Zap that ran on July 1st disappears from your history on July 15th if you’re on the free plan, even if you never opened the task log.

    Error logs disappear on the same schedule. If a Zap failed two weeks ago and you didn’t catch it, the error detail is gone. You’ll see the Zap is turned off or paused, but you won’t know what broke or which record triggered the failure.

    This is especially painful for workflows that run infrequently. A monthly invoicing Zap, a quarterly data export, or a seasonal campaign trigger might execute once and then sit idle. By the time you need to review what happened, the history is already gone.

    How to archive task data before it disappears

    The cleanest fix is to log critical task data to a destination you control. Add a final action step to every high-stakes Zap that writes a record to Google Sheets, Airtable, or a dedicated database. Include the trigger timestamp, the input data, and the result of each key action.

    For payment workflows, log the customer email, the amount, the transaction ID, and the timestamp. For form submissions, log the submission ID, the form fields, and which downstream action fired. For subscriber updates, log the old state, the new state, and the source trigger.

    This adds one extra task to every Zap run, which increases your task count slightly—but it’s worth it. A Google Sheet with six months of task logs is searchable, exportable, and permanent. Zapier’s dashboard isn’t.

    If you’re on a paid plan and running high-volume Zaps, consider a dedicated logging service like Logtail or Papertrail. Zapier supports webhook actions, so you can POST task data to an external log collector that retains it indefinitely. This is overkill for most solo operators, but if you’re processing hundreds of tasks per day across multiple workflows, centralized logging makes troubleshooting faster.

    When retention limits break reconciliation

    Task history limits hit hardest when you’re reconciling data between systems. You notice a mismatch—your CRM shows 1,823 subscribers, but your analytics tool shows 1,807—and you want to trace which records didn’t sync. If the gap opened three weeks ago, Zapier’s history won’t help you.

    The same problem surfaces with payment processors. Stripe shows 42 successful charges in June, but your accounting spreadsheet only logged 40. Without task history, you can’t identify which two transactions failed to trigger the logging Zap, or whether they errored silently.

    Operators who rely on Zapier for mission-critical workflows—subscriber onboarding, payment confirmations, content delivery—need a backup audit trail. If the workflow fails and you don’t catch it within the retention window, you’re reconstructing events from incomplete data.

    What to log and what to skip

    Not every Zap needs external logging. Low-stakes workflows—social media cross-posting, Slack notifications, simple RSS-to-email triggers—don’t justify the extra task overhead. If the worst-case failure is a missed tweet, let Zapier’s native history handle it.

    Focus logging on workflows where failure or data loss has downstream consequences: payment processing, lead capture, subscriber management, content delivery, invoicing, or any workflow that touches money or customer data.

    For these high-stakes Zaps, log enough detail to reconstruct what happened without storing sensitive data unnecessarily. Don’t log full credit card numbers or raw password fields. Log transaction IDs, email addresses, timestamps, and success/failure flags—enough to trace the workflow, not enough to create a security liability.

    If you’re running Zapier on a paid plan solely for the longer task history, calculate whether external logging is cheaper. A Google Sheet is free. Airtable’s free tier handles 1,200 records per base. Both retain data indefinitely. If you’re paying $30/month for Zapier Professional mostly to access 90-day history, you’re overpaying for archival storage.

    Want more workflow breakdowns like this? Subscribe to One Two Three Send for operator-to-operator guides on the tools that actually run your business—no fluff, just the edge cases that matter.

  • Paid social ad budgets below $500/month: when to stop and redirect

    Paid social ad budgets below $500/month: when to stop and redirect

    Paid social ad budgets below $500/month: when to stop and redirect
    Photo by Quilia on Unsplash

    Most solo operators running paid social ads are spending just enough to lose money slowly. Not because the creative is bad or the targeting is wrong—but because platforms like Facebook, Instagram, and LinkedIn need minimum spend thresholds to exit learning phases and deliver stable results.

    If you’re spending under $500 per month on paid social, you’re likely feeding the algorithm without ever reaching the point where it can optimize effectively. Here’s when to pull the plug and put that budget somewhere else.

    Learning phases eat small budgets alive

    Facebook’s ad delivery system enters a “learning phase” every time you launch a new ad set. During this period—typically 50 conversions or about 7 days—the algorithm tests placements, audiences, and delivery patterns. Performance is unstable, cost per result is high, and you’re essentially paying for the platform to figure out what works.

    If your monthly budget is $300 and you’re optimizing for a conversion that costs $15, you’re generating 20 conversions per month. That’s not enough to exit learning on even one ad set, let alone test variants or scale what works. You reset the learning phase every time you tweak creative, adjust targeting, or pause for a few days.

    LinkedIn is worse. The platform recommends a minimum daily budget of $10 per campaign and suggests at least $5,000 in lifetime spend to gather meaningful data. At $400/month, you’re running a single campaign for weeks without enough signal to know if your targeting is directionally correct.

    Platform minimums and daily spend floors

    Beyond learning phases, each platform enforces daily or lifetime budget minimums that make small budgets impractical:

    • Facebook/Instagram: $1/day minimum per ad set, but realistic delivery starts around $5–10/day depending on audience size and objective.
    • LinkedIn: $10/day minimum per campaign. Sponsored Content and Message Ads often require $15–20/day to see consistent delivery.
    • Twitter/X: Minimum $5/day, but impressions taper off fast below $20/day.

    If you’re spending $300/month across two platforms, you’re looking at $5/day per platform—barely clearing minimums, never reaching statistical significance, and constantly restarting learning cycles when budget runs out mid-month.

    When organic or email wins instead

    Below $500/month, your budget is better spent on channels that don’t penalize you for small scale:

    Organic social scheduling and repurposing. A $15/month tool like Publer or Buffer lets you schedule posts across networks, repurpose content into multiple formats, and maintain consistent presence without paying for each impression. You lose paid reach, but you also stop hemorrhaging budget into learning phases that never resolve.

    Email list growth via lead magnets. Put $200/month into a freelance designer for lead magnet PDFs, landing page tweaks, or content upgrades. Pair that with organic promotion and you’re building an owned channel that doesn’t reset when you pause spend. Platforms like MailerLite or Brevo let you grow to 1,000+ subscribers for free or under $15/month, and every subscriber you add compounds over time.

    Low-cost traffic tests via solo ads or newsletter sponsorships. If you need paid traffic and have a tight budget, solo ads in your niche (typically $0.30–0.70 per click) or small newsletter sponsorships ($50–150 per placement) give you fixed-cost exposure without algorithmic gatekeeping. You know exactly what you’re paying per visitor, and there’s no learning phase tax.

    The breakpoint: $500/month, single platform, single objective

    If you’re committed to paid social, here’s the minimum viable threshold:

    • $500+/month on one platform (not split across three)
    • One conversion objective (not awareness + traffic + conversions in parallel)
    • At least 50 conversions per month to exit and re-enter learning without burning budget

    Below that, you’re paying for noise. The algorithm can’t learn, you can’t test, and your cost per result stays artificially high because the platform never stabilizes delivery.

    Run the math on your last 90 days. If your monthly spend averages under $500 and you’re not seeing consistent cost-per-result improvements month over month, pull the budget. Redirect it to owned channels, test organic tactics for 60 days, and return to paid social only when you have the budget to clear learning phases without restarting every week.

    Reply with your current monthly paid social spend and conversion count—I’ll tell you if you’re above or below the threshold where the algorithm can actually work.

    Heads up — some links in this article are affiliate links. If you sign up through them, we may earn a small commission at no extra cost to you. We only recommend tools we use ourselves.

  • Google Analytics 4 event parameters: which ones actually fire

    Google Analytics 4 event parameters: which ones actually fire

    Google Analytics 4 event parameters: which ones actually fire
    Photo: Ajiro Shinpei via Wikimedia Commons (CC BY-SA 4.0)

    Google Analytics 4 lets you attach up to 25 custom parameters to each event. That sounds generous until you realize that half of them might never show up in your reports—and the platform won’t tell you which ones got dropped until you go looking.

    If you’re running a content business and relying on GA4 to track subscriber behavior, link clicks, or content engagement, this matters more than you think. Parameters that don’t fire mean attribution you can’t trace and conversion paths you can’t rebuild.

    Why parameters get dropped

    GA4 has three silent filters that strip parameters before they hit your data stream:

    Character limits. Parameter names max out at 40 characters. Values cap at 100 characters. Cross either threshold and the entire parameter vanishes. No error message, no warning in the real-time view—it just doesn’t arrive.

    Reserved parameter names. GA4 reserves roughly 50 parameter names for its own use. If you accidentally name a custom parameter something like page_location, session_id, or user_id, your value gets overwritten by GA4’s automatic collection. The list isn’t published in one place; you have to cross-reference the automatically collected events documentation to catch conflicts.

    Data type mismatches. GA4 infers parameter types from the first value it sees. If your first event sends article_id as a string and the second sends it as an integer, one of them won’t register as a custom dimension. The platform doesn’t reconcile types retroactively, so you’re left with partial data and no alert.

    How to audit what’s actually firing

    Most operators check the real-time report and assume everything’s working. That view only shows the last 30 minutes and doesn’t surface parameter-level failures.

    The better approach: open the DebugView panel in GA4. It requires enabling debug mode in your Google Tag Manager container or adding ?debug_mode=true to your site URL if you’re using gtag.js directly. DebugView shows every event and parameter as it arrives, including which ones GA4 accepted and which ones it ignored.

    Run a test session where you trigger each custom event you care about—newsletter signups, affiliate link clicks, content unlocks, purchase completions. Watch the parameter list for each event. If a parameter you sent isn’t listed, it got dropped.

    Once you know which parameters aren’t firing, check their names against the reserved list, confirm their character counts, and verify that your tag configuration isn’t sending mixed data types.

    When to use event-scoped vs. user-scoped parameters

    GA4 parameters come in two flavors: event-scoped and user-scoped. Event-scoped parameters attach to individual actions—link_url, video_title, form_id. User-scoped parameters attach to the visitor across sessions—subscription_tier, signup_source, customer_ltv.

    The distinction matters because GA4 limits you to 50 custom event-scoped dimensions and 25 custom user-scoped dimensions per property. If you’re tracking a membership site or a newsletter with multiple tiers, user-scoped parameters let you segment reports without burning through event slots.

    But user-scoped parameters don’t populate immediately. GA4 only attaches them after the first event in a session fires. If you need to filter reports by subscription_tier and a visitor’s first event is a page view, the tier parameter won’t be available until the second event. That creates reporting gaps if you’re trying to attribute conversions by tier.

    The workaround: send a silent user_properties_set event on page load with all your user-scoped parameters, then fire your standard events afterward. It’s an extra event in your tag setup, but it ensures parameters are available from the first interaction.

    One non-obvious fix

    If you’re sending parameters through Google Tag Manager and they’re still not showing up in GA4, check your tag’s Fields to Set configuration. GA4 tags in GTM have two places to define parameters: the “Event Parameters” section and the “Fields to Set” section. Event parameters go to GA4. Fields to Set go to the Google tag itself and don’t always pass through to GA4 reports.

    Most operators fill out Fields to Set by mistake and wonder why their custom dimensions stay empty. Move everything to Event Parameters unless you’re explicitly configuring a Google Ads conversion tag.

    If you’re running attribution reporting across multiple tools—GA4, your newsletter platform, and a course LMS—make sure your parameter names stay consistent. GA4 doesn’t auto-map source to utm_source or email to user_email. Pick a naming convention and enforce it across every tag, webhook, and API call.

    Want more breakdowns like this? Reply with the analytics setup you’re trying to debug—I’ll cover it in a future issue.

  • WordPress database character set conversion: when emoji breaks old posts

    WordPress database character set conversion: when emoji breaks old posts

    WordPress database character set conversion: when emoji breaks old posts
    Photo by Markus Winkler on Unsplash

    Most WordPress sites installed before 2015 run on a latin1 character set. That was fine until emoji, non-Latin scripts, and special characters became standard in content. The fix is converting to utf8mb4, the MySQL character set that supports the full Unicode range. But the migration isn’t one-click safe, and operators who skip the collation audit often find mangled text in old posts weeks later.

    Why utf8mb4 matters now

    WordPress has shipped with utf8mb4 as the default character set since version 4.2 in 2015. If your database predates that, or if your host used an older MySQL template during setup, you’re likely still on latin1 or the older three-byte utf8 encoding.

    The three-byte utf8 can’t store emoji, many Asian characters, or mathematical symbols. If a reader pastes an emoji into a comment form or you copy-paste content from a doc that includes a smart quote outside the latin1 range, MySQL either rejects the insert or converts the character to a question mark.

    utf8mb4 uses four bytes per character and covers the entire Unicode standard. That means emoji, CJK ideographs, and symbols render correctly and survive round-trip edits in the WordPress editor.

    The collation mismatch that breaks content

    Character set defines which characters MySQL can store. Collation defines how MySQL compares and sorts them. When you convert a database from latin1 to utf8mb4, you also change the collation—typically from latin1_swedish_ci to utf8mb4_unicode_ci or utf8mb4_general_ci.

    If your existing content contains extended ASCII characters—curly quotes, em dashes, accented letters—and those were stored as latin1 bytes, a straight conversion can misinterpret them. MySQL reads the old byte sequence as if it were already utf8mb4, producing garbled output: “don’t” instead of “don’t.”

    This happens because the byte 0x92 in latin1 (right single quotation mark) has a different meaning in utf8mb4. The conversion tool changes the schema but doesn’t transcode the data unless explicitly told to.

    How to convert without breaking old posts

    The WordPress database charset converter in wp-admin → Tools → Database (added in WP 4.2) handles most cases, but it only appears if WordPress detects a charset mismatch. If the tool doesn’t show, your database and wp-config.php already match, or your host disabled the feature.

    For manual conversion, use the WP-CLI command:
    wp db convert-charset utf8mb4

    This command checks each table, converts the schema, and attempts to recode existing data. But it can’t fix data that was already double-encoded or incorrectly inserted under the old charset.

    Before you run any conversion:

    • Export a full database backup via phpMyAdmin or your host’s backup tool.
    • Check your MySQL version. utf8mb4 requires MySQL 5.5.3 or later; most hosts are on 8.0+ now, but confirm.
    • Run a test query to identify problem rows:
      SELECT post_title, post_content FROM wp_posts WHERE post_content LIKE '%â€%' LIMIT 20;
      If you see garbled characters, your data is already mis-encoded and needs a two-step fix.

    If you find corrupted rows, you’ll need to convert from the actual source encoding. Many databases labeled latin1 were silently storing utf8 bytes. In that case, convert from utf8 to utf8mb4, not latin1 to utf8mb4. Tools like mysqldump with the --default-character-set flag let you specify the real source encoding.

    What breaks after conversion

    Index length limits are the most common post-conversion issue. utf8mb4 uses four bytes per character, so a VARCHAR(255) index that worked under latin1 (255 bytes) now requires 1,020 bytes (255 × 4). MySQL’s default InnoDB index prefix limit is 767 bytes on older configurations.

    If you hit this during conversion, you’ll see:
    ERROR 1071 (42000): Specified key was too long; max key length is 767 bytes

    The fix: enable innodb_large_prefix and set innodb_file_format=Barracuda in your MySQL config, or shorten the indexed column. Most modern managed WordPress hosts (including BigScoots) run MySQL 5.7+ with large prefixes enabled by default, but check if you manage your own VPS.

    Plugins that write custom tables may also need updates. If a plugin creates a table after your conversion, it might default to the old charset unless the plugin explicitly sets utf8mb4 in its schema. Check any membership, LMS, or e-commerce plugins with custom tables.

    When to skip the conversion

    If your site is English-only, has no user-generated content, and you never use emoji or special characters, the conversion won’t break anything—but it also won’t deliver visible value. The character set becomes important when:

    • You accept comments, forum posts, or form submissions from readers
    • You publish multilingual content or quote non-English sources
    • You paste from Google Docs, Notion, or other tools that insert smart quotes and em dashes
    • You use emoji in headlines, CTAs, or social-share snippets

    For solo operators running a single-language blog with no UGC, the status quo works. But if you plan to scale, open comments, or accept guest posts, convert now before you have 500 posts to audit.

    One last thing: After conversion, update your wp-config.php to match. Set:
    define('DB_CHARSET', 'utf8mb4');
    define('DB_COLLATE', 'utf8mb4_unicode_ci');

    Without that, WordPress will keep writing new content in the old charset, and you’ll be back where you started.

    Hit a wall with WordPress hosting performance or database issues? Subscribe to One Two Three Send for operator-focused breakdowns every week—no fluff, just the technical details that matter.