Category: AI Tools

  • AI assistant system prompts: where to store them and when to version

    AI assistant system prompts: where to store them and when to version

    AI assistant system prompts: where to store them and when to version
    Photo by Zulfugar Karimov on Unsplash

    Most solo operators write a good system prompt once, paste it into an AI chat window, get decent output for a week, then watch quality slide. The prompt drifts—small edits pile up, context bloats, and nobody remembers what the original instruction said. Six months later, you’re debugging output without knowing which version of the prompt produced it.

    System prompts deserve the same version control and storage discipline you give code or design assets. Here’s how to store them, when to version, and what breaks when you don’t.

    Store prompts as plain text files, not chat history

    Chat interfaces are ephemeral. Claude, ChatGPT, and other web UIs don’t guarantee indefinite history retention, and searching old threads for “that prompt that worked in July” wastes time. Worse, you can’t diff two versions of a prompt buried in separate chat sessions.

    Store system prompts as .txt or .md files in a dedicated folder. Name them by function: newsletter-intro-rewriter.txt, seo-meta-description.txt, customer-support-tone.txt. Keep them in Dropbox, Google Drive, or—better—a Git repository if you’re comfortable with version control.

    Plain text beats proprietary formats. You can grep, diff, and copy-paste without fighting file locks or platform-specific editors.

    Version prompts when output quality shifts

    Not every tweak needs a new version. If you fix a typo or tighten wording without changing intent, overwrite the file. But version the prompt when:

    • You change the task scope (e.g., adding competitor analysis to a product-description prompt)
    • You adjust tone or output length significantly
    • You switch models or providers (a prompt tuned for GPT-4 may underperform on Claude, and vice versa)
    • You notice output quality degrade and need to roll back

    If you’re using Git, commit with a meaningful message: git commit -m "Tightened newsletter-intro prompt: removed redundant context about audience size". If you’re not using Git, append a date or version number to the filename: newsletter-intro-v2-2026-11.txt.

    Versioning lets you A/B test. Run the same input through two prompt versions, compare output, and keep the winner. Without versions, you’re guessing which change caused the improvement—or the regression.

    Tag prompts with model and temperature settings

    A prompt is only half the recipe. The model, temperature, max tokens, and other parameters matter just as much. Store those settings alongside the prompt text, either in a header comment or a separate metadata file.

    Example header inside newsletter-intro-rewriter.txt:

    # Model: Claude 3.5 Sonnet (checked November 2026)
    # Temperature: 0.7
    # Max tokens: 500
    # Last updated: 2026-11-09
    
    You are an editor for a newsletter about online business tools...

    When output changes unexpectedly, check whether the provider updated the model or shifted default parameters. Claude and OpenAI both version their models; a prompt that worked on gpt-4-0613 may behave differently on a newer snapshot. Tag your prompt with the model identifier, and you’ll know when to retest.

    What breaks when you don’t version

    Three failure modes show up fast:

    Prompt drift. You edit a prompt in-place, forget what you changed, and output quality tanks. Without a prior version, you can’t roll back. You rewrite from scratch, wasting the tuning work you did months ago.

    Inconsistent output across team members. If two people use slightly different versions of the same prompt—one copied from Slack, one from an old email—you get inconsistent tone, structure, or accuracy. Customers notice. A single source of truth fixes this.

    Lost optimisation work. You spend an hour refining a prompt, then close the browser tab. Next week, you start over. Versioned prompts are an asset; unversioned ones are disposable scratch work.

    Tools that help (and their limits)

    Dedicated prompt-management tools exist—PromptLayer, Humanloop, and LangSmith all offer versioning, logging, and comparison features. They’re useful if you’re running prompts at scale via API and need analytics. But most solo operators don’t need the overhead. A folder of text files and basic Git hygiene solves 90% of the problem for free.

    If you’re already using Claude or ChatGPT via API in a script or automation, store prompts as variables in your codebase. That way, version control is automatic—every commit captures prompt and code together. Just avoid hardcoding prompts as long strings; pull them from external files so non-coders can edit without touching code.

    Start simple: one folder, one naming convention

    You don’t need a complex system on day one. Create a folder called prompts, drop in one .txt file per task, and commit to updating the file instead of rewriting in a chat window every time. That alone puts you ahead of most operators.

    When a prompt stops working, duplicate the file, rename it with a version suffix, and edit the new copy. Compare output. Keep the better version. Delete the worse one, or archive it in a prompts/archive subfolder if you think you’ll need it later.

    Versioning matters most for prompts you use weekly. One-off requests don’t need the ceremony. But if you’re generating newsletter intros, product descriptions, or support replies on a regular cadence, treat the prompt like infrastructure. Store it, version it, and document the settings that make it work.

    Got a prompt-management system that works for you? Hit reply and share your setup—we’ll feature the best approaches in a future piece.

    Heads up — some links in this article are affiliate links. If you sign up through them, we may earn a small commission at no extra cost to you. We only recommend tools we use ourselves.
  • AI model context windows: what fits, what gets cut, and when to chunk

    AI model context windows: what fits, what gets cut, and when to chunk

    AI model context windows: what fits, what gets cut, and when to chunk
    Photo: NASA/GSFC/Arizona State University via Wikimedia Commons (Public domain)

    Every AI model has a context window—the maximum amount of text it can process in a single request. Send too much and the model either truncates your input, returns an error, or silently drops the earliest parts of your conversation. For solo operators feeding customer emails, blog drafts, or research notes into an AI assistant, hitting that ceiling means lost context and useless output.

    Understanding how context windows work, what actually counts against them, and when to split your input saves you from re-running failed requests and wondering why the model ignored half your instructions.

    What the context window actually measures

    Context windows are measured in tokens, not characters or words. A token is roughly four characters in English, so a 128,000-token window handles around 96,000 words—but that’s a rough average. Punctuation, code, and non-English text tokenize differently.

    The window includes everything: your system prompt, the user message, any examples you provide, the model’s previous responses in the conversation, and the new response it’s generating. If you’re running a multi-turn chat, earlier exchanges eat into the budget before your latest question even arrives.

    As of November 2026, Claude offers models with context windows up to 200,000 tokens (checked November 2026). OpenAI’s GPT-4 Turbo and GPT-4o support 128,000 tokens (checked November 2026). Smaller models and older versions cap out much lower—sometimes as low as 4,096 tokens.

    When you hit the limit

    Different platforms handle overflow differently. Some models truncate silently from the beginning of the conversation, keeping only the most recent exchanges. Others return an error and refuse to process anything. A few will let you submit the request but deliver incomplete or incoherent output because critical context was dropped mid-thought.

    If you’re pasting a 15,000-word research document and a 500-word prompt into a model with an 8,000-token window, the model will never see your instructions—they’ll be cut first. The API won’t always warn you.

    Check your provider’s documentation for token-counting tools. OpenAI provides a browser-based tokenizer (checked November 2026) that shows exactly how your text gets chunked. Anthropic’s API returns token counts in the response metadata.

    Chunking strategies that preserve meaning

    When your input exceeds the window, split it intelligently rather than chopping at arbitrary character limits. Break on section headings, paragraph boundaries, or logical topic shifts—not mid-sentence.

    Process each chunk separately with the same prompt, then either concatenate the outputs or run a second pass that summarizes the individual results. For long documents, include a brief summary of earlier chunks in each subsequent request so the model maintains continuity.

    Avoid sliding-window approaches where you overlap chunks by 10–20%. They burn tokens on repetition and rarely improve output quality unless you’re doing deep semantic analysis across boundaries.

    If you’re building a retrieval-augmented generation (RAG) system, pre-filter your knowledge base so only relevant excerpts enter the context window. Embedding-based search and vector databases let you pull the five most relevant paragraphs instead of dumping entire articles into the prompt.

    What doesn’t count (and what shouldn’t)

    System prompts and fixed instructions count against the window every time, even if they never change. If you’re running the same 2,000-token system message on every request, you’ve permanently reduced your effective window by 2,000 tokens. Trim boilerplate, combine redundant examples, and move static reference material out of the prompt and into a pre-processed lookup table.

    Formatting tokens add up faster than you expect. JSON scaffolding, XML tags, and markdown syntax all consume budget. If you’re wrapping every data point in verbose markup, you’re trading tokens for structure that the model may not need.

    Model responses count toward the window in multi-turn conversations, so long assistant replies in early turns compress the space available for later exchanges. If you’re running a ten-message chat and the model wrote 1,500 tokens in message three, those tokens reduce what you can send in message eleven.

    When to pay for a bigger window

    Larger context windows cost more per token. Claude‘s extended-context models and OpenAI’s GPT-4 Turbo charge higher per-million-token rates than smaller-window alternatives. If you’re processing hundreds of requests daily, a bigger window might double your API bill without improving output.

    Use a larger window when you genuinely need the model to synthesize across many pages—legal document review, multi-file code analysis, or research summarization. Don’t default to the largest available model for single-question tasks that fit comfortably in 4,000 tokens.

    For high-volume workflows, test whether breaking a 20,000-token job into four 5,000-token chunks and using a cheaper model produces acceptable results. The cost difference often outweighs the minor quality trade-off.

    One thing to try this week: Paste your most common AI prompt into your provider’s token counter and check how much headroom you actually have. If you’re regularly within 10% of the limit, either shrink your input or switch to a model with a bigger window before you start losing context in production.

    Got a question about working with AI tools in your online business? Reply to this email—we answer reader questions every Sunday.

    Heads up — some links in this article are affiliate links. If you sign up through them, we may earn a small commission at no extra cost to you. We only recommend tools we use ourselves.
  • AI prompt libraries: where to store them and when they rot

    AI prompt libraries: where to store them and when they rot

    AI prompt libraries: where to store them and when they rot
    Photo: Ginny from USA via Wikimedia Commons (CC BY-SA 2.0)

    If you run prompts more than twice, you save them. The question is where—and whether you’ll ever find them again when the model changes or the use case drifts.

    Most solo operators start with a Google Doc, graduate to Notion, then scatter prompts across Slack saved messages, browser bookmarks, and a folder called “AI stuff.” Six months later, half the saved prompts fail because the model was updated, the output format changed, or the original context is gone.

    Here’s how to store prompts so they stay useful, and when to retire them before they waste your time.

    Pick one storage method and enforce it

    The best prompt library is the one you’ll actually use. That means low friction and a single source of truth.

    Plain text files in a dedicated folder work for operators comfortable with file browsers. Name each file by use case: email-subject-lines.txt, blog-intro-rewrite.txt. Keep a README with the model name, temperature, and date last tested. Version control with Git if you’re already using it for code; otherwise a Dropbox or Google Drive folder with file history is enough.

    Notion databases let you tag by model, category, and status (active / deprecated / testing). Add a “last verified” date column and filter by it. The search is fast, and you can duplicate a row to test a variation without losing the original.

    Dedicated prompt managers like PromptBase or custom Airtable bases add structure but introduce another tool. Worth it if you’re running dozens of prompts daily; overkill if you have twelve evergreen templates.

    Whatever you pick, the rule is the same: if a prompt isn’t in the library, it doesn’t exist. No exceptions for “just this once” saves in Slack or a scratch pad.

    Tag by model, temperature, and expected output

    A prompt without context is a time bomb. When Claude or GPT-4 updates, your saved prompt might return different lengths, tones, or formats—and you won’t know why until you’ve wasted twenty minutes troubleshooting.

    Store three pieces of metadata with every prompt:

    • Model and version. “Claude Sonnet, October 2026″ or “GPT-4o, November 2026.” If the provider doesn’t version publicly, note the date you saved it.
    • Temperature or sampling setting. A prompt tuned for temperature 0.2 will feel robotic at 0.9. If you’re copy-pasting into a web UI that resets settings, note what worked.
    • Expected output type. “Returns 5 subject lines, ~50 chars each” or “Generates 300-word intro, casual tone.” When output drifts, you’ll know whether the prompt or the model changed.

    Add a “last verified” date and update it every few months. If a prompt hasn’t been tested in six months and the model has updated twice, assume it’s stale.

    When to retire a prompt

    Prompts don’t age well. Models improve, your use case shifts, or you realise the original prompt was solving the wrong problem.

    Retire when the model changes and the output degrades. If a prompt that returned crisp 50-character subject lines now produces 80-character SEO keyword soup, don’t try to fix it with band-aid instructions (“keep it short”). Rewrite from scratch with the new model’s behaviour in mind, or switch models.

    Retire when you stop using it for three months. If a prompt was valuable, you’d be running it. If you haven’t touched it since February, delete it or move it to an archive folder. Clutter kills discoverability.

    Retire when the use case disappears. Prompts tuned for Twitter’s 280-character limit don’t help if you’ve moved to Threads or given up on social entirely. Don’t hoard prompts for workflows you abandoned.

    Mark retired prompts clearly—add “DEPRECATED” to the filename or move them to a separate folder. If you need the logic later, you’ll know where to look, but it won’t pollute your active list.

    Test and version instead of tweaking in place

    When a prompt stops working, the instinct is to edit it and save over the original. Don’t. You’ll lose the baseline and won’t know if the new version is better or just different.

    Duplicate the prompt, rename it with a version suffix (email-subject-v2), and test side by side. Run both on the same input and compare output quality, speed, and cost (if you’re calling via API and tracking tokens).

    If the new version wins, mark the old one deprecated. If it doesn’t, keep the original active and note what you tried in a changelog or comment field. Two months from now, you’ll save yourself from testing the same failed variation twice.

    Prompts are infrastructure, not inspiration. Treat them like code: version them, test them, and delete them when they’re dead weight. The goal isn’t to collect prompts—it’s to run the ones that work without thinking twice.

    Reply with how you store yours—or where they go to die. We’re collecting operator setups for a follow-up piece.

    Heads up — some links in this article are affiliate links. If you sign up through them, we may earn a small commission at no extra cost to you. We only recommend tools we use ourselves.
  • AI assistant rate limits: where requests queue and when they fail

    Rate limits are the invisible fence around every AI API. Cross it and your request gets delayed, rejected, or silently queued. The problem: every provider structures limits differently, and most documentation buries the details three clicks deep.

    If you’re building workflows that lean on AI—content generation, summarisation, customer-reply drafting—you need to know where the throttle sits, how hard it clamps, and what your fallback looks like when the queue fills.

    How AI rate limits are measured

    Most providers set three separate limits: requests per minute (RPM), tokens per minute (TPM), and tokens per day (TPD). Hit any one and you’re blocked until the window resets.

    OpenAI’s GPT-4 models, for example, enforce both RPM and TPM caps that vary by subscription tier. On a free-tier account, you might be capped at 3 RPM and 40,000 TPM (checked November 2026, OpenAI rate limits documentation). Pay-as-you-go accounts on higher tiers get significantly more headroom, but the limits still exist.

    Anthropic’s Claude models use a similar structure but label them differently: message batches, input tokens, and output tokens each have separate ceilings (checked November 2026, Anthropic rate limits guide). If you’re chaining prompts or running batch jobs, you’ll hit the output token limit before the request count.

    Google’s Gemini API publishes per-minute request caps that reset on a rolling window, not a fixed clock boundary—so a burst at 10:59 and another at 11:01 can still trigger a block (checked November 2026, Gemini API quotas).

    What happens when you exceed the limit

    Behavior varies. OpenAI returns a 429 status code and expects your application to retry with exponential backoff. If you don’t handle it, the request just fails.

    Claude queues some requests when you’re near the limit but not over it, then processes them as capacity frees. That sounds helpful until you realise your API call now takes 45 seconds instead of 5, and your user is staring at a spinner.

    Some platforms—particularly those wrapping multiple models under one API—will silently downgrade your request to a cheaper, faster model when the preferred one is rate-limited. You won’t get an error, but you also won’t get the output quality you expected.

    How to structure requests around limits

    If you’re running a workflow that makes more than a handful of AI calls per hour, you need request pacing. The simplest approach: add a fixed delay between calls. Say you’re allowed 60 requests per minute—schedule one every 1.1 seconds and you’ll never hit the wall.

    For batch jobs, split the work into smaller chunks and process them serially instead of firing everything at once. A backlog of 200 summarisation tasks can run overnight without a single retry if you queue them properly.

    If you’re using a no-code automation tool like Zapier or Make, check whether it respects rate-limit headers. Some do; others will hammer the endpoint until it returns an error, then mark the entire task as failed. In that case, you’ll need to add a manual delay action between steps or route requests through a middleware function that handles retries.

    The non-obvious tip: monitor your token budget, not just request count

    Most operators watch request volume and assume they’re safe. Then a single prompt with a 15,000-token context window eats half the daily allowance in one call.

    Track both input and output tokens separately. If you’re generating long-form content, output tokens climb fast—and on tiered pricing, they’re often the expensive half. Set a per-request token ceiling in your application logic so a runaway generation doesn’t blow your quota before lunch.

    Anthropic and OpenAI both return token counts in the API response metadata. Log them. Build a running tally. When you approach 80% of your daily cap, switch to a smaller model or pause non-critical jobs until the window resets.

    Rate limits aren’t advertised as a feature, but they shape how you build. Know the ceiling before you hit your head on it.

    Want more breakdowns like this? Subscribe to One Two Three Send—we explain the mechanics behind the tools you use every week.

    Heads up — some links in this article are affiliate links. If you sign up through them, we may earn a small commission at no extra cost to you. We only recommend tools we use ourselves.
  • AI output length caps: where models stop mid-sentence and why

    AI output length caps: where models stop mid-sentence and why

    AI output length caps: where models stop mid-sentence and why
    Photo by Brecht Corbeel on Unsplash

    You’re two-thirds through a long-form draft when the AI stops mid-paragraph. No warning. No ellipsis. Just a hard stop that leaves you scrambling to prompt “continue” three times in a row—and each continuation drifts further from the original outline.

    Every AI model enforces a maximum output token limit. It’s separate from the context window, rarely mentioned in marketing pages, and almost always smaller than you expect. If you’re generating anything longer than a few hundred words—email sequences, blog posts, product descriptions, tutorial steps—you need to know where that wall is.

    What output limits actually are

    The context window tells you how much input and output a model can handle in total. A model with a 200,000-token context window might only generate 4,096 tokens in a single response. That’s the output cap.

    OpenAI’s GPT-4 models enforce a 4,096-token output limit across most API endpoints, as documented in their model reference (checked October 2026). Anthropic’s Claude models allow up to 8,192 tokens of output for Claude 3.5 Sonnet and Claude 3 Opus, per their models overview (checked October 2026). Google’s Gemini 1.5 Pro supports up to 8,192 output tokens, according to the Gemini API documentation (checked October 2026).

    Four thousand tokens is roughly 3,000 words. Eight thousand is closer to 6,000. If your prompt asks for a 5,000-word guide and you’re using GPT-4, the model will stop partway through—usually without signaling that it hit a limit.

    Why “continue” rarely works cleanly

    The obvious workaround is to type “continue” or “keep going” when the output stops. The model picks up where it left off, right?

    Sometimes. More often, the second chunk shifts tone, drops context from earlier sections, or restarts the same paragraph with slightly different phrasing. That’s because each continuation is a new inference pass. The model sees the prior output as static context, not a live draft it’s editing. If the earlier response pushed close to the output cap, adding it back into the context for the continuation eats tokens fast—and you hit diminishing returns after two or three rounds.

    Stitching together three or four “continue” responses by hand turns a ten-minute task into an hour of editing seams.

    Design prompts around the cap, not against it

    The better approach: structure prompts so each response stays well under the limit, then combine outputs yourself.

    Instead of asking for a full 4,000-word blog post, request an outline first. Then prompt for each section separately: introduction, three body sections, conclusion. Five discrete responses, each 600–800 words, none hitting the cap. You control the handoffs, and the model never has to guess what “continue” means.

    For email sequences, generate one email per prompt. For tutorial steps, one step at a time. For product descriptions across a catalogue, batch by category but keep each response to a dozen items or fewer.

    This also makes it easier to adjust mid-process. If section two goes off-track, you regenerate that section without torching the whole draft.

    Check output limits before you build workflows

    If you’re automating content generation—feeding AI outputs into a CMS, email platform, or publishing queue—test the upper boundary first. Send a prompt that should produce 5,000 tokens and see where it cuts off. Note the model, the endpoint, and the actual token count returned.

    API responses often include metadata showing tokens used. OpenAI’s API returns usage.completion_tokens in the JSON response. Anthropic returns usage.output_tokens. Log those numbers for a week and you’ll see the pattern: most responses stay under 2,000 tokens, but the ones that don’t all stop at the same ceiling.

    Once you know the cap, you can set guardrails. If you’re using an AI writing assistant inside a workflow automation tool, add a step that checks output length and triggers a second prompt when needed—but design that second prompt to pick up a specific section, not just “continue.”

    We’ve started treating output caps the same way we treat email subject-line length or image file size limits: a constraint you design around from the start, not a surprise you debug later.

    Hit a wall with your AI workflows? Reply and tell us which model you’re using and where it stops—we’re tracking patterns for a future breakdown.

    Heads up — some links in this article are affiliate links. If you sign up through them, we may earn a small commission at no extra cost to you. We only recommend tools we use ourselves.
  • AI assistants repeat themselves when you don’t set temperature

    AI assistants repeat themselves when you don’t set temperature

    AI assistants repeat themselves when you don't set temperature
    Photo: Emeka Udenze via Wikimedia Commons (CC0)

    If you’ve ever run the same prompt twice and gotten word-for-word identical responses, or watched an AI assistant spiral into repetitive loops, you’ve seen temperature at work—or not working.

    Temperature is a parameter that controls how much randomness an AI model injects into its output. It’s not hidden deep in developer docs; most consumer AI tools expose it. But most solo operators never touch it, which means they’re stuck with whatever default the platform chose.

    Here’s how it works, when to adjust it, and one non-obvious way it breaks your workflow if you leave it on autopilot.

    What temperature actually controls

    When an AI model generates text, it doesn’t pick the single “best” next word. It assigns probabilities to thousands of candidates, then samples from that distribution.

    Temperature adjusts the shape of that distribution:

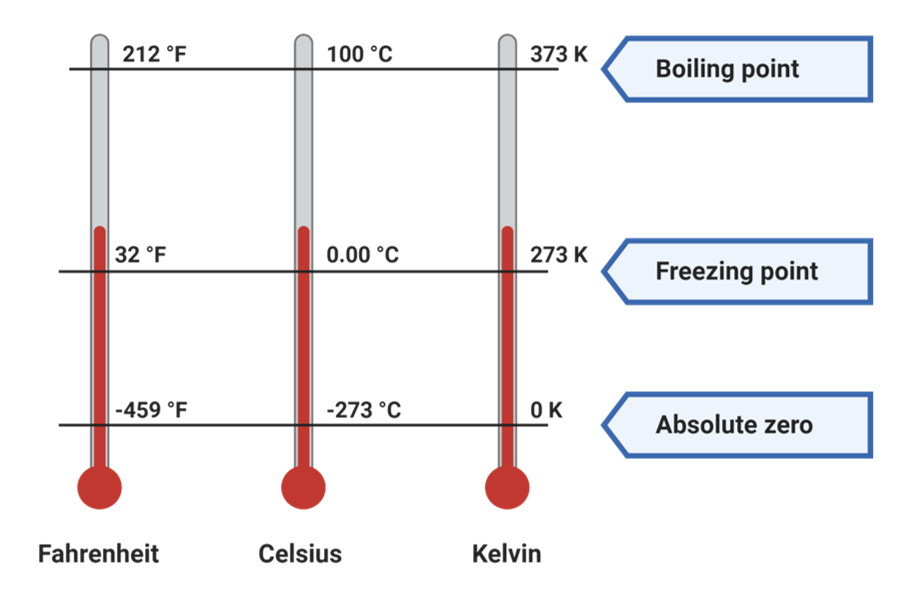
    • Temperature 0 (or close to it): the model always picks the highest-probability token. Output is deterministic. Run the same prompt ten times, you get ten identical responses.
    • Temperature 0.7–1.0: the model samples more widely. You get variety, creativity, and occasional surprises—some useful, some not.
    • Temperature above 1.5: the distribution flattens. Low-probability words get picked more often. Output becomes incoherent or tangential fast.

    Most platforms default to 0.7 or 1.0. Claude defaults to 1.0. OpenAI’s ChatGPT sits around 0.7 in the web interface. Google’s Gemini models vary by endpoint.

    That default is optimized for general chat. It’s not optimized for your use case.

    When to drop temperature to zero

    If you’re using AI to generate structured output—JSON schemas, CSV rows, code snippets, form letters, product descriptions from a template—you want deterministic results.

    Set temperature to 0. You’ll get the same output every time, which makes testing, debugging, and batch processing predictable. If the first result is wrong, the prompt is wrong. Fix the prompt, not the dice roll.

    Example: you’re generating meta descriptions for 200 blog posts. You write a prompt, test it on three posts, and it works. You run the batch overnight at temperature 0.7. In the morning, 180 are perfect and 20 are off-brand or too long. You can’t tell which prompt variation caused the problem, because the model sampled differently each time.

    Drop to temperature 0. Now every meta description follows the same logic. If one breaks, they all break the same way—and you can fix the root cause in one edit.

    When to raise temperature above default

    Brainstorming, headline variants, subject-line testing, social-post angles—anything where you want the model to surprise you benefits from higher temperature.

    Set it to 1.2 or 1.3. You’ll get weirder suggestions, some of which will be unusable. But the hit rate on novel ideas goes up. Run the same prompt five times and you’ll see real divergence, not just synonym swaps.

    One catch: higher temperature increases the chance of hallucination and off-topic drift. Don’t use it for factual research or anything that feeds directly into customer-facing copy without review.

    The non-obvious problem: mid-conversation drift

    Most AI chat interfaces don’t let you adjust temperature per message. The setting applies to the whole conversation thread.

    If you start a thread at temperature 1.0 to brainstorm blog topics, then shift gears and ask the model to write a structured outline, you’re still sampling at 1.0. The outline will vary every time you regenerate it, which makes it hard to iterate on structure without the content shifting under you.

    The fix: start a new conversation when you switch from exploratory mode to execution mode. Or use an API client or playground interface (OpenAI, Anthropic, and Google all offer them) where you can set temperature per request.

    For solo operators running prompt-based workflows—newsletter intros, product descriptions, SEO meta fields—this matters more than model size or context window. A smaller model at the right temperature will outperform a bigger one set to default.

    Check your tool’s settings. If you’re using Claude via the web interface, click the model dropdown and look for “temperature” or “sampling.” If you’re calling an API, it’s almost always exposed as a parameter. If you’re using a no-code AI tool like Zapier’s ChatGPT action or Make’s OpenAI module, temperature is in the advanced settings.

    Set it once per workflow type. You’ll spend less time regenerating and more time shipping.

    Want more breakdowns of the settings nobody explains? Subscribe to One Two Three Send—one operator-focused article every day, no fluff.

    Heads up — some links in this article are affiliate links. If you sign up through them, we may earn a small commission at no extra cost to you. We only recommend tools we use ourselves.
  • AI assistant token pricing: what you’re actually charged per request

    AI assistant token pricing: what you’re actually charged per request

    AI assistant token pricing: what you're actually charged per request
    Photo by Markus Winkler on Unsplash

    Most solo operators treat AI assistant pricing like a flat monthly subscription. You pay $20, you get unlimited ChatGPT Plus. Simple.

    But the moment you move to API access—Claude, GPT-4, Gemini, or any other model billed per token—the math changes completely. You’re no longer paying for access. You’re paying for every word you send and every word the model returns.

    If you’re building AI workflows, automating content generation, or running prompts at scale, understanding token pricing is the difference between a $15/month tool cost and a $400 surprise bill.

    How token pricing actually works

    Tokens aren’t words. They’re chunks of text—usually 3–4 characters, depending on the model’s tokenizer. The phrase “newsletter operators” is three tokens. A 500-word article might consume 650–750 tokens, depending on punctuation and structure.

    Every API call bills you twice: once for input tokens (your prompt and any context you include), and once for output tokens (the model’s response). Input is almost always cheaper—sometimes 10× cheaper—than output.

    As of October 2026, here’s what you’re paying per million tokens on the most common models:

    • GPT-4o: $2.50 input / $10.00 output
    • Claude 3.5 Sonnet: $3.00 input / $15.00 output
    • GPT-4o mini: $0.15 input / $0.60 output
    • Gemini 1.5 Flash: $0.075 input / $0.30 output

    If you’re generating a 1,000-token article with a 200-token prompt using GPT-4o, that’s $0.005 for input and $0.01 for output—about 1.5 cents per article. Run that 1,000 times a month and you’re at $15. Add debugging, retries, and context bloat, and you’re closer to $40.

    Where costs spike: context and retries

    Token costs compound fast when you’re including context. If you’re feeding the model your brand voice guide, three example posts, and a style sheet every time you generate a headline, you might be sending 2,000+ tokens of input for a 50-token output.

    That’s $0.005 in input and $0.0005 in output per request. The input is now 10× the cost of the result.

    Retries make it worse. Most automation tools—Zapier, Make, n8n—will re-run a failed API call at least once. If your prompt is malformed or the model times out, you’ve just doubled your token spend for zero usable output.

    The fix: strip unnecessary context. If you’re generating subject lines, you don’t need to include your entire content strategy doc. Summarize it into 100 tokens or cache it using the model’s context-caching feature (available in Claude and some OpenAI endpoints). Caching input tokens costs about 90% less on repeat calls.

    Choosing the right model for the job

    You don’t need GPT-4o or Claude 3.5 Sonnet for every task. If you’re summarizing reader replies, reformatting CSVs, or generating meta descriptions, a mini model works fine—and costs 10–20× less.

    Here’s a rough decision tree:

    • Use a flagship model (GPT-4o, Claude 3.5 Sonnet) for: long-form content generation, nuanced editing, complex reasoning, brand-voice matching.
    • Use a mini/flash model for: summarization, reformatting, extracting structured data, generating simple variants (subject lines, CTAs).
    • Use a local or open model (via Ollama, LM Studio) for: high-volume tasks where latency doesn’t matter and you want zero per-token cost.

    If you’re running 10,000+ requests a month, split your workload. Route simple tasks to Gemini Flash or GPT-4o mini, and reserve the expensive models for work that actually needs them.

    Track spend before it surprises you

    Every major AI provider offers usage dashboards. Set a monthly spending cap in OpenAI’s settings or Anthropic’s console. Most platforms let you set a hard limit—$50, $100, whatever fits your budget—and they’ll stop processing requests once you hit it.

    If you’re running prompts through Zapier or Make, add a step that logs token counts to a Google Sheet or Airtable. You’ll see exactly which automations are burning tokens and where to optimize.

    One operator I know was spending $80/month on Claude API calls to generate social posts. After logging token usage, he realized 60% of the cost came from a 1,200-token brand-voice primer he was sending with every request. He cached it, cut his bill to $28, and the output quality didn’t change.

    Want more breakdowns like this? Subscribe to One Two Three Send—we cover the tools, pricing, and workflows that actually matter for solo operators.

    Heads up — some links in this article are affiliate links. If you sign up through them, we may earn a small commission at no extra cost to you. We only recommend tools we use ourselves.
  • AI prompt version control: tracking what worked last month

    AI prompt version control: tracking what worked last month

    AI prompt version control: tracking what worked last month
    Photo by Alexander Sutton on Unsplash

    If you’re running prompts through Claude, ChatGPT, or any other AI assistant more than a few times a week, you’ve probably rewritten the same prompt four different ways in the last month—and forgotten which version actually gave you the output you wanted.

    Most solo operators treat prompts like scratch paper. You tweak, you run, you tweak again. If it works, great. If it doesn’t, you start over. But six weeks later, when you need that same task done again, you’re back to square one because you didn’t save the prompt that worked.

    Prompt version control isn’t about building a fancy system. It’s about keeping a simple log of what you changed, when, and why it mattered. Here’s how to do it without adding another tool to your stack.

    Why prompts drift faster than you think

    Unlike code, prompts don’t break loudly. They degrade quietly. You change one instruction, and the output shifts just enough that you don’t notice—until three iterations later, when the AI is giving you something completely different from what you originally wanted.

    Common drift triggers:

    • You add a constraint to fix one edge case, and it breaks the normal case.
    • You switch models (GPT-4 to Claude, or vice versa) and forget to adjust tone instructions.
    • You copy a prompt from a Slack thread and lose the context that made it work.
    • You refine phrasing for clarity, but the AI interprets the new wording differently.

    Without version control, you can’t roll back. You just keep tweaking forward, hoping you stumble back onto something that works.

    The simplest version control setup

    You don’t need Git. You don’t need a prompt management SaaS. You need a text file with dates and a notes field.

    Create a file called prompts.txt or ai-log.md in your notes app, Dropbox, or Google Drive. Every time you land on a prompt that works well enough to reuse, paste it in with three pieces of metadata:

    • Date: when you last used or updated it.
    • Task name: a short label like “newsletter intro rewrite” or “SEO meta description generator.”
    • What changed: one sentence on what you tweaked and why.

    Example entry:

    2026-10-15 | Newsletter intro rewrite
    Prompt: “Rewrite the following intro in 2–3 sentences. Use active voice. Open with a specific detail, not a general statement. Audience: solo online-business operators.”
    Changed: removed “engaging” from instructions—it was making tone too informal.

    That’s it. No tagging system. No nested folders. Just a running log you can Cmd+F when you need to find the version that worked three months ago.

    When to snapshot a prompt

    You don’t need to log every single run. Snapshot a prompt when:

    • You use it successfully for the first time and plan to reuse it.
    • You make a meaningful change that improves output quality.
    • You switch models or tools and need to adjust instructions.
    • Someone on your team asks how you got a specific result.

    If you’re running 10+ prompts a day, you’ll probably log 2–3 per week. That’s enough to build a reusable library without turning it into a chore.

    A shareable library beats a private one

    If you work with a VA, contractor, or co-founder, move your prompt log into a shared doc. Google Docs, Notion, or a private GitHub gist all work.

    The benefit isn’t just collaboration—it’s accountability. When someone else might read your prompt log, you write better notes. You explain why you changed something instead of just pasting a new version. That clarity helps future-you more than anyone else.

    For teams using Claude heavily, consider keeping a dedicated #prompts Slack channel where anyone can drop a working prompt with a sentence of context. It’s searchable, timestamped, and doesn’t require anyone to remember to update a doc.

    Track results, not just prompts

    A prompt log gets more useful when you add one line about what happened after you ran it. Not a full analysis—just a quick note.

    • “Used for 8 newsletter intros this month, 6 needed minor edits.”
    • “Switched to this version after the old one started overusing em dashes.”
    • “Output quality dropped when I moved from GPT-4 to 3.5—reverted.”

    This turns your log from a static archive into a decision-making tool. When you’re deciding whether to tweak a prompt or leave it alone, you can look back and see whether your last round of changes actually improved anything.

    Most solo operators don’t need enterprise prompt-management software. You need a text file, a habit of pasting what works, and enough discipline to write one sentence about why it mattered. Start today with a single file and three logged prompts. By the end of the month, you’ll stop rewriting from scratch.

    What’s one prompt you’ve rewritten five times this year? Reply and let us know—we might feature your setup in a future issue. And if you’re not subscribed yet, join the list for more operator-to-operator breakdowns like this every week.

    Heads up — some links in this article are affiliate links. If you sign up through them, we may earn a small commission at no extra cost to you. We only recommend tools we use ourselves.
  • AI model context windows expire mid-task—here’s when

    AI model context windows expire mid-task—here’s when

    AI model context windows expire mid-task—here's when
    Photo: Dietmar Rabich via Wikimedia Commons (CC BY-SA 4.0)

    You’re halfway through drafting a series of social posts with an AI assistant. You step away to take a call, answer some emails, grab lunch. When you return and ask it to continue, the tone shifts. It forgets the audience you described. The product details you fed it earlier are gone.

    This isn’t a bug. It’s how AI context windows work—and most operators don’t realize their session has an expiration timer running in the background.

    What actually expires

    When you interact with an AI model through a chat interface—Claude, ChatGPT, Gemini, or an embedded assistant in a writing tool—the system maintains a “context window.” That’s the running record of everything you and the model have said in the current conversation.

    But context isn’t free. It costs tokens to store, retrieve, and process. So platforms set limits on how long that context persists when you’re inactive.

    Most tools reset after 30 to 90 minutes of inactivity. Claude‘s web interface, for example, typically expires sessions around 60 minutes. ChatGPT’s free tier is closer to 30. Some API-based tools let you configure the timeout, but defaults rarely exceed two hours.

    What gets lost:

    • Previous instructions you gave about tone, audience, or format
    • Background data you pasted in—product specs, customer quotes, content briefs
    • Refinements you made over multiple turns
    • The thread of logic that led to the current draft

    When the session expires, the model starts fresh. It won’t remember that you asked it to write for a technical audience, avoid jargon, or reference the pricing table you shared earlier.

    Why this matters for solo operators

    If you’re using AI to draft a newsletter, write ad copy, or generate a content calendar, you’re rarely doing it in one uninterrupted sitting. You stop to check a source, review a past campaign, or handle a customer question.

    That 10-minute detour might not feel long, but if you’ve been idle for 45 minutes total across multiple breaks, you’re approaching the cutoff. The next time you return, the assistant has no memory of your earlier work.

    This is especially painful when you’re iterating. You spend 20 minutes training the model on your brand voice, then walk away. When you come back to generate the next batch, you’re starting over.

    How to work around expiration

    The simplest fix: copy your prompt and the model’s output into a text file before you step away. If the session expires, you can paste it back in as context for the next request.

    For longer projects, build a reusable prompt template that includes all your standing instructions—brand voice, audience details, formatting rules. Store it in a note-taking tool or a dedicated prompt library. Each time you start a new session, paste it in as the first message.

    If you’re using an API-based tool (like Claude via API or OpenAI’s GPT models in a custom workflow), check whether the platform supports session persistence or custom timeout settings. Some let you extend the window to several hours, though you’ll pay more in token costs.

    Another tactic: send a short message every 20–30 minutes to keep the session alive. A simple “continue” or “hold that thought” resets the inactivity clock. This works if you’re actively multitasking but not if you’ve genuinely stepped away.

    When to let it expire

    Not every conversation needs to persist. If you’re using AI for one-off tasks—rewriting a single headline, generating a quick email reply, brainstorming a post idea—letting the context expire is fine. You don’t need the model to remember what you asked it an hour ago.

    But if you’re building something over multiple turns—drafting a multi-part email sequence, developing a content strategy, refining a landing page—treat the context window like unsaved work. Don’t assume it’ll be there when you return.

    Most AI tools don’t warn you when expiration is approaching. The session just ends. So if you’re planning to step away for more than 15 minutes, save your work externally. Copy the thread, export the draft, or paste key instructions into a doc.

    Context windows are cheap until they disappear. Plan accordingly.

    Want more breakdowns like this? Subscribe to One Two Three Send for weekly operator-focused takes on the tools and tactics that actually matter.

    Heads up — some links in this article are affiliate links. If you sign up through them, we may earn a small commission at no extra cost to you. We only recommend tools we use ourselves.
  • AI prompt libraries: should you build yours or borrow someone else’s?

    AI prompt libraries: should you build yours or borrow someone else’s?

    AI prompt libraries: should you build yours or borrow someone else's?
    Photo: Ginny from USA via Wikimedia Commons (CC BY-SA 2.0)

    Every few weeks, someone launches a new prompt library. A Notion doc, an Airtable base, a GitHub repo, a paid membership site—all promising to save you hours by giving you ready-made prompts for content creation, research, email drafts, and social posts.

    The pitch is simple: stop reinventing the wheel. Copy, paste, tweak, done.

    But after a year of watching solo operators toggle between borrowed prompts and their own scratch files, a pattern emerges: the people who get the most value from AI aren’t the ones with the biggest prompt libraries. They’re the ones who know exactly when to build and when to borrow.

    Borrowed prompts work when the task is generic

    If you’re summarizing a podcast transcript, drafting a cold outreach email, or turning bullet points into a blog outline, a borrowed prompt will get you 80% of the way there. The task is common enough that someone else has already figured out the structure, tone markers, and output format.

    Most public prompt libraries excel at these repeatable, low-context tasks. You plug in your variable (the transcript, the recipient name, the bullet list), and the AI returns something usable. You might tweak a sentence or two, but you’re not rewriting the whole thing.

    Borrowed prompts also shine when you’re learning a new AI tool. Seeing how someone else structures a multi-step prompt—where they place constraints, how they handle tone, when they ask for numbered lists versus paragraphs—teaches you the grammar of the tool faster than trial and error.

    But borrowed prompts fail the moment your task requires domain knowledge, brand voice, or a non-standard output format.

    Built prompts win when specificity matters

    If you run a finance newsletter and need to explain a Fed policy change in 200 words with no jargon, a generic “explain this news story” prompt won’t cut it. You need constraints the original author never considered: your audience’s literacy level, your editorial style, the three concepts you always define inline, the two you never mention.

    That’s when building your own prompt library pays off. You’re not writing prompts from scratch every time—you’re maintaining a small set of highly-tuned templates that reflect how your business actually works.

    One operator I talked to keeps 11 prompts in a text file. That’s it. Each one is 150–300 words long, with placeholders for the variable parts (topic, audience, length). She’s revised them over six months, adding constraints every time the output missed the mark. Now she gets usable drafts in one shot, 90% of the time.

    Her library isn’t shareable. It wouldn’t help you. But it’s worth more to her than any $49 prompt pack, because it encodes her editorial voice and her readers’ expectations.

    The hybrid approach most operators settle on

    Most people end up with a two-tier system: a handful of borrowed prompts for generic tasks (summarization, list generation, basic research), and a small set of custom prompts for the work that defines their business.

    The borrowed prompts live in a bookmarks folder or a Notion page someone else made. You don’t maintain them. If they stop working, you swap them out.

    The custom prompts live in a text file, a note in your task manager, or a dedicated doc. You version them. You test changes. You treat them like any other business asset.

    This split matters because it changes how you spend your time. You’re not trying to build a comprehensive prompt library—you’re identifying the 5–10 tasks where a custom prompt saves you an hour a week, and you’re optimizing those.

    Everything else? Use someone else’s work.

    When to stop tweaking and just write it yourself

    There’s a point where prompt engineering costs more time than doing the task manually. If you’ve spent 30 minutes trying to get Claude to format a comparison table the way you want it, and you could’ve built the table in 15 minutes, you’ve crossed that line.

    The best operators I’ve seen treat prompts like automation: you build it when the task is frequent enough and predictable enough that the upfront cost pays back in a month. If it’s a one-off, or if the output requirements change every time, skip the prompt library entirely.

    One useful heuristic: if you can’t describe the task in three sentences without saying “it depends,” don’t build a prompt for it yet. Wait until you’ve done it manually five times and the pattern is obvious.

    Then—and only then—write the prompt, test it twice, and save it.

    Want more like this? Subscribe to One Two Three Send for weekly breakdowns of the tools and tactics that actually matter for solo operators.

    Heads up — some links in this article are affiliate links. If you sign up through them, we may earn a small commission at no extra cost to you. We only recommend tools we use ourselves.